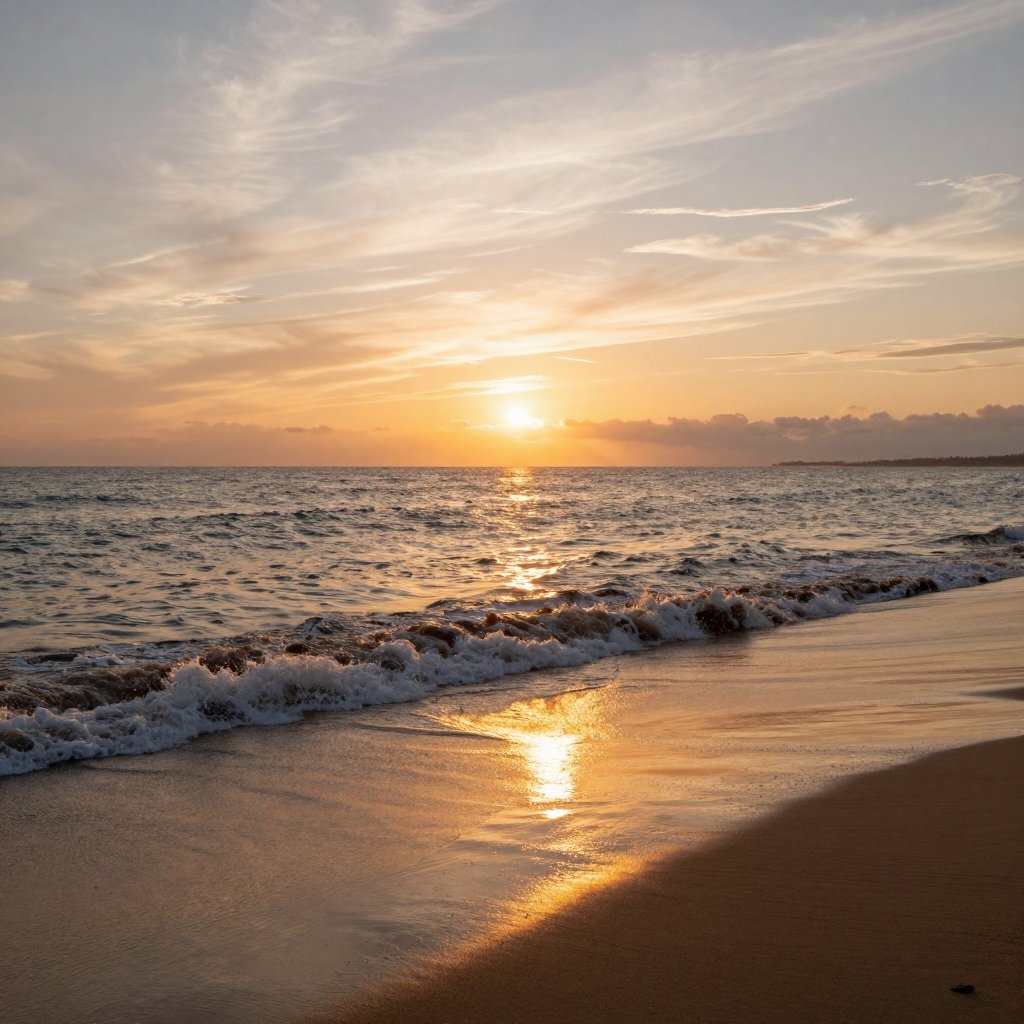
Generate an image of a beach at sunset with waves gently crashing on the shore.
Unified multimodal large language models (MLLMs) and multi-agent systems have advanced visual generation. However, three limitations remain. (1) Existing methods often distill task-specific experience with limited generalizability. (2) Reflection is often deferred until task completion. (3) Knowledge is often acquired only in response to downstream task demands. To address these limitations, we introduce OmniHarness, a framework for generalizable visual generation via symbolic policy learning. OmniHarness abstracts verified executions into symbolic policies for visual generation task families, capturing shared procedures and applicability conditions while removing instance-specific inputs. The harness instantiates, adapts, and composes these policies for new tasks. Intermediate verification guides refinement and failure recovery during execution. Through self-directed inquiry, OmniHarness autonomously generates and executes practice tasks near its capability limits before downstream objectives are specified. Execution feedback continually refines the policies while model parameters remain fixed. Experiments across six benchmarks, three MLLM backbones, and three visual agent frameworks demonstrate strong performance and continual capability expansion. On ComfyBench's Creative tasks, OmniHarness achieves a 95.0% resolve rate, exceeding the strongest baseline by 27.5 percentage points. Frozen policy snapshots improve existing visual agent systems through plug-and-play reuse.
Generate an image of a beach at sunset with waves gently crashing on the shore.
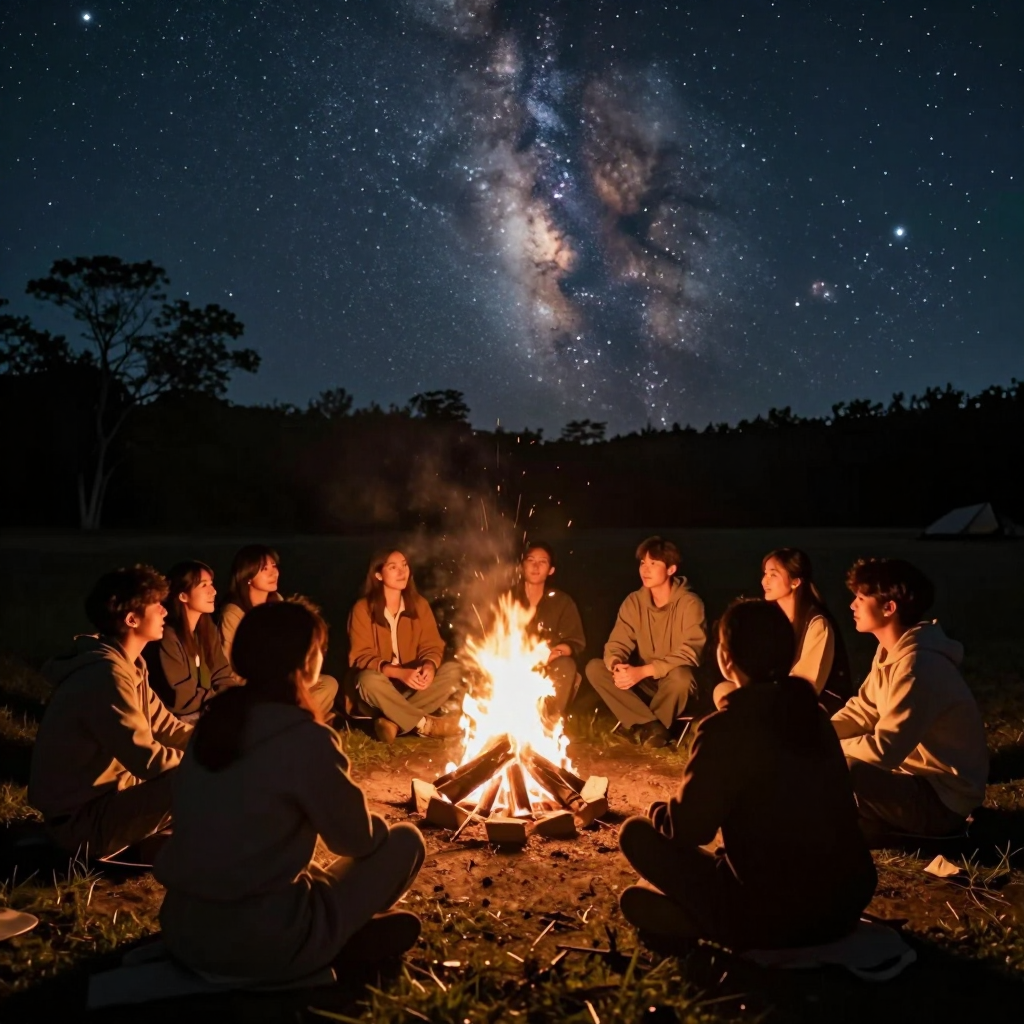
Generate an image of people sitting around a campfire under a starry night sky.
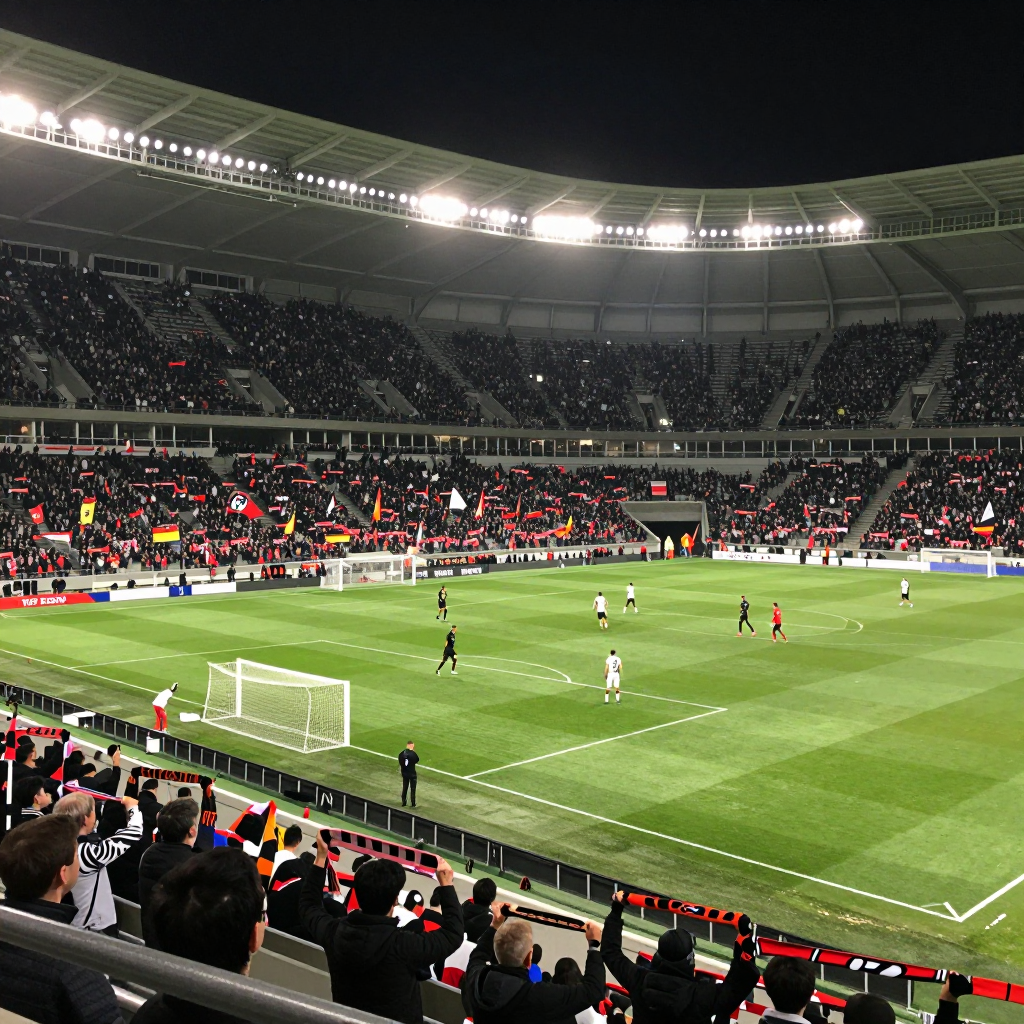
Generate an image of a soccer stadium filled with cheering fans during a match.
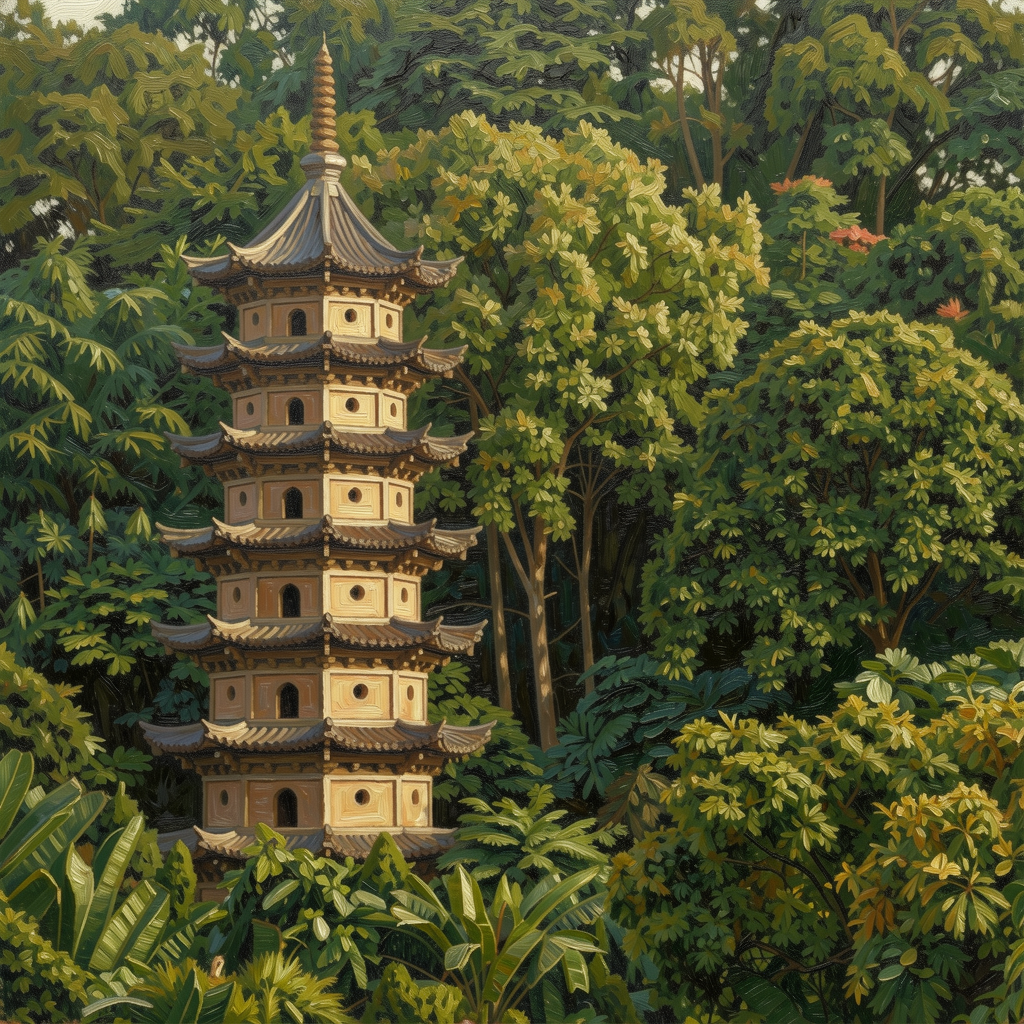
Generate an image of a pagoda in a quite forest. The pagoda should be placed in the left half of the image, with trees filling other areas.
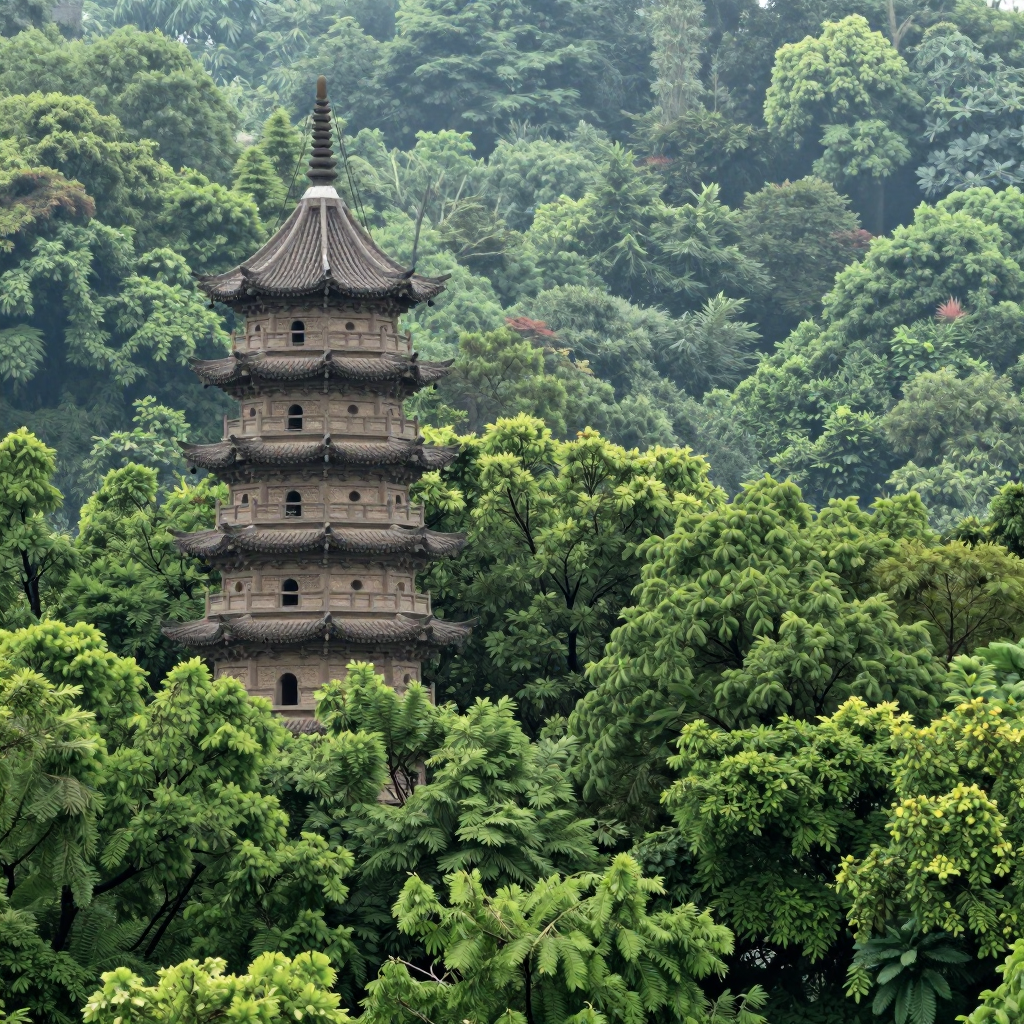
First generate an image of a pagoda in a quiet forest. The pagoda should be placed in the left half of the image, with trees filling other areas. Then convert the image into a painting with oil style.
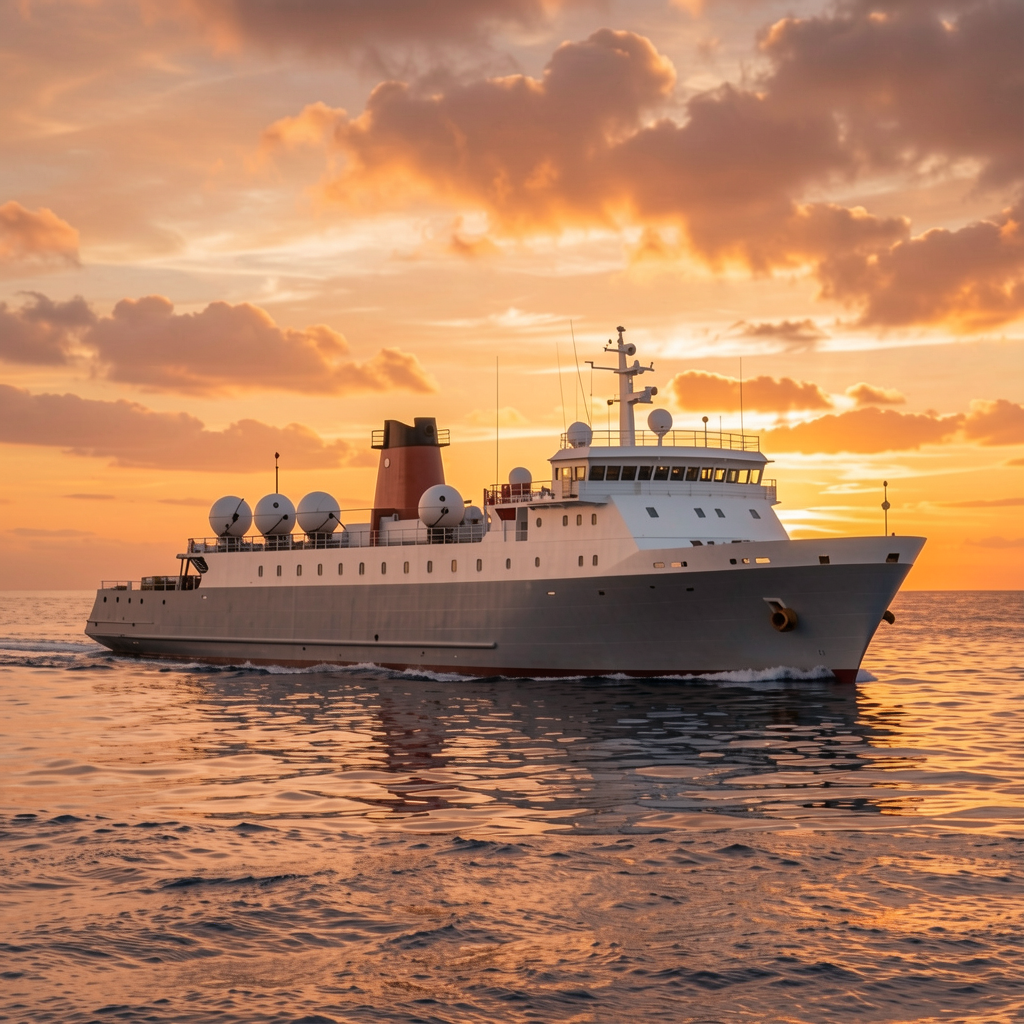
First generate an image of a ship floating in the sea. Then replace the background with a sunset sky.
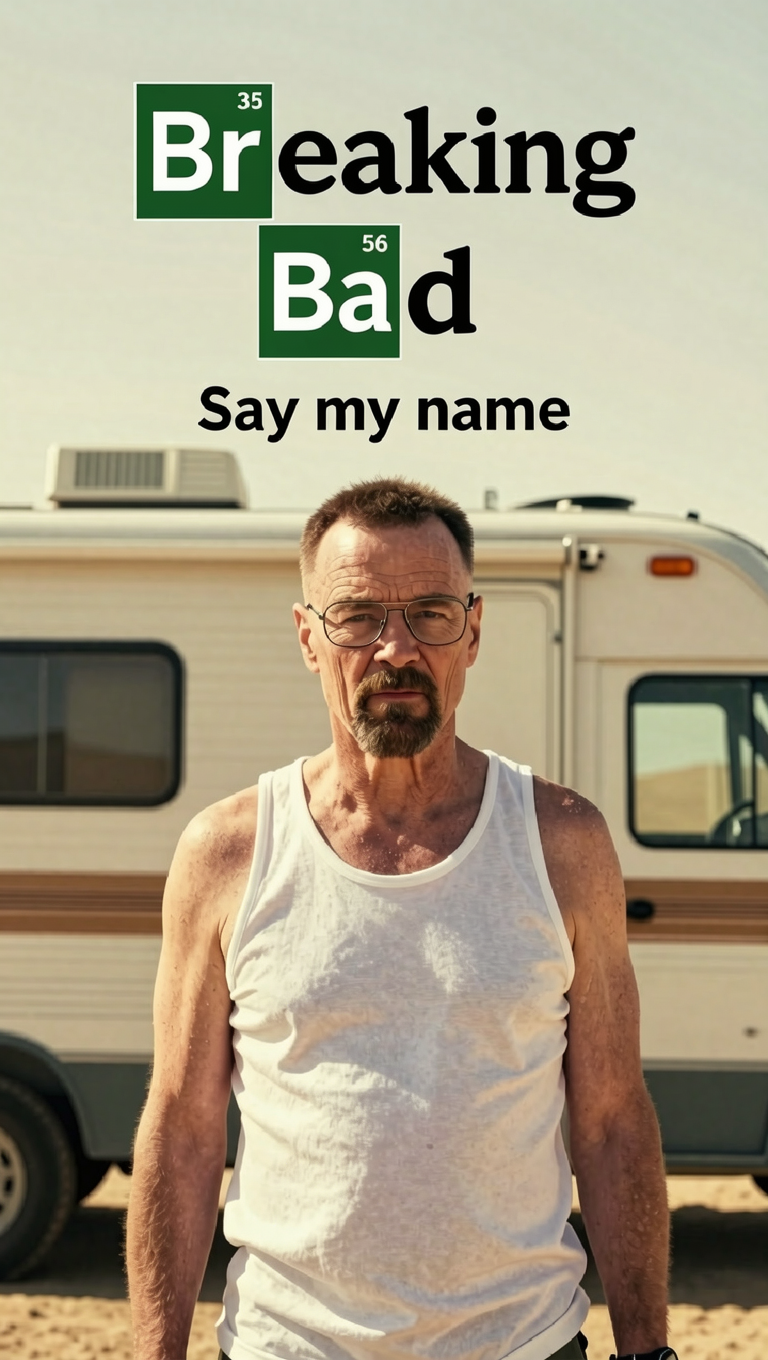
Generate a poster for a series named "Breaking Bad". The result should be a vertical image of the main character, Walter White, wearing a white vest with a serious expression, standing in front of a motorhome in the desert. The title "Breaking Bad" should be displayed in the top center of the image, followed by the tagline "Say my name".
Generate an image of a comic strip with four panels. The first panel should show a man waking up in bed, the second panel should show him looking at his smartphone, the third panel should show the smartphone displaying that it is Sunday, and the fourth panel should show the man continue to lie in bed.

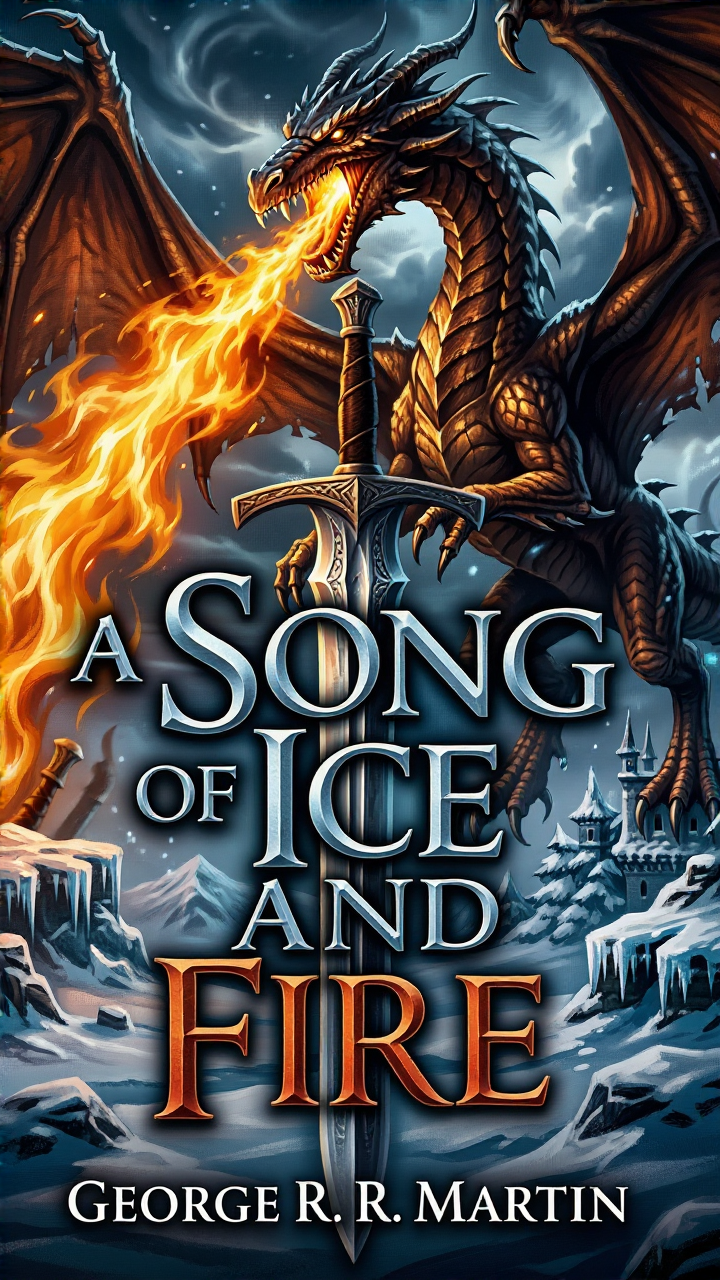
Design a book cover for a novel titled "A Song of Ice and Fire". The cover should feature a dragon breathing fire, a snowy landscape, and a sword. The title of the book together with the author's name "George R. R. Martin" should be displayed prominently on the cover.
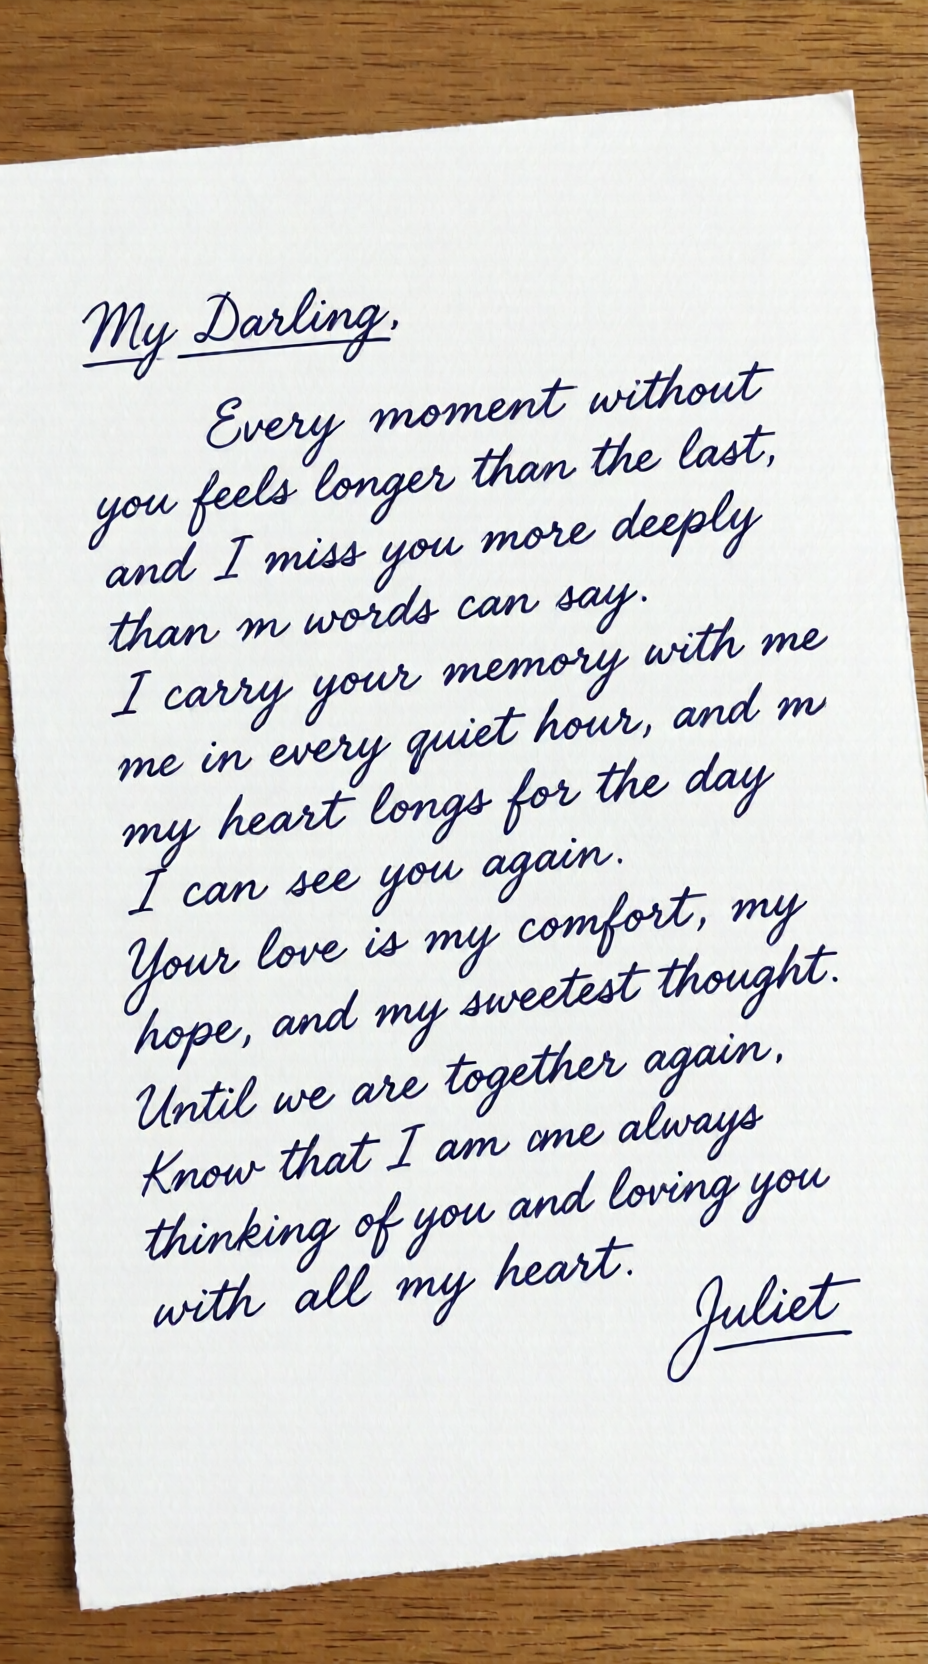
Generate an image of a handwritten letter on a piece of paper. The letter should be addressed to "My Darling" and signed with the name "Juliet". The content of the letter should express love and longing.
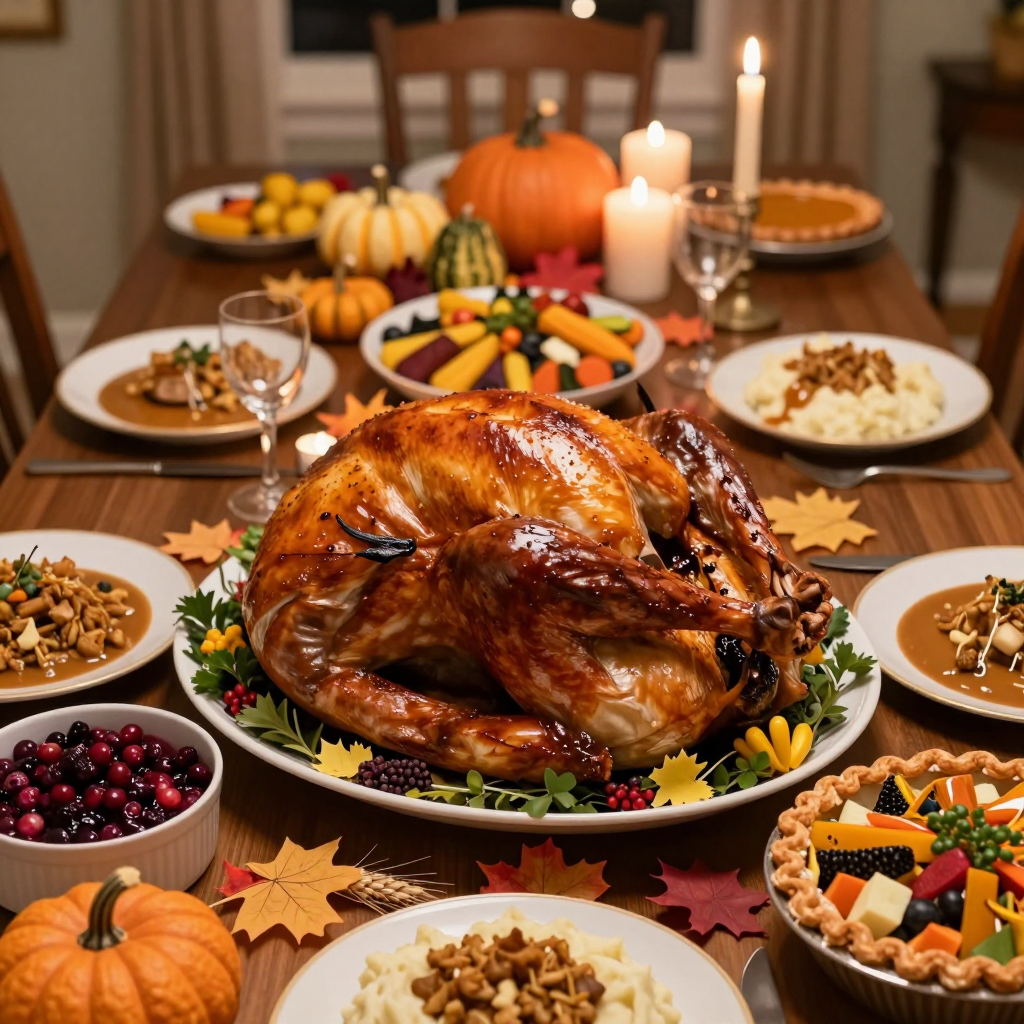
An autumnal harvest celebration in North America, where a large fowl takes center stage on the dining table
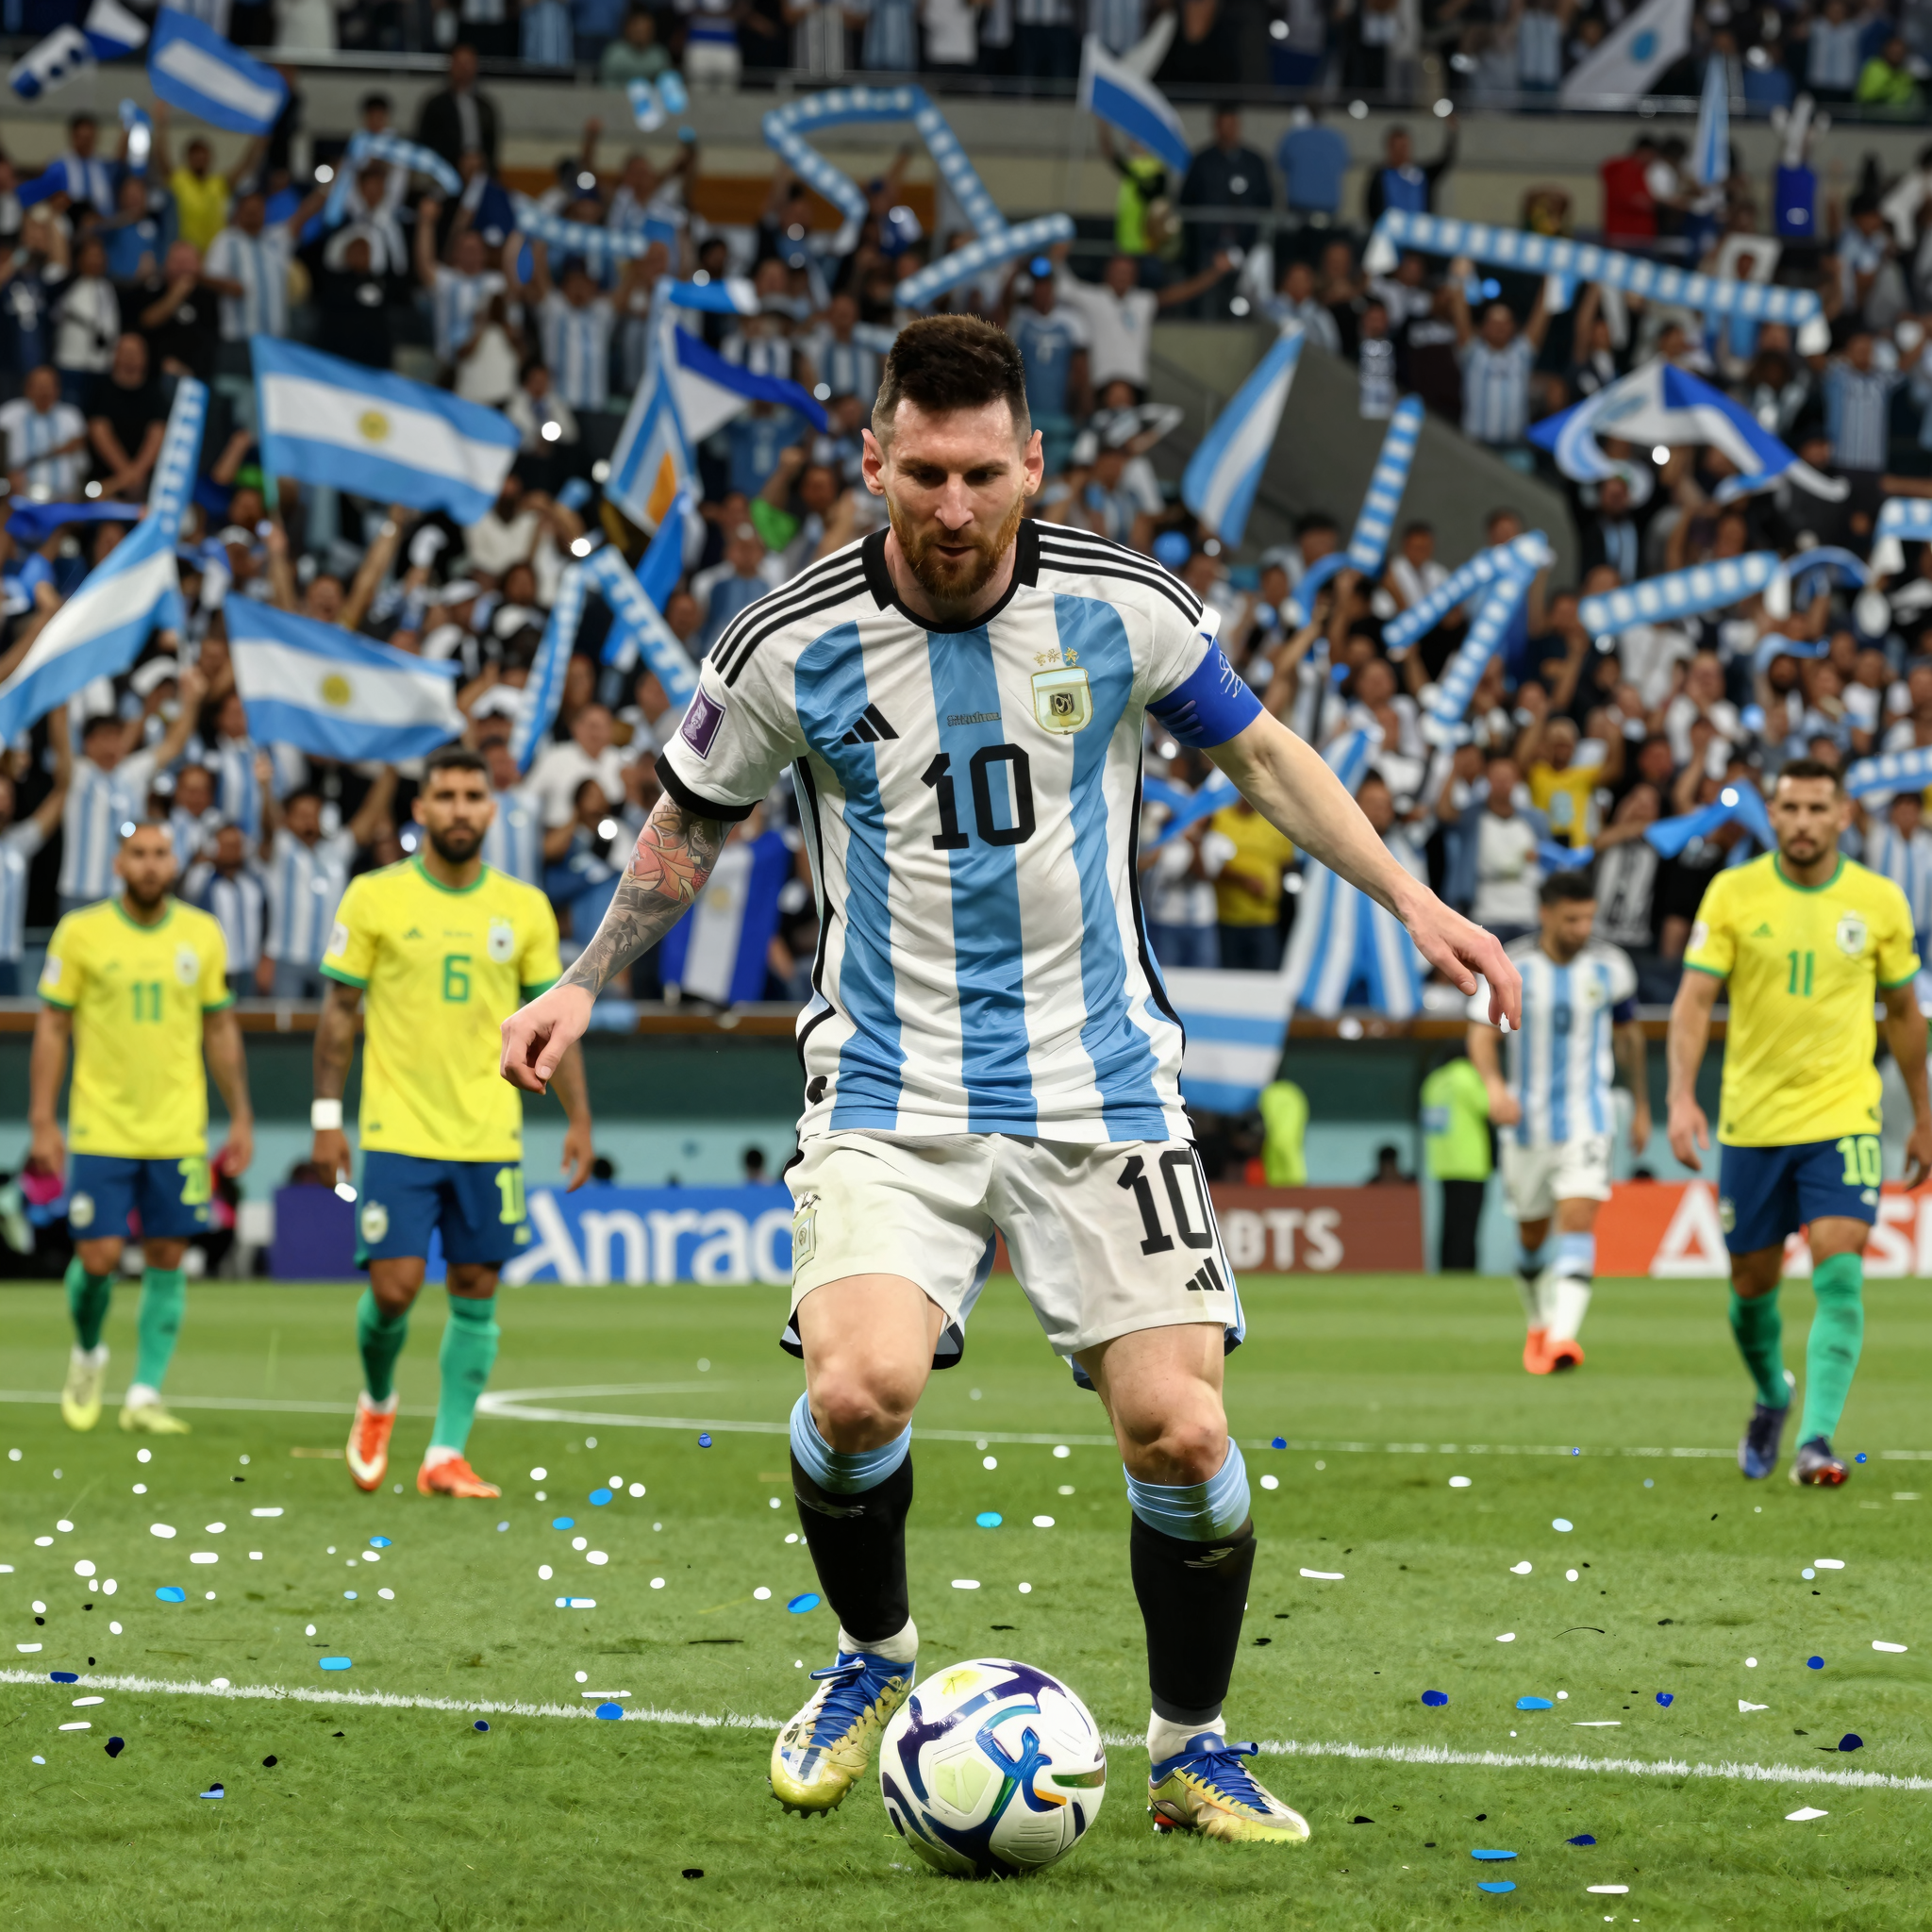
A sport that ignites national fervor in Argentina, often associated with legendary players and historic rivalries
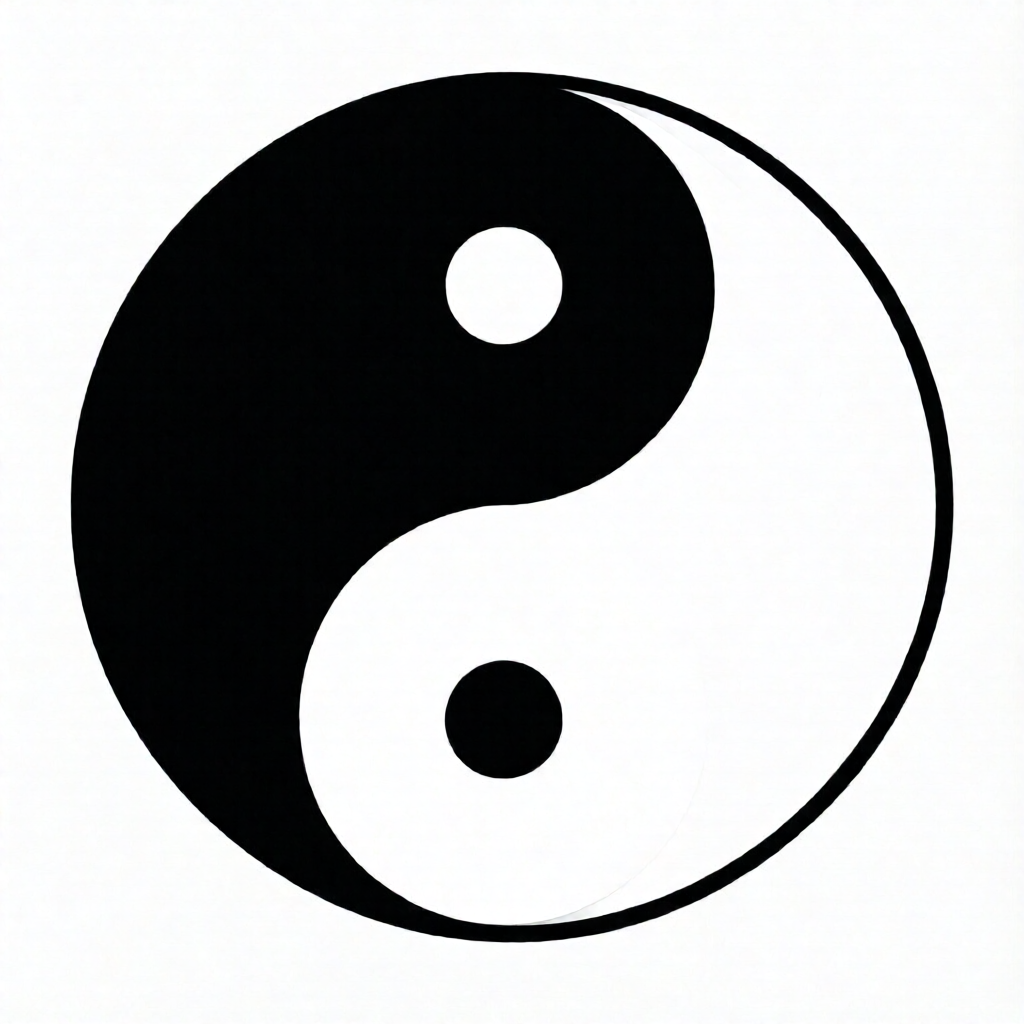
An image of a circular emblem representing balance and harmony in Taoist philosophy
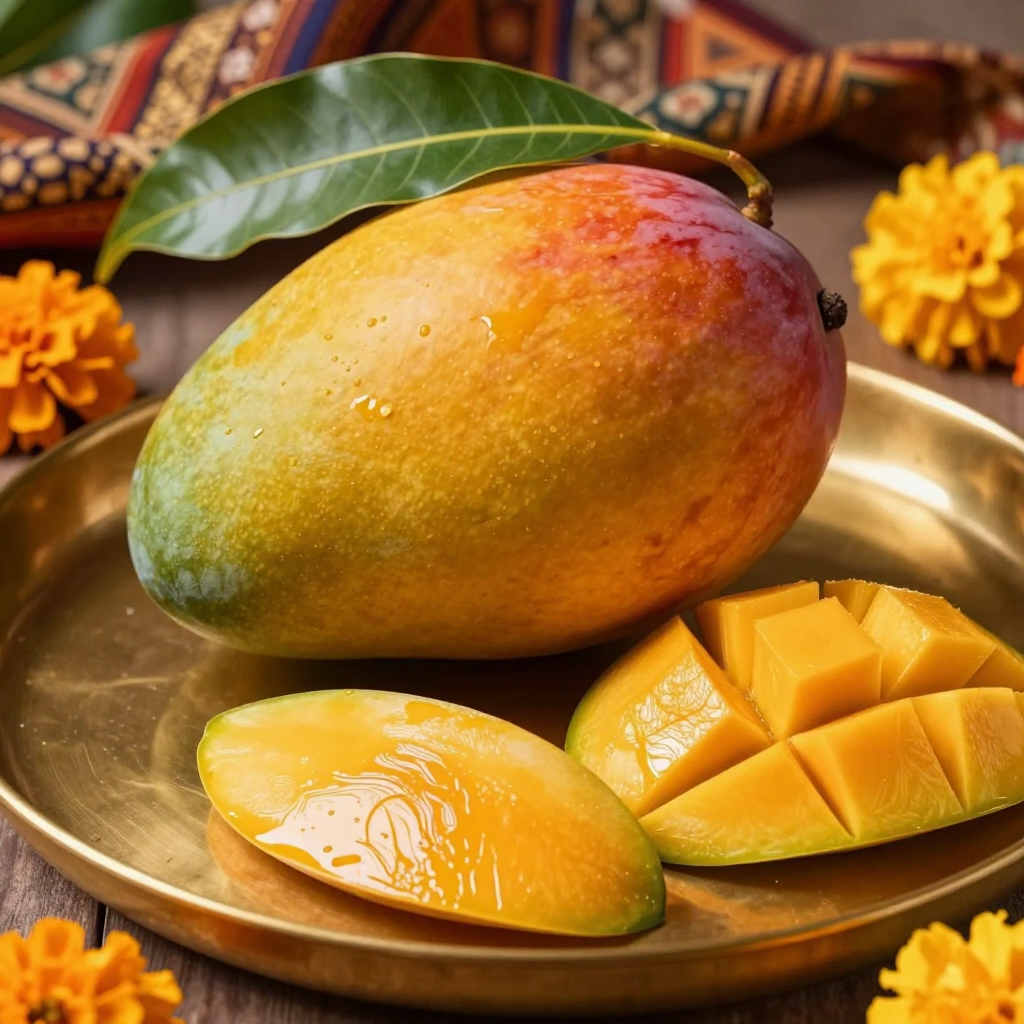
A beloved fruit in India, known as the 'king of fruits,' cherished for its rich flavor and cultural significance
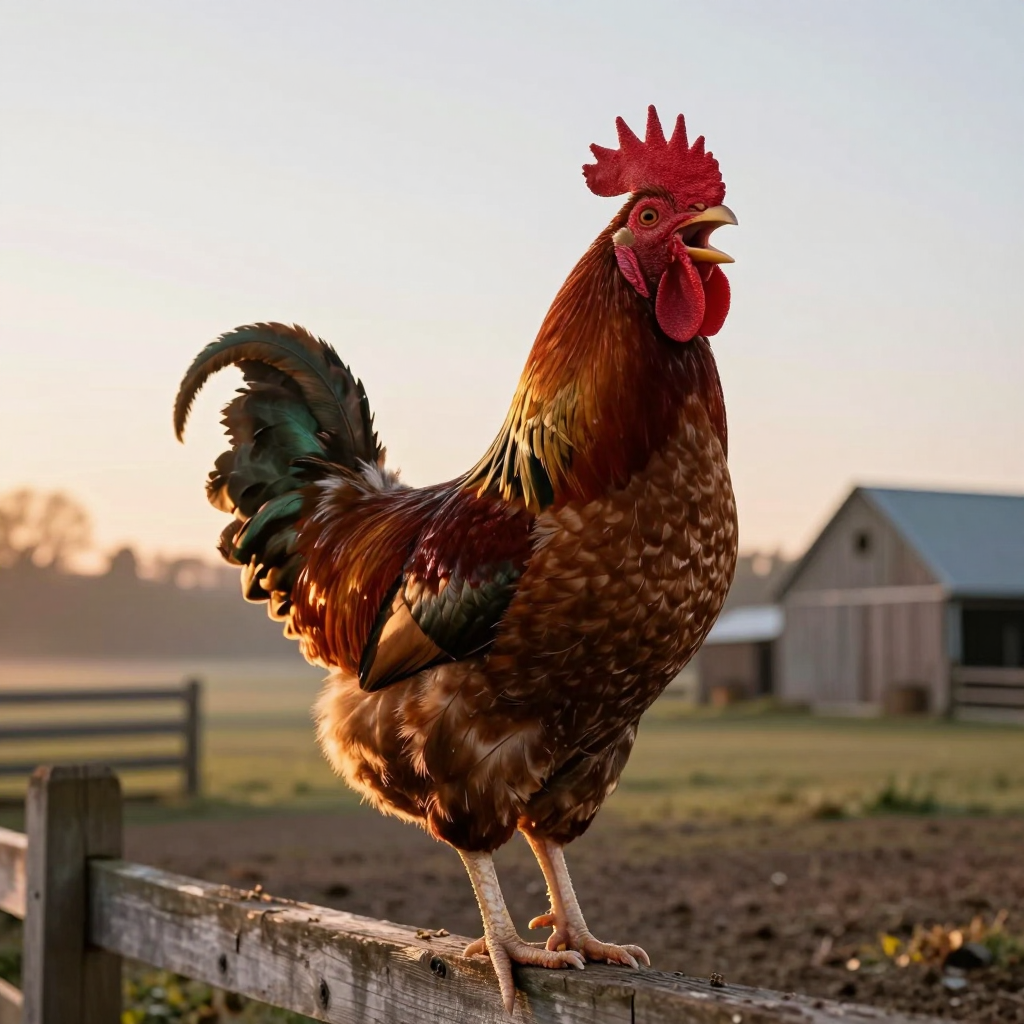
The animal that crows in the morning
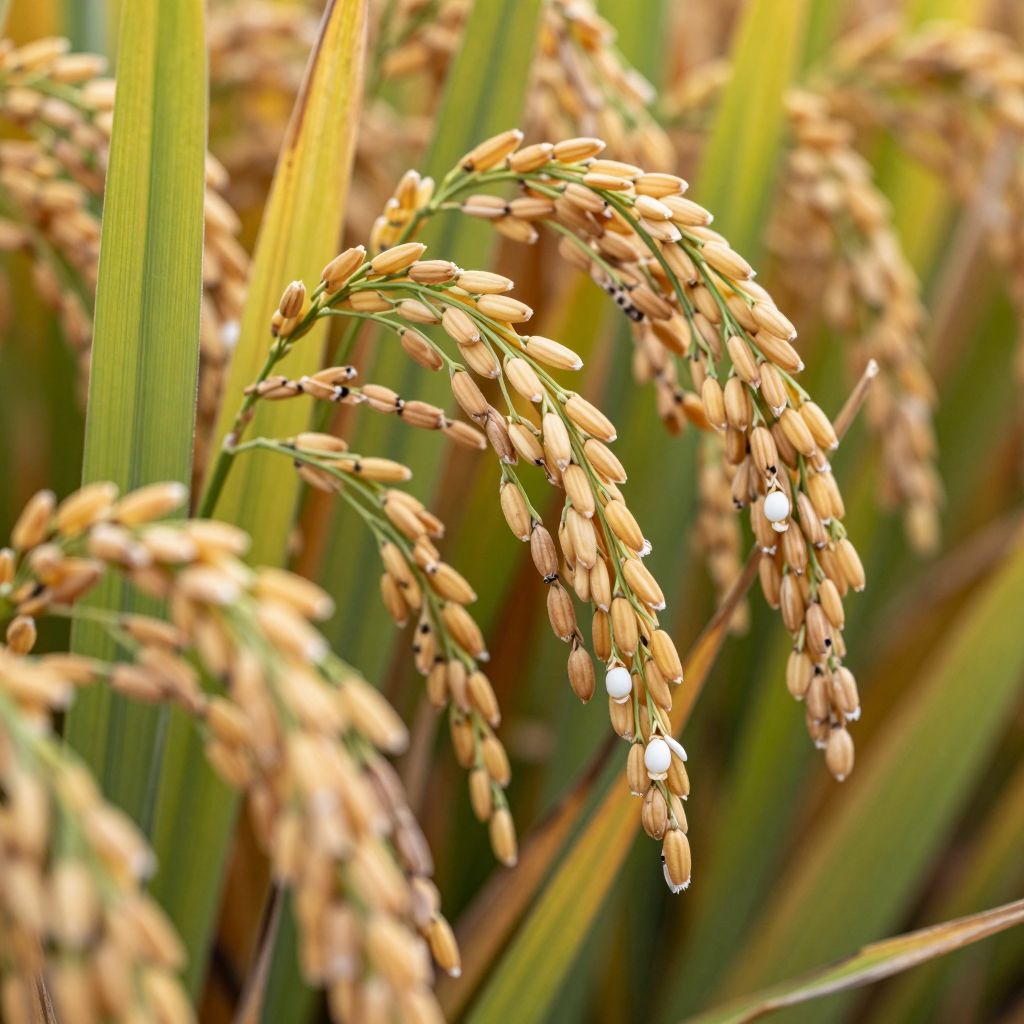
The grain that rice is derived from
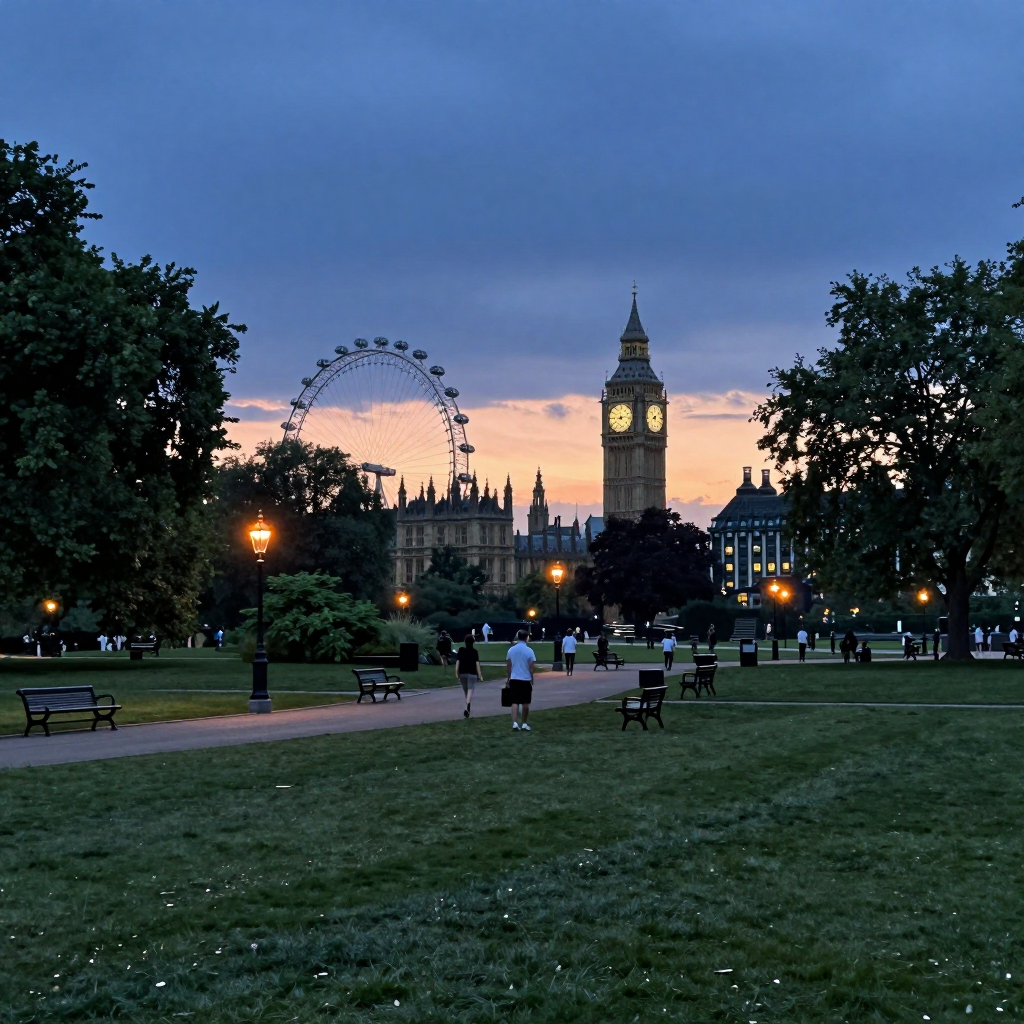
A park in London at 10 PM during the summer solstice
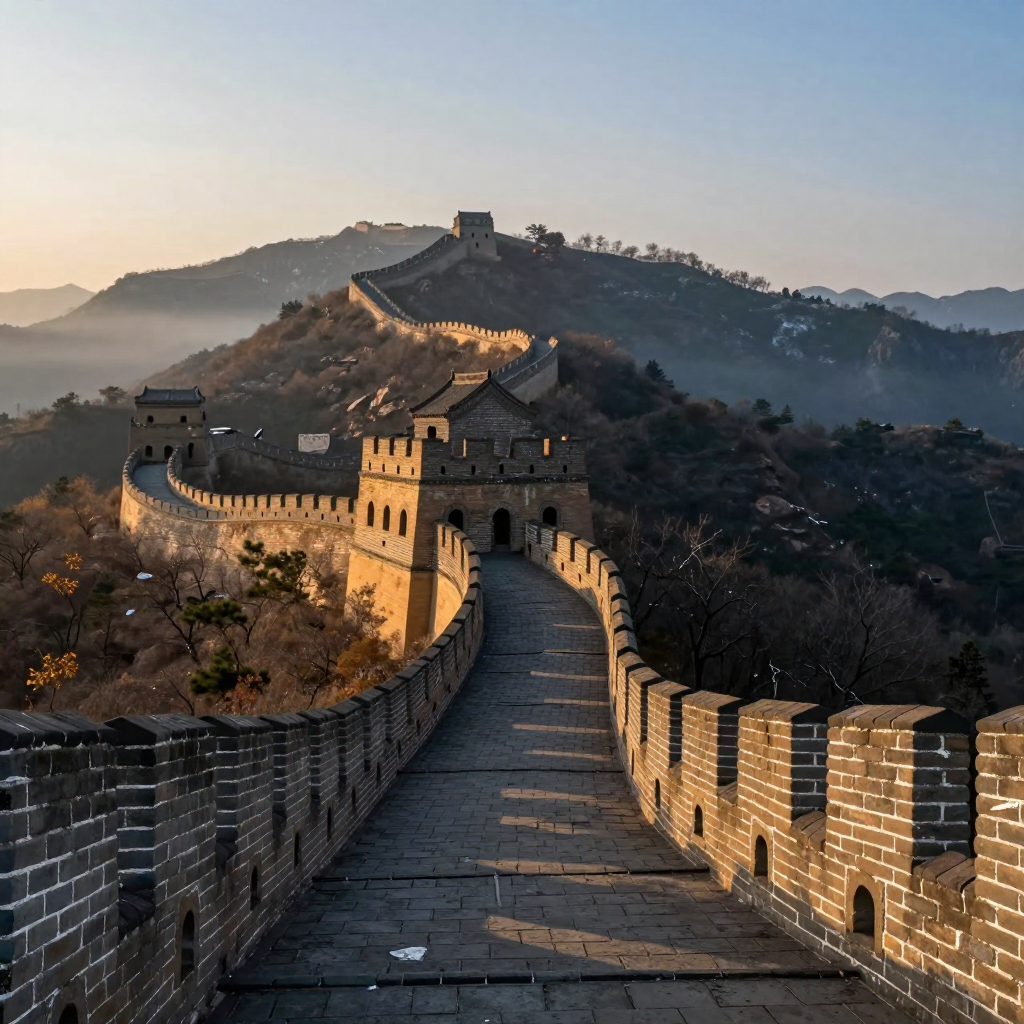
The Great Wall of China when it's 3 PM in Los Angeles
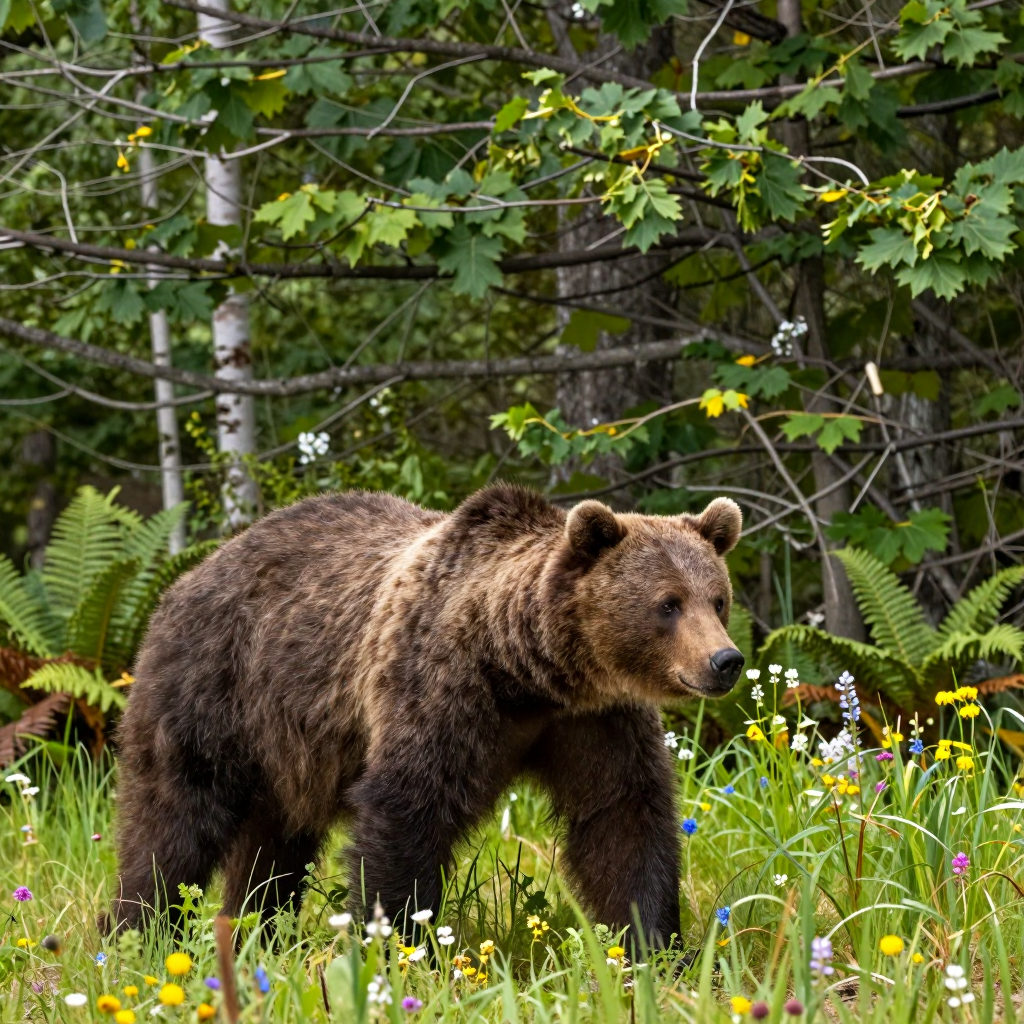
A bear during summer.
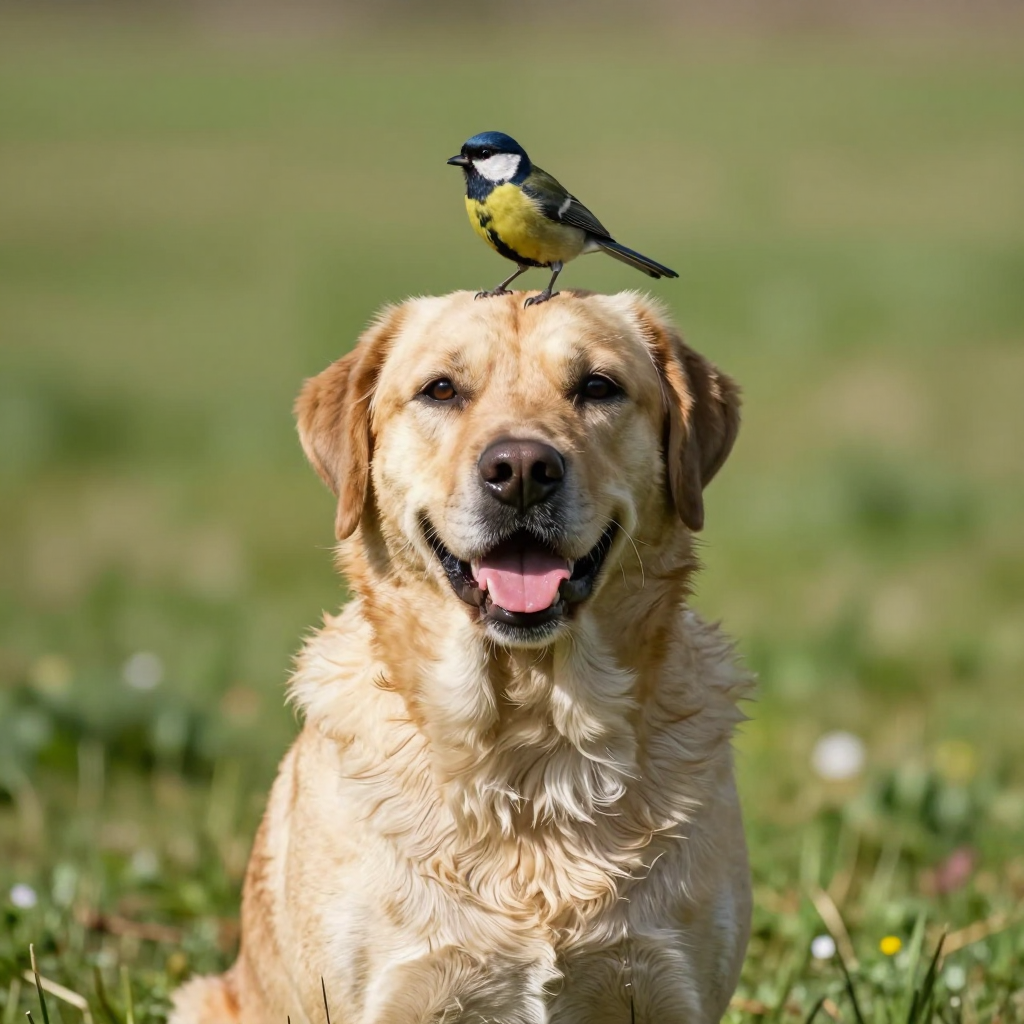
Generate an image of a bird and a dog, with the smaller animal on top and the larger below
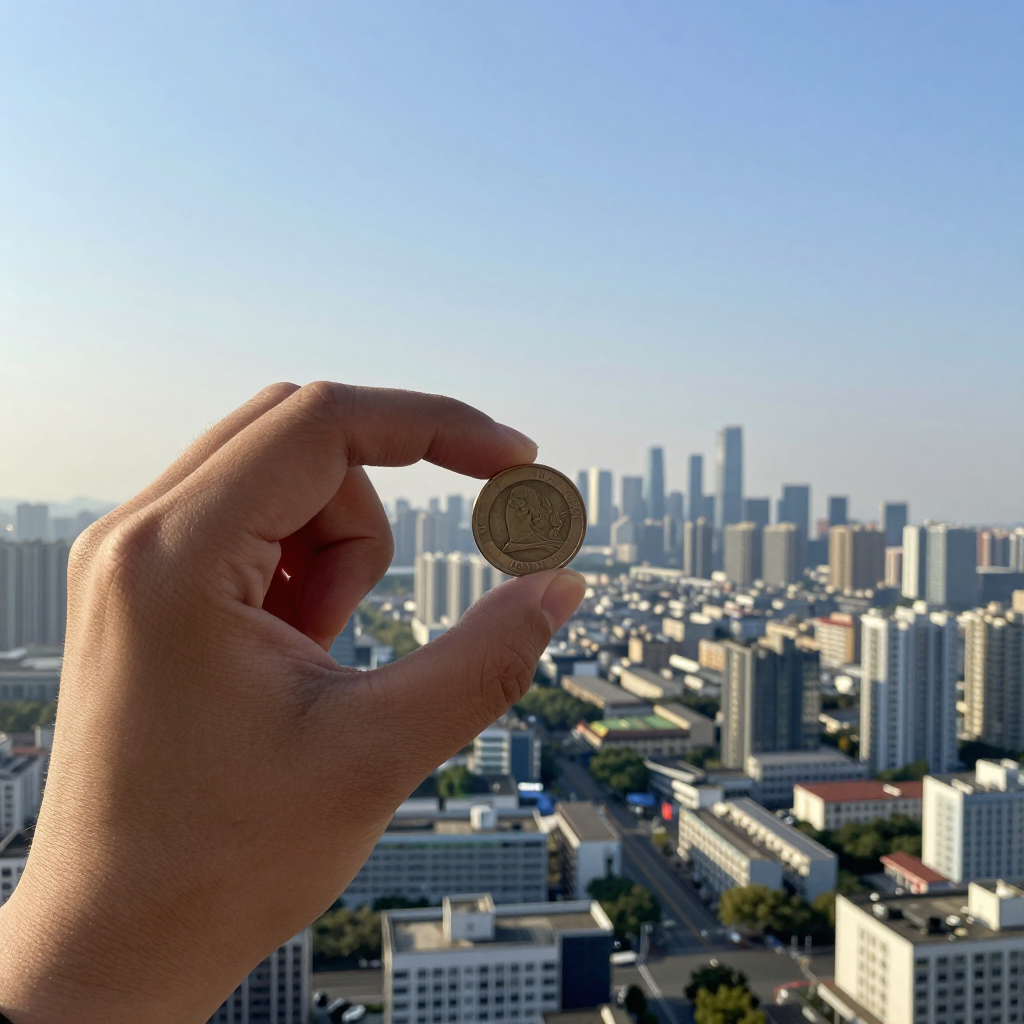
A hand holding a small coin in the immediate foreground, and a distant cityscape that seems very far away on the horizon
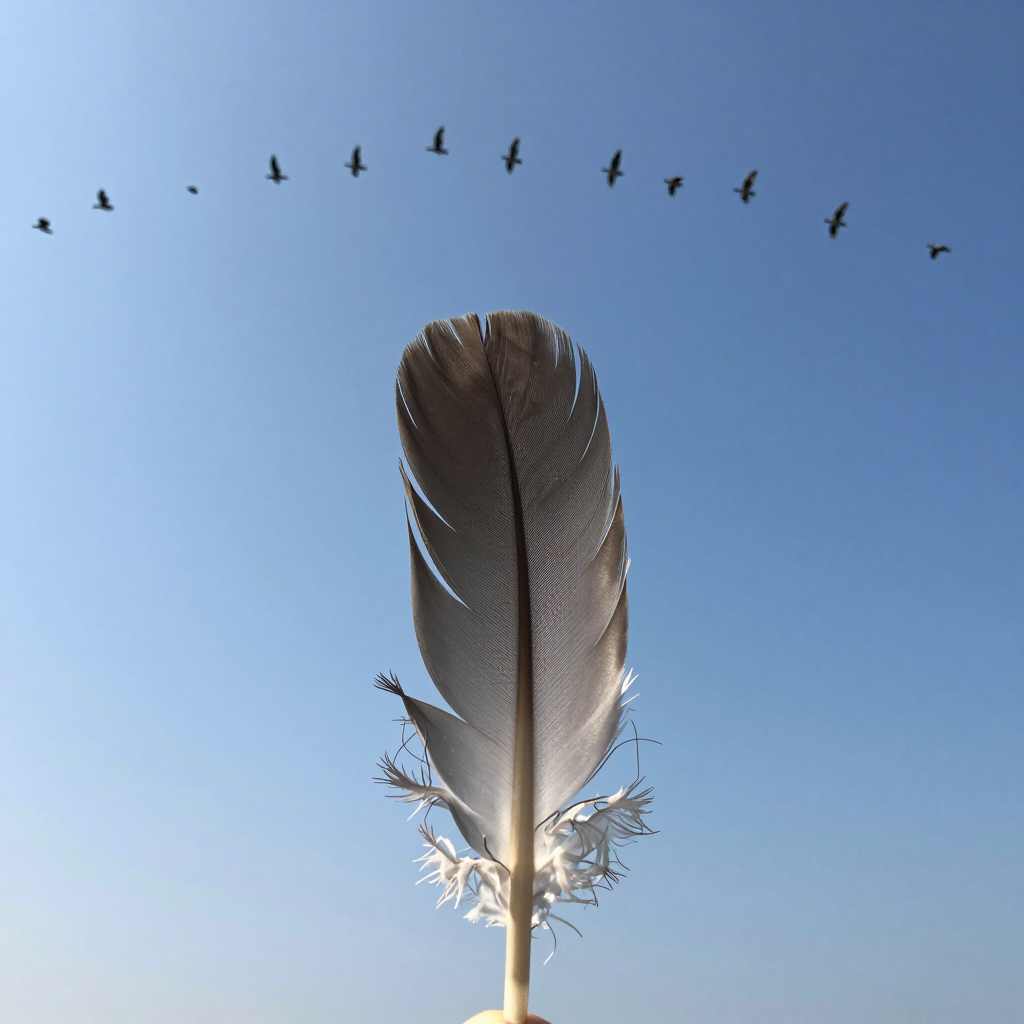
A close-up of a single feather right in front of you, and a flock of birds that looks really tiny soaring high overhead
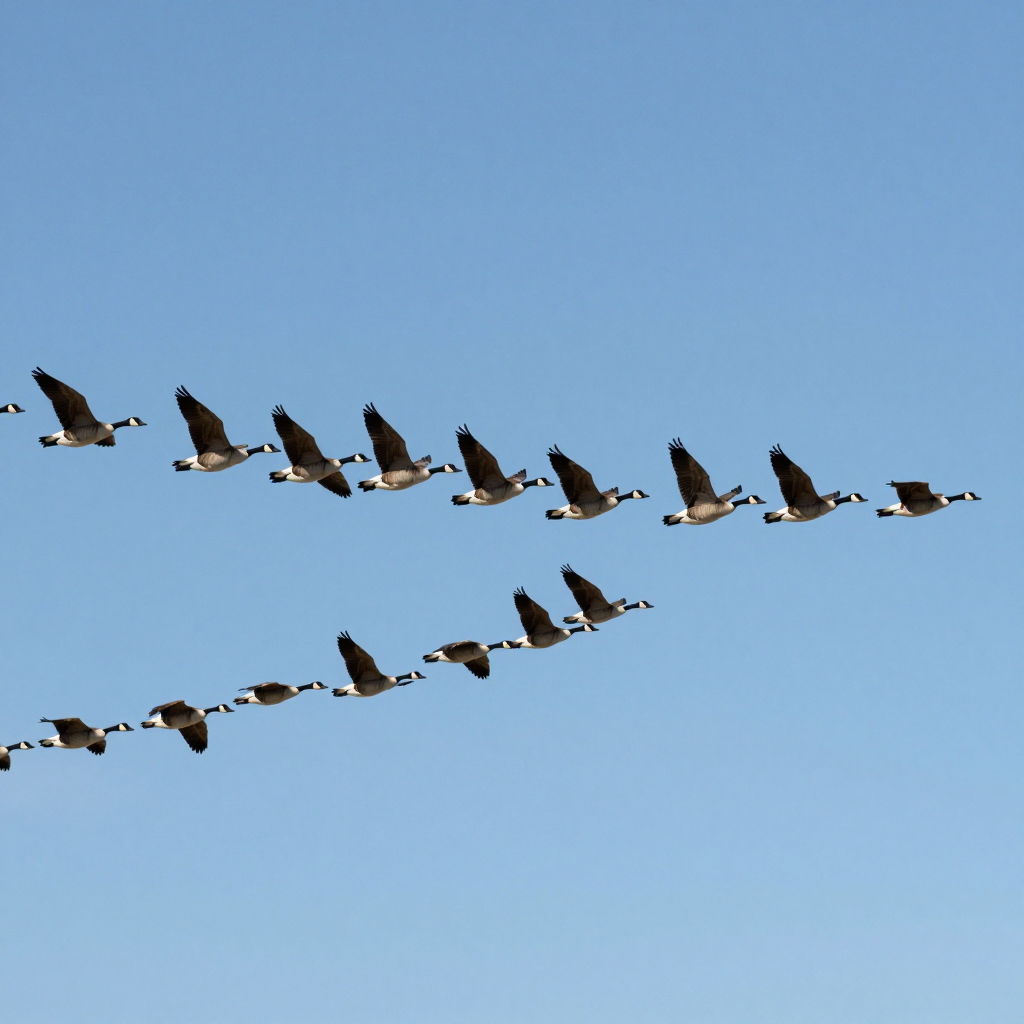
Migrating geese, emphasizing the shape of the formation
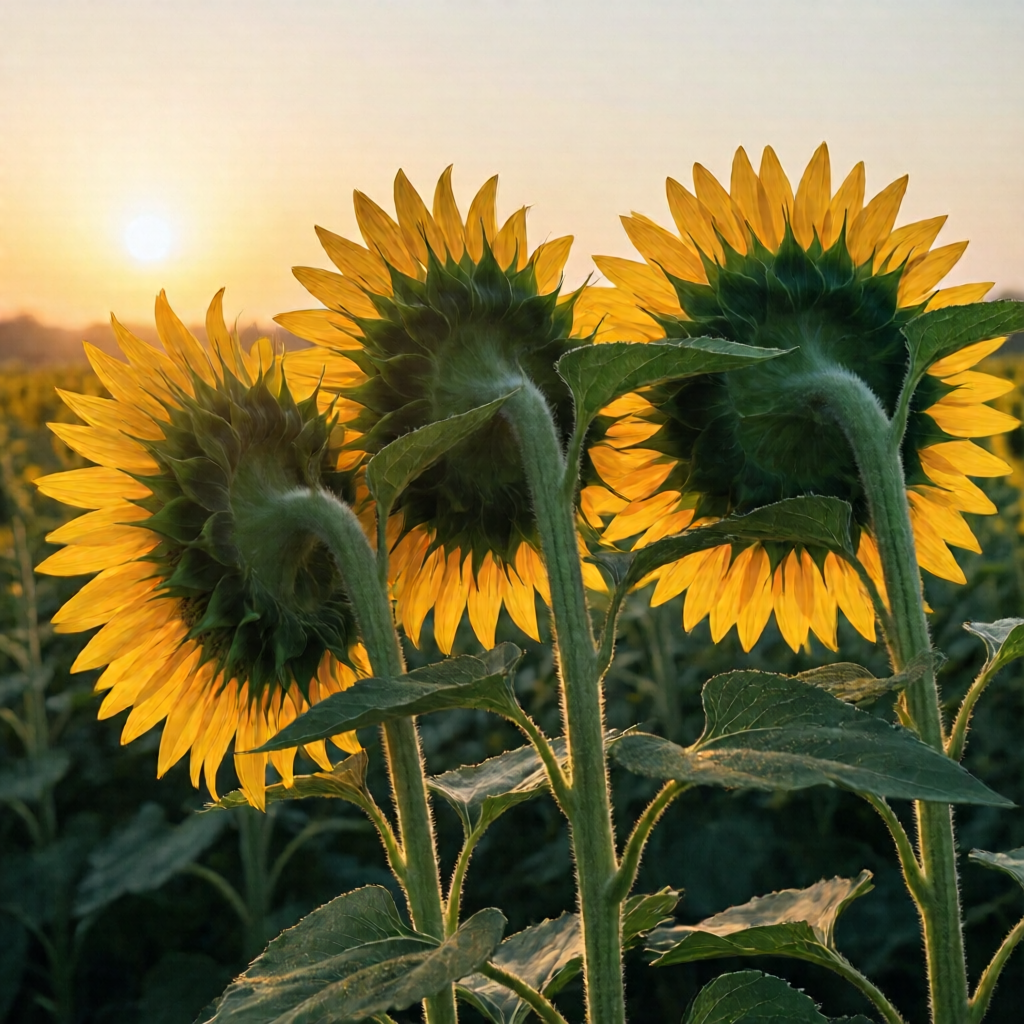
Sunflowers and the sun
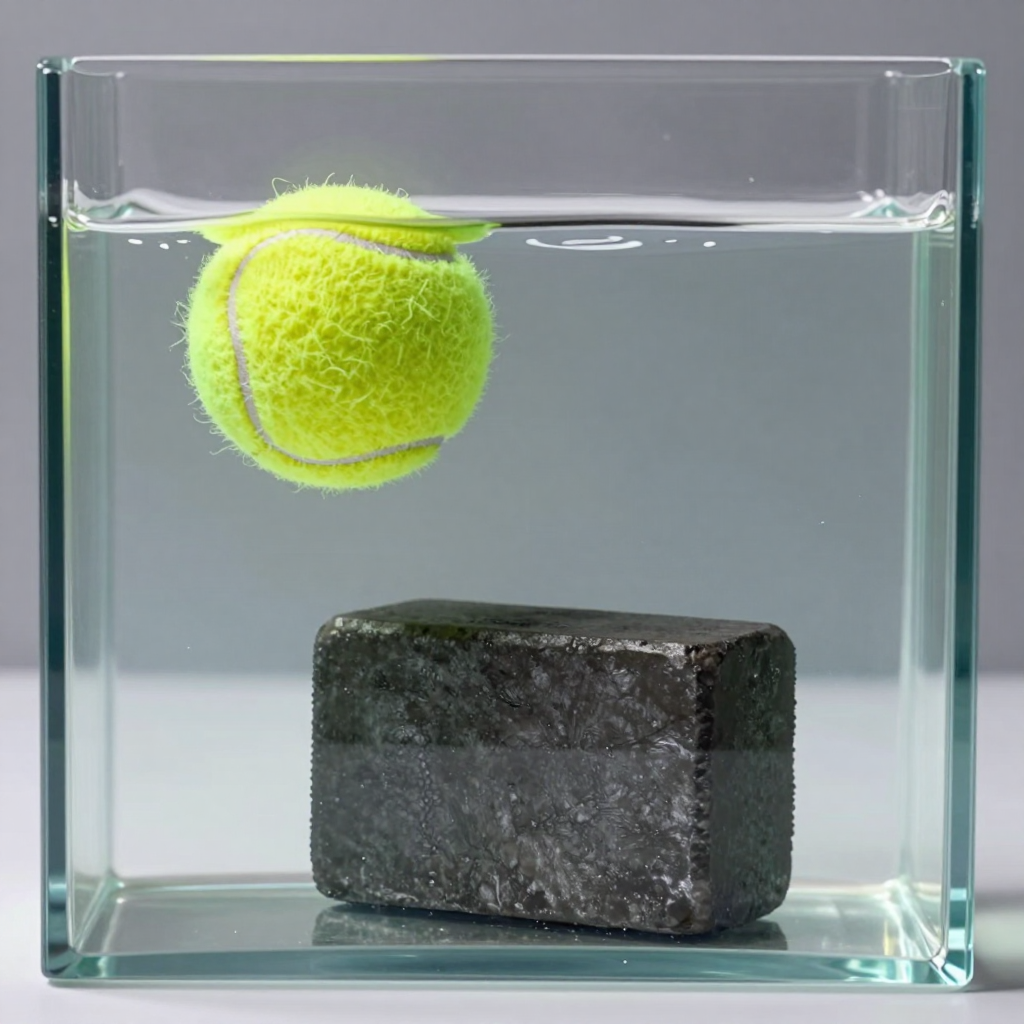
A tennis ball and a iron block are in a transparent water tank
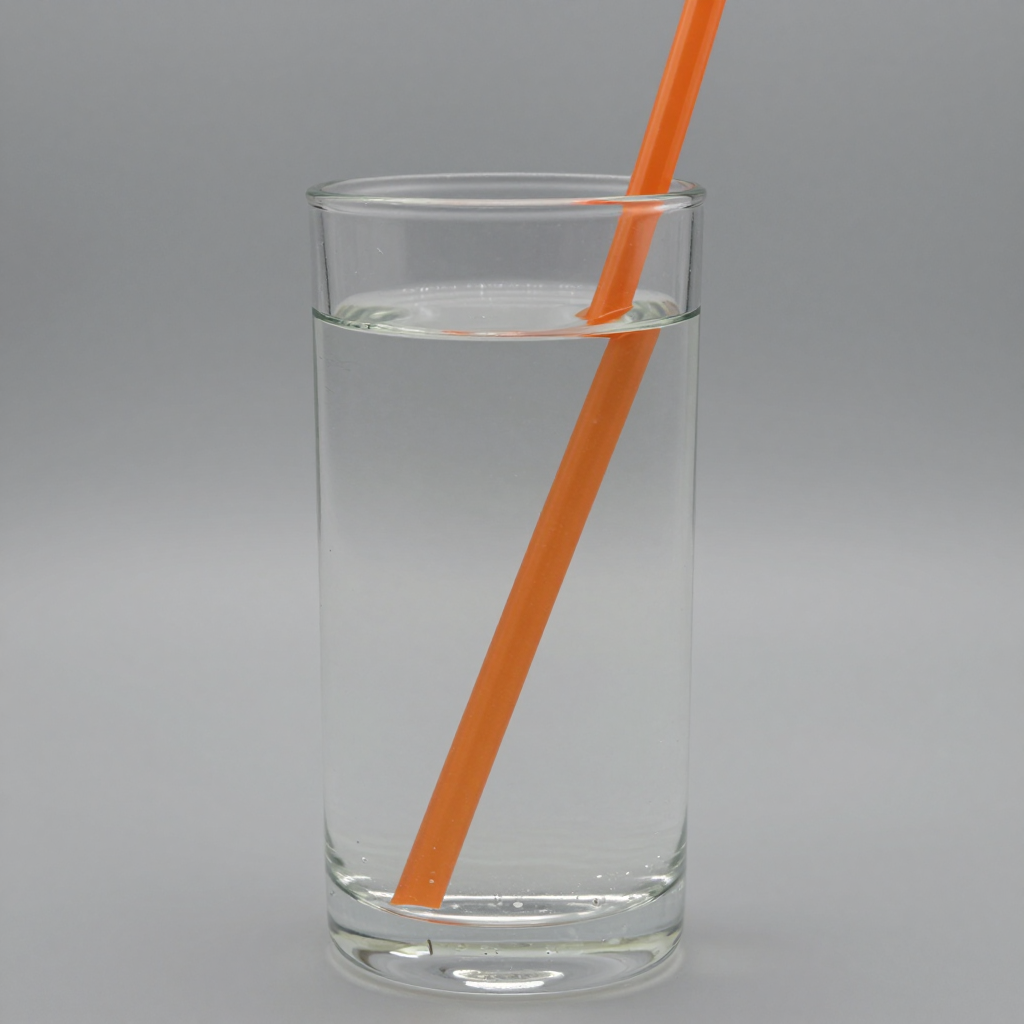
A clear glass of water with a portion of a plastic drinking straw submerge
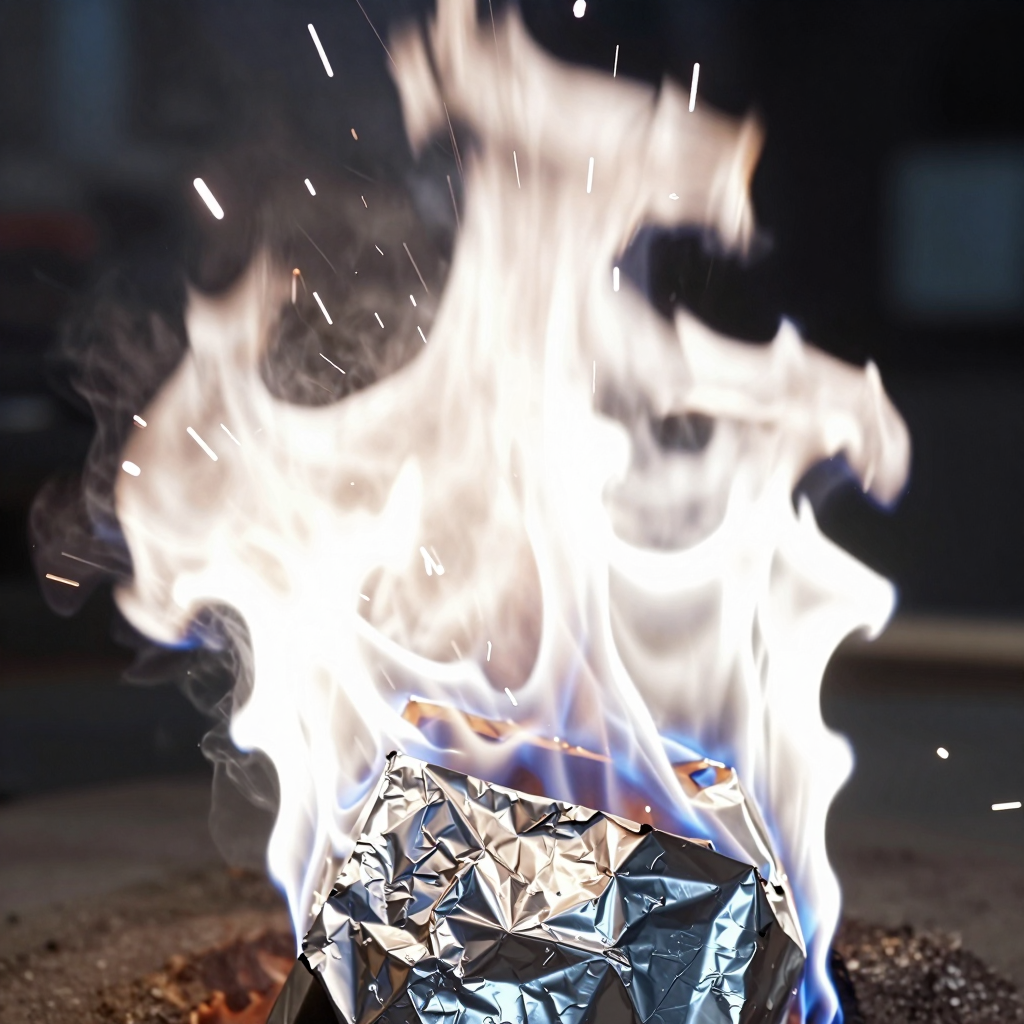
The aluminum is burning, highlighting the color
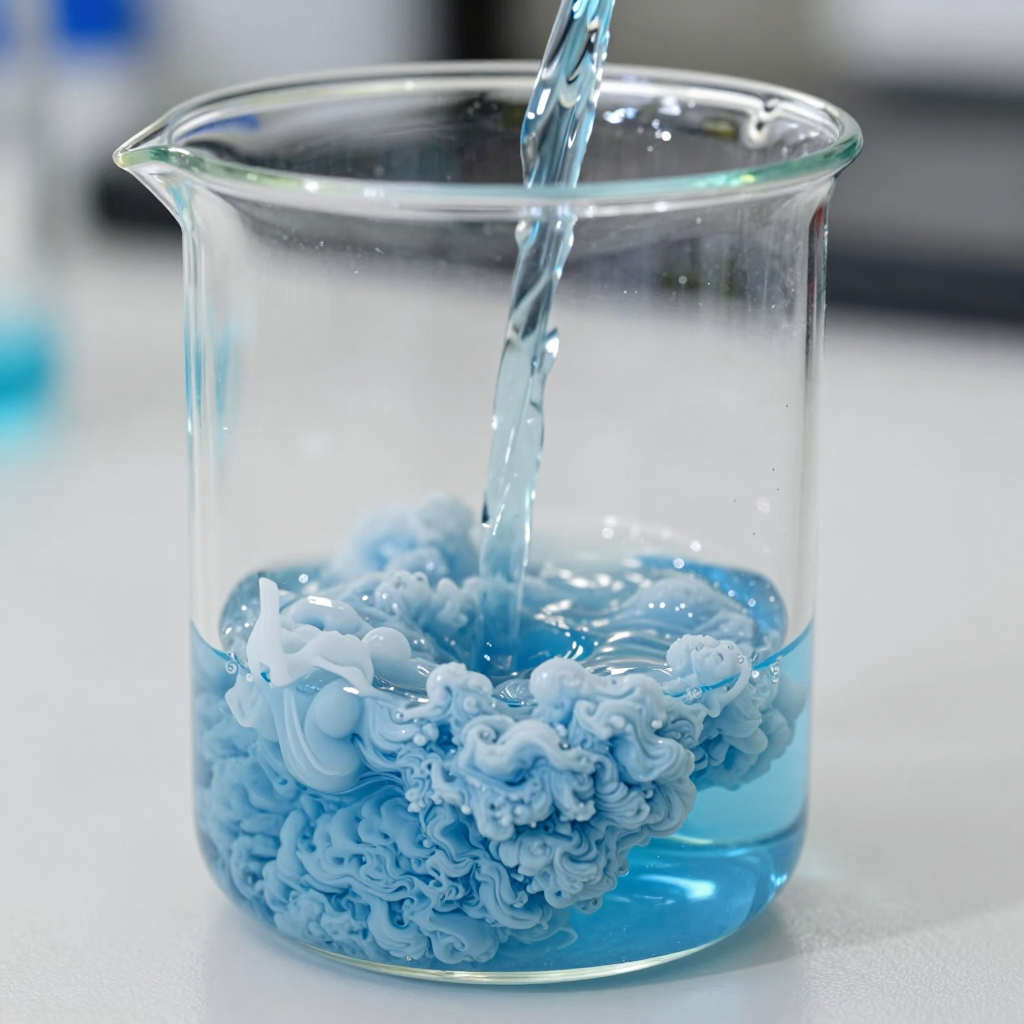
Copper sulfate solution mixing with sodium hydroxide solution in a beaker
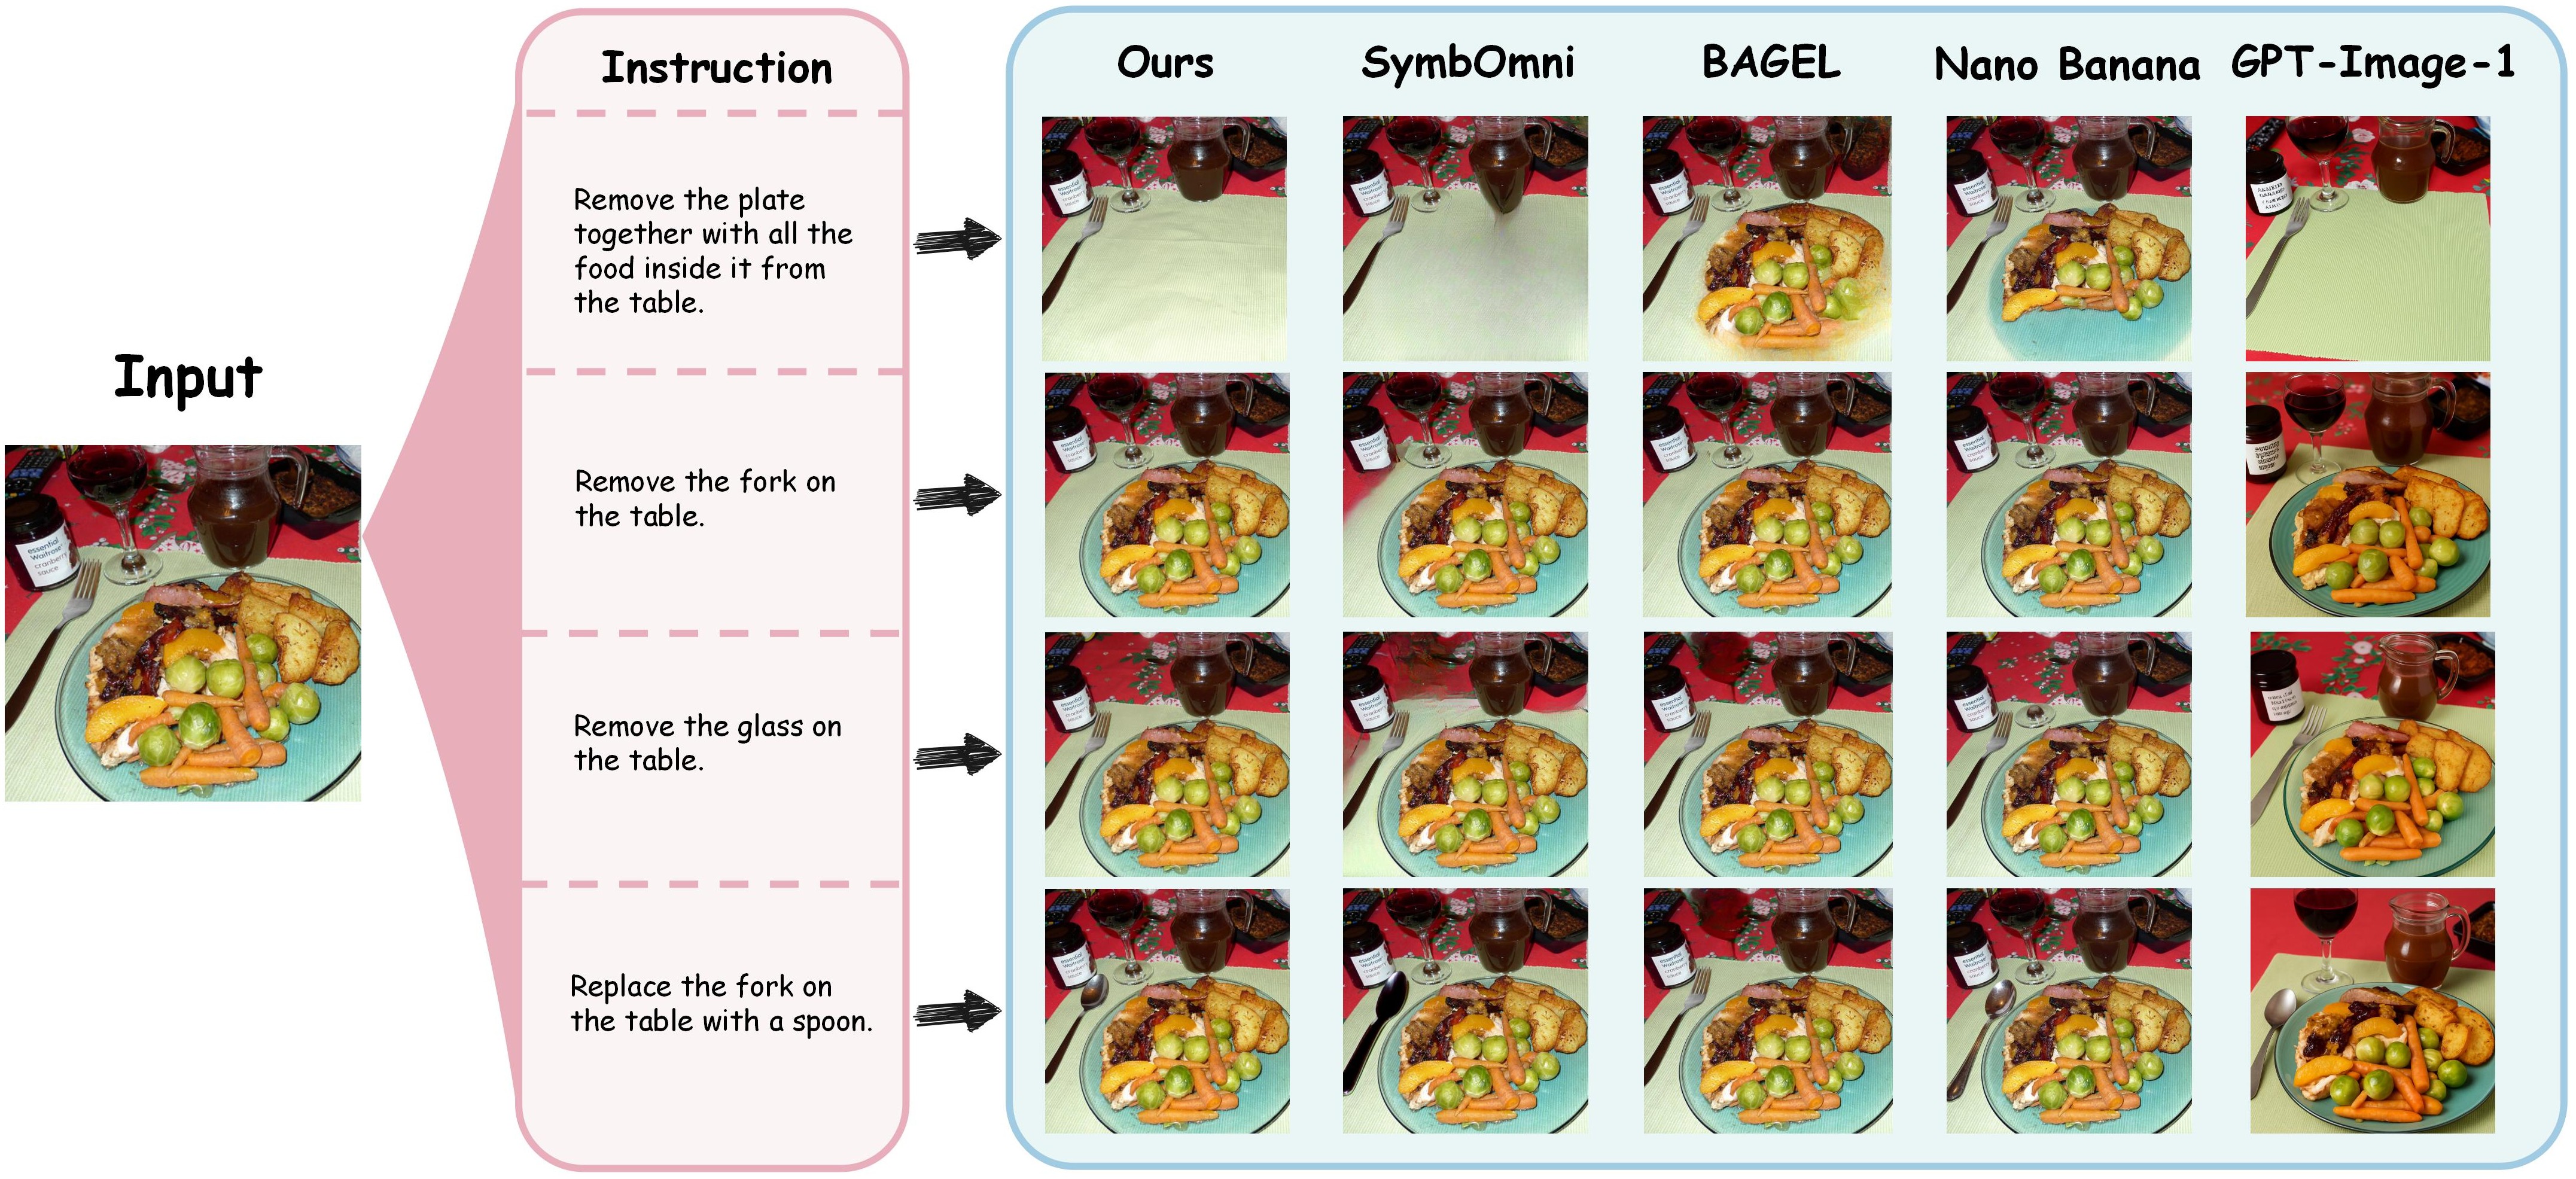
Remove the plate together with all the food inside it from the table.
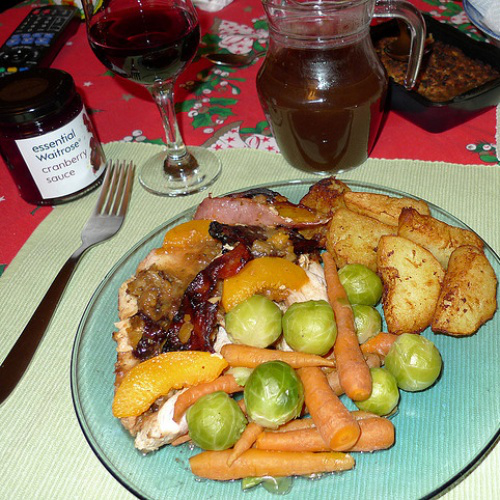
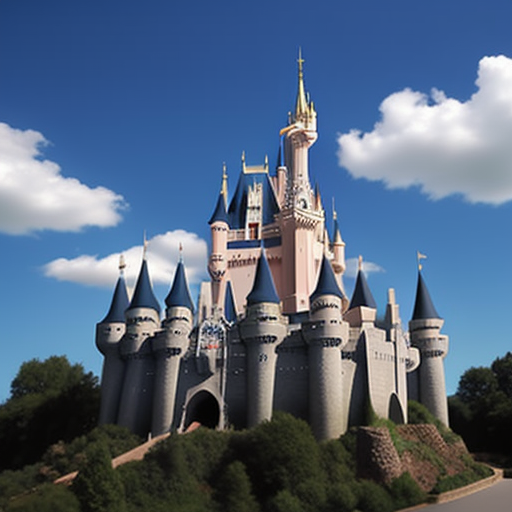
First follow the architecture style of the castle to generate a large church. Then convert it into a 2-second video.
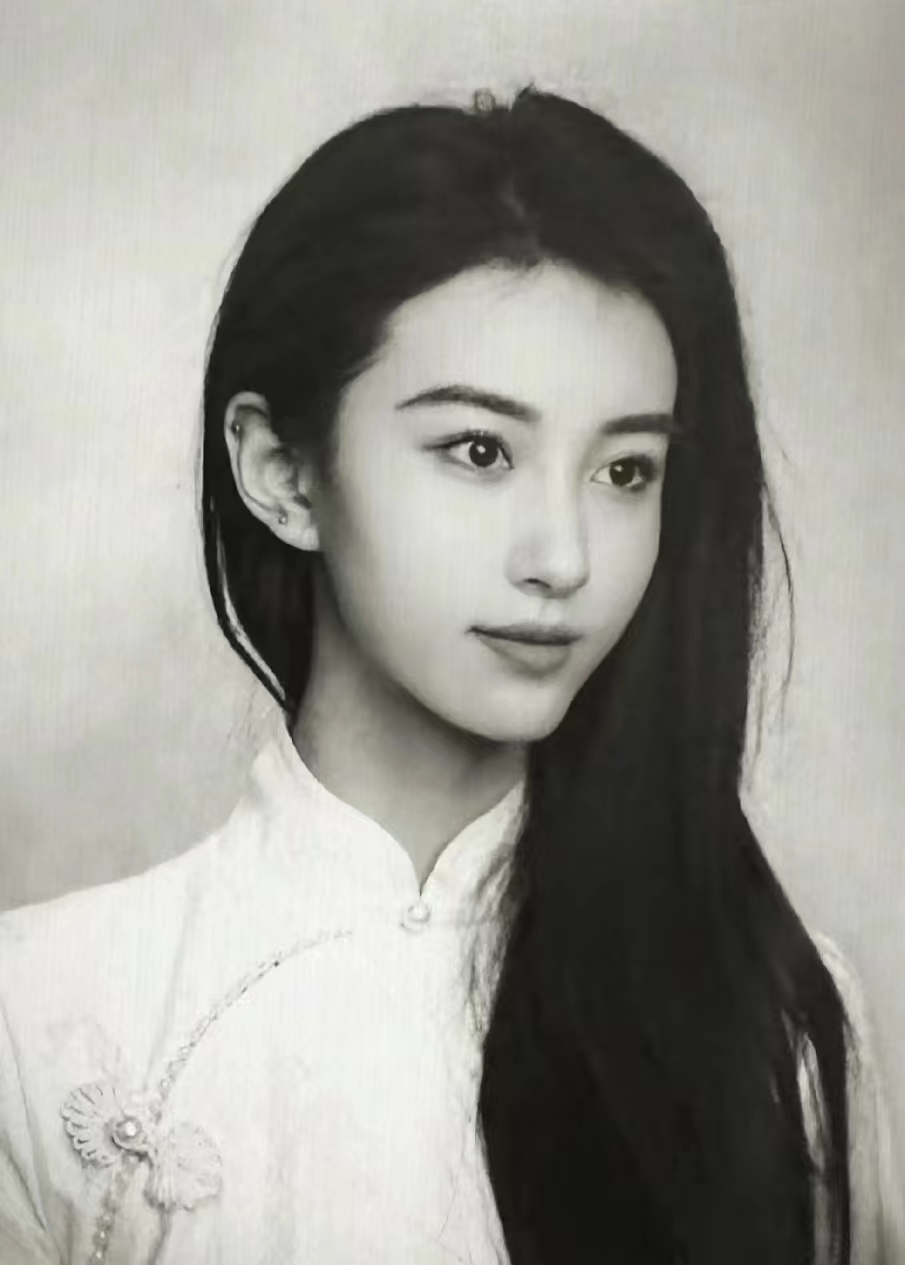
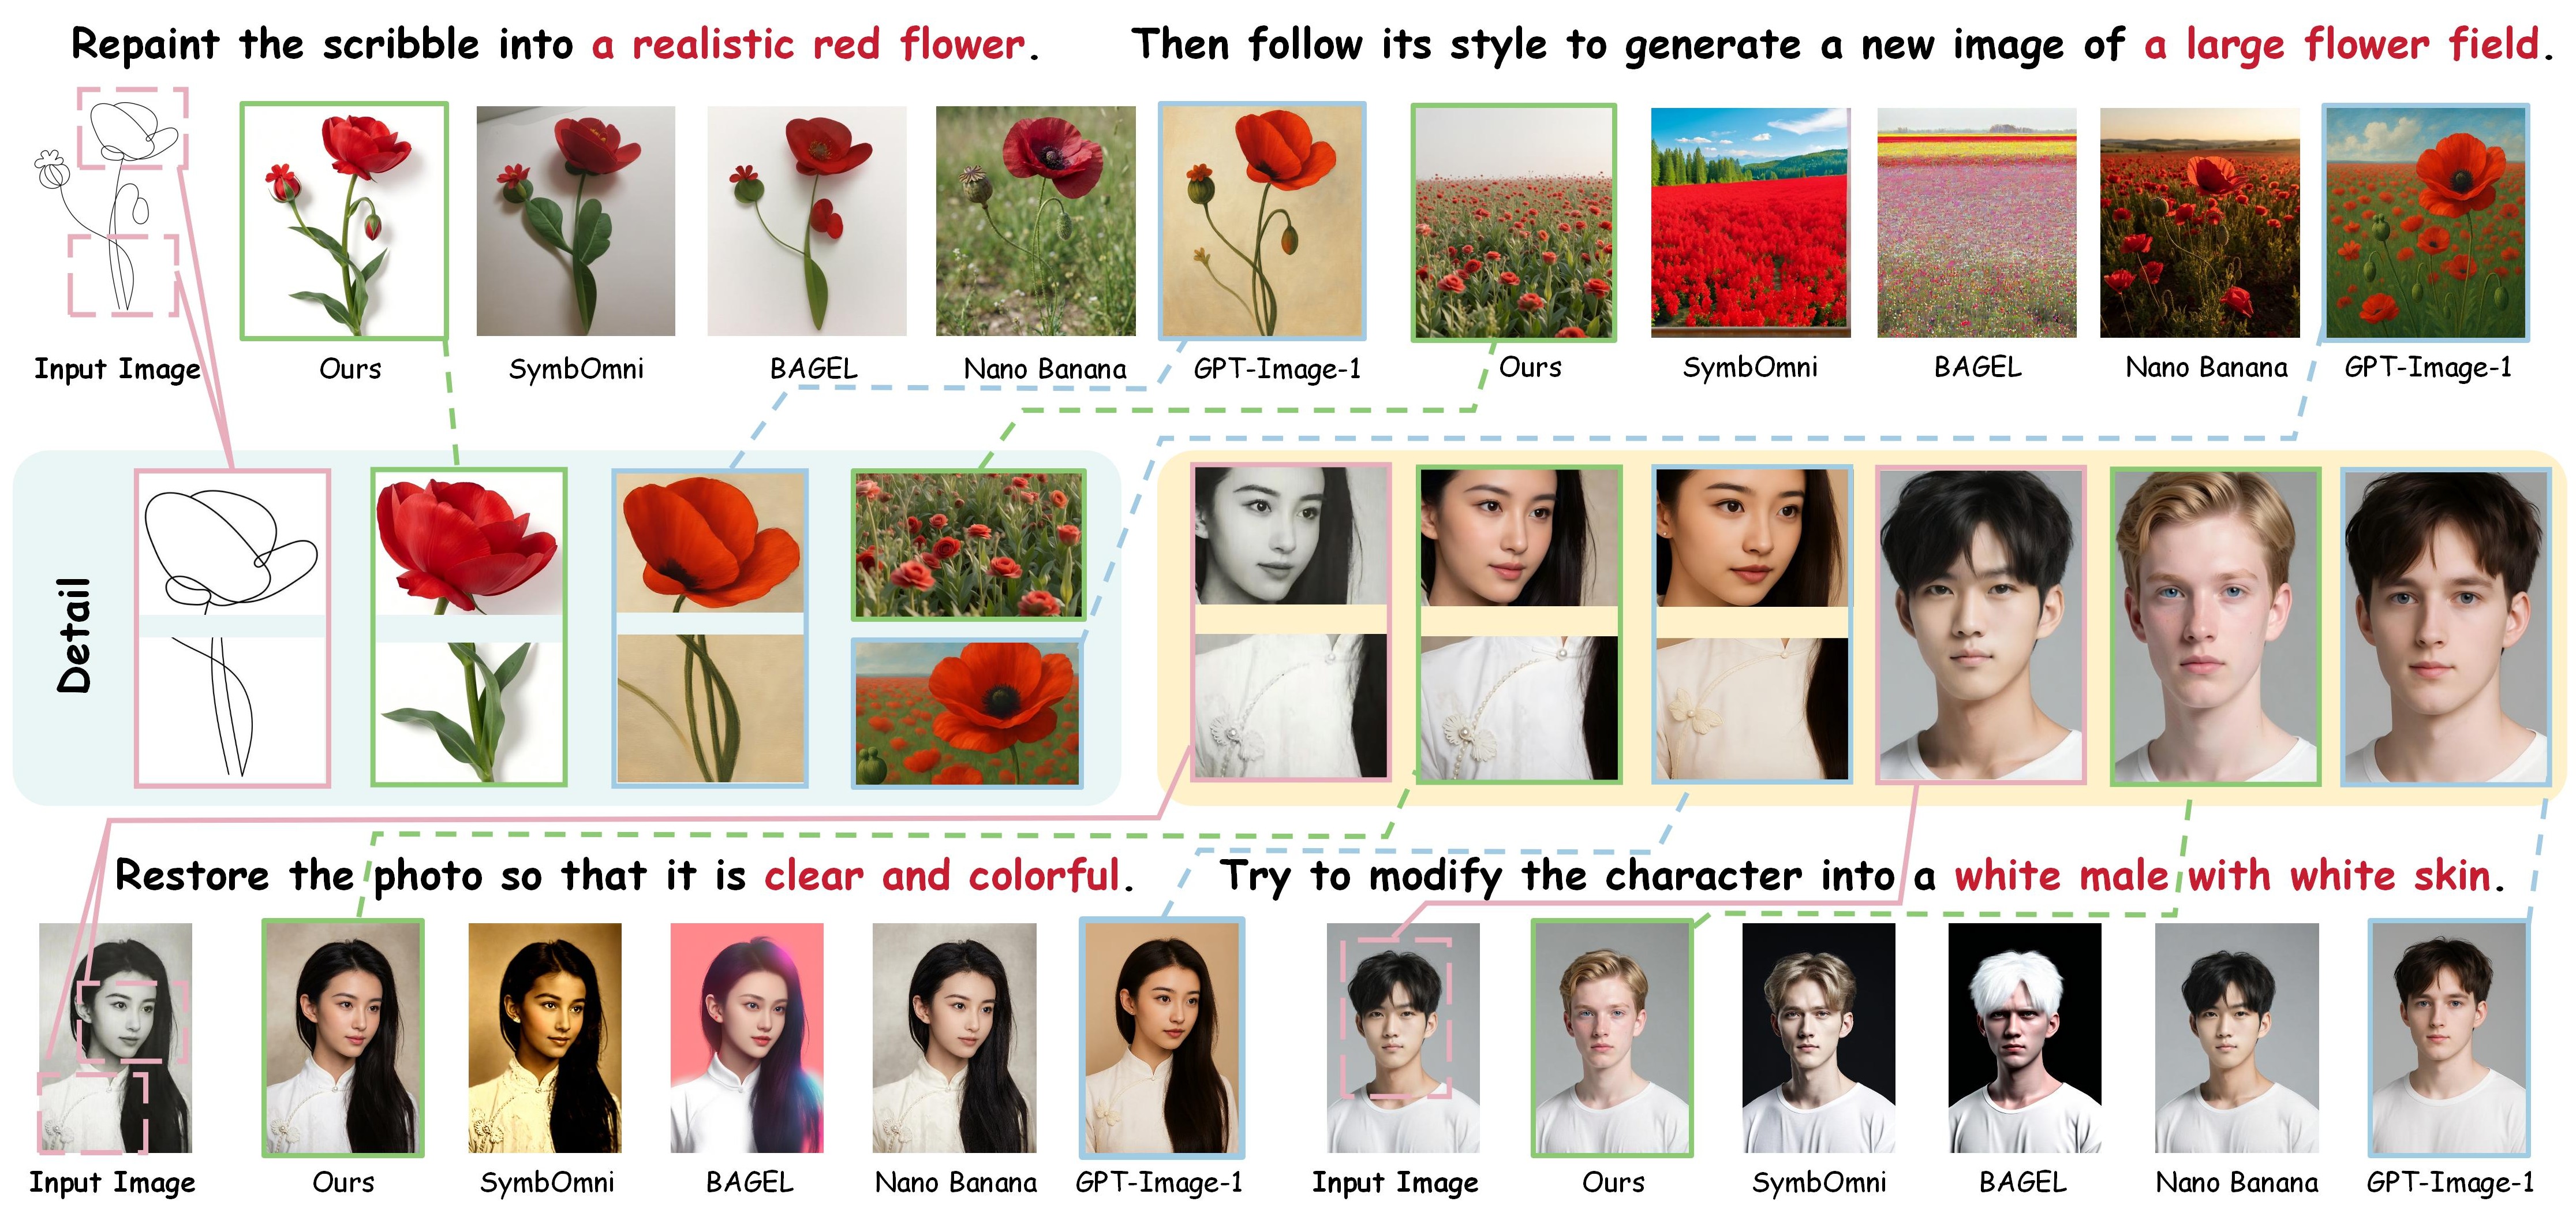
Modify the photo into a 2-second colorful video of the woman turning her head and smiling.
First repaint the scribble into a realistic gray pigeon. Then convert it into a 2-second video of the pigeon flying.

(a) End-to-end unified MLLMs enable fast multimodal generation but lack deliberate reasoning and self-correction.
(b) Existing multi-agent systems improve collaborative reasoning but lack unified coordination and persistent knowledge accumulation.
(c) OmniHarness integrates self-directed inquiry and feedback-guided execution to learn reusable symbolic policies for generalizable visual generation.

Self-directed inquiry and feedback-guided execution drive symbolic policy learning for generalizable visual generation. The policy library evolves during OmniHarness execution, while frozen snapshots support plug-and-play reuse across visual agents.
Differences are relative to the first method in each group. Red indicates an increase, green a decrease, and gray no change; metric arrows indicate whether higher or lower is better.
ComfyBench evaluates autonomous workflow construction, where each agent must produce an executable ComfyUI workflow that satisfies the task requirements.
| Agent | Vanilla | Complex | Creative | Total | ||||
|---|---|---|---|---|---|---|---|---|
| Pass↑ | Res.↑ | Pass↑ | Res.↑ | Pass↑ | Res.↑ | Pass↑ | Res.↑ | |
| GPT-4o + Zero-shot | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| GPT-4o + Few-shot | 32.0↑32.0 | 27.0↑27.0 | 16.7↑16.7 | 8.3↑8.3 | 7.5↑7.5 | 0.0=0.0 | 22.5↑22.5 | 16.0↑16.0 |
| GPT-4o + CoT | 44.0↑44.0 | 29.0↑29.0 | 11.7↑11.7 | 8.3↑8.3 | 12.5↑12.5 | 0.0=0.0 | 28.0↑28.0 | 17.0↑17.0 |
| GPT-4o + CoT-SC | 45.0↑45.0 | 34.0↑34.0 | 11.7↑11.7 | 5.0↑5.0 | 15.0↑15.0 | 0.0=0.0 | 29.0↑29.0 | 18.5↑18.5 |
| Claude-3.5-Sonnet + RAG | 27.0↑27.0 | 13.0↑13.0 | 23.0↑23.0 | 6.7↑6.7 | 7.5↑7.5 | 0.0=0.0 | 22.0↑22.0 | 8.5↑8.5 |
| Llama-3.1-70B + RAG | 58.0↑58.0 | 32.0↑32.0 | 23.0↑23.0 | 10.0↑10.0 | 15.0↑15.0 | 5.0↑5.0 | 39.0↑39.0 | 20.0↑20.0 |
| GPT-4o + RAG | 62.0↑62.0 | 41.0↑41.0 | 45.0↑45.0 | 21.7↑21.7 | 40.0↑40.0 | 7.5↑7.5 | 52.0↑52.0 | 23.0↑23.0 |
| o1-mini + RAG | 32.0↑32.0 | 16.0↑16.0 | 21.7↑21.7 | 8.3↑8.3 | 12.5↑12.5 | 7.5↑7.5 | 25.0↑25.0 | 12.0↑12.0 |
| o1-preview + RAG | 70.0↑70.0 | 46.0↑46.0 | 48.3↑48.3 | 23.3↑23.3 | 30.0↑30.0 | 12.5↑12.5 | 55.5↑55.5 | 32.5↑32.5 |
| Llama-3.1-70B + ComfyAgent | 63.0 | 35.0 | 26.7 | 18.3 | 20.0 | 5.0 | 43.5 | 24.0 |
| GPT-4o + ComfyAgent | 67.0↑4.0 | 46.0↑11.0 | 48.3↑21.6 | 21.7↑3.4 | 40.0↑20.0 | 15.0↑10.0 | 56.0↑12.5 | 32.5↑8.5 |
| GPT-4o + ComfyMind | 100.0↑37.0 | 92.0↑57.0 | 100.0↑73.3 | 85.0↑66.7 | 100.0↑80.0 | 57.5↑52.5 | 100.0↑56.5 | 83.0↑59.0 |
| DeepSeek-V3 + ComfyMind | 100.0↑37.0 | 90.0↑55.0 | 100.0↑73.3 | 71.7↑53.4 | 100.0↑80.0 | 60.0↑55.0 | 100.0↑56.5 | 78.5↑54.5 |
| Gemini-2.5-Flash + SymbOmni | 100.0↑37.0 | 95.0↑60.0 | 100.0↑73.3 | 83.3↑65.0 | 100.0↑80.0 | 67.5↑62.5 | 100.0↑56.5 | 86.0↑62.0 |
| GPT-4o + OmniHarness | 100.0↑37.0 | 95.0↑60.0 | 100.0↑73.3 | 76.7↑58.4 | 100.0↑80.0 | 95.0↑90.0 | 100.0↑56.5 | 89.5↑65.5 |
| Codex GPT-4o + OmniHarness | 100.0↑37.0 | 97.0↑62.0 | 100.0↑73.3 | 83.3↑65.0 | 100.0↑80.0 | 95.0↑90.0 | 100.0↑56.5 | 92.5↑68.5 |
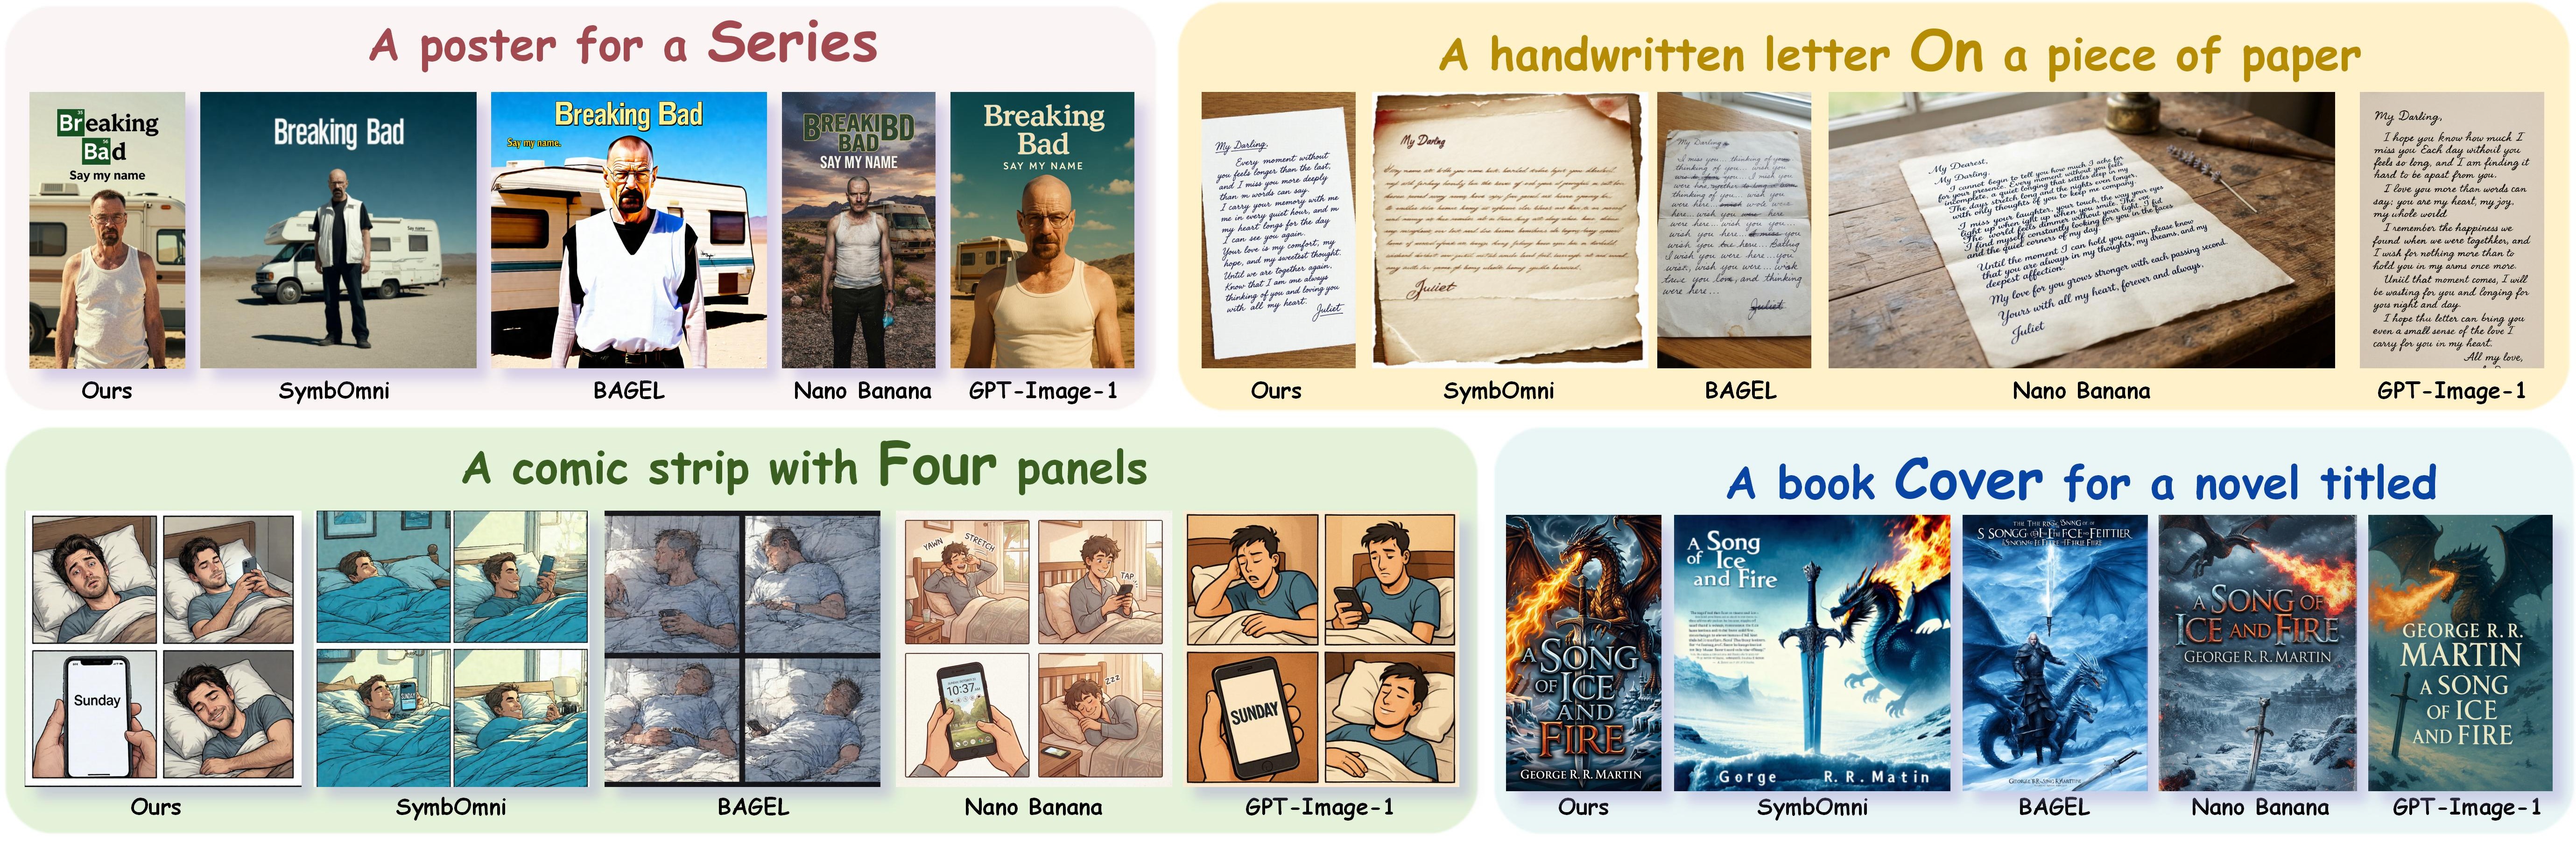
GenEval measures compositional text-to-image fidelity through single-object generation, two-object co-occurrence, counting, color, relative position, and attribute binding.
| Method | Single Obj.↑ | Two Obj.↑ | Counting↑ | Colors↑ | Position↑ | Attr. Bind.↑ | Overall↑ |
|---|---|---|---|---|---|---|---|
| Frozen Text-Encoder Mapping Methods | |||||||
| SDv1.5 | 0.97 | 0.38 | 0.35 | 0.76 | 0.04 | 0.06 | 0.43 |
| SDv2.1 | 0.98↑0.01 | 0.51↑0.13 | 0.44↑0.09 | 0.85↑0.09 | 0.07↑0.03 | 0.17↑0.11 | 0.50↑0.07 |
| SD-XL | 0.98↑0.01 | 0.74↑0.36 | 0.39↑0.04 | 0.85↑0.09 | 0.15↑0.11 | 0.23↑0.17 | 0.55↑0.12 |
| DALL-E 2 | 0.94↓0.03 | 0.66↑0.28 | 0.49↑0.14 | 0.77↑0.01 | 0.10↑0.06 | 0.19↑0.13 | 0.52↑0.09 |
| SD3-Medium | 0.99↑0.02 | 0.94↑0.56 | 0.72↑0.37 | 0.89↑0.13 | 0.33↑0.29 | 0.60↑0.54 | 0.74↑0.31 |
| Unified Multimodal Models | |||||||
| LlamaGen | 0.71 | 0.34 | 0.21 | 0.58 | 0.07 | 0.04 | 0.32 |
| LWM | 0.93↑0.22 | 0.41↑0.07 | 0.46↑0.25 | 0.79↑0.21 | 0.09↑0.02 | 0.15↑0.11 | 0.47↑0.15 |
| SEED-X | 0.97↑0.26 | 0.58↑0.24 | 0.26↑0.05 | 0.80↑0.22 | 0.19↑0.12 | 0.14↑0.10 | 0.49↑0.17 |
| Emu3-Gen | 0.98↑0.27 | 0.71↑0.37 | 0.34↑0.13 | 0.81↑0.23 | 0.17↑0.10 | 0.21↑0.17 | 0.54↑0.22 |
| Janus | 0.97↑0.26 | 0.68↑0.34 | 0.30↑0.09 | 0.84↑0.26 | 0.46↑0.39 | 0.42↑0.38 | 0.61↑0.29 |
| JanusFlow | 0.97↑0.26 | 0.59↑0.25 | 0.45↑0.24 | 0.83↑0.25 | 0.53↑0.46 | 0.42↑0.38 | 0.63↑0.31 |
| Janus-Pro-7B | 0.99↑0.28 | 0.89↑0.55 | 0.59↑0.38 | 0.90↑0.32 | 0.79↑0.72 | 0.66↑0.62 | 0.80↑0.48 |
| GoT | 0.99↑0.28 | 0.69↑0.35 | 0.67↑0.46 | 0.85↑0.27 | 0.34↑0.27 | 0.27↑0.23 | 0.64↑0.32 |
| Bagel | 0.98↑0.27 | 0.94↑0.60 | 0.76↑0.55 | 0.91↑0.33 | 0.69↑0.62 | 0.70↑0.66 | 0.78↑0.46 |
| GPT-Image-1 | 0.99↑0.28 | 0.92↑0.58 | 0.85↑0.64 | 0.92↑0.34 | 0.75↑0.68 | 0.61↑0.57 | 0.84↑0.52 |
| Collaborative AI Systems | |||||||
| ComfyAgent | 0.69 | 0.30 | 0.33 | 0.50 | 0.04 | 0.04 | 0.32 |
| ComfyMind | 1.00↑0.31 | 1.00↑0.70 | 0.96↑0.63 | 0.97↑0.47 | 0.63↑0.59 | 0.81↑0.77 | 0.90↑0.58 |
| SymbOmni | 1.00↑0.31 | 1.00↑0.70 | 0.99↑0.66 | 0.98↑0.48 | 0.97↑0.93 | 0.95↑0.91 | 0.98↑0.66 |
| OmniHarness | 1.00↑0.31 | 1.00↑0.70 | 1.00↑0.67 | 1.00↑0.50 | 1.00↑0.96 | 0.98↑0.94 | 0.997↑0.677 |
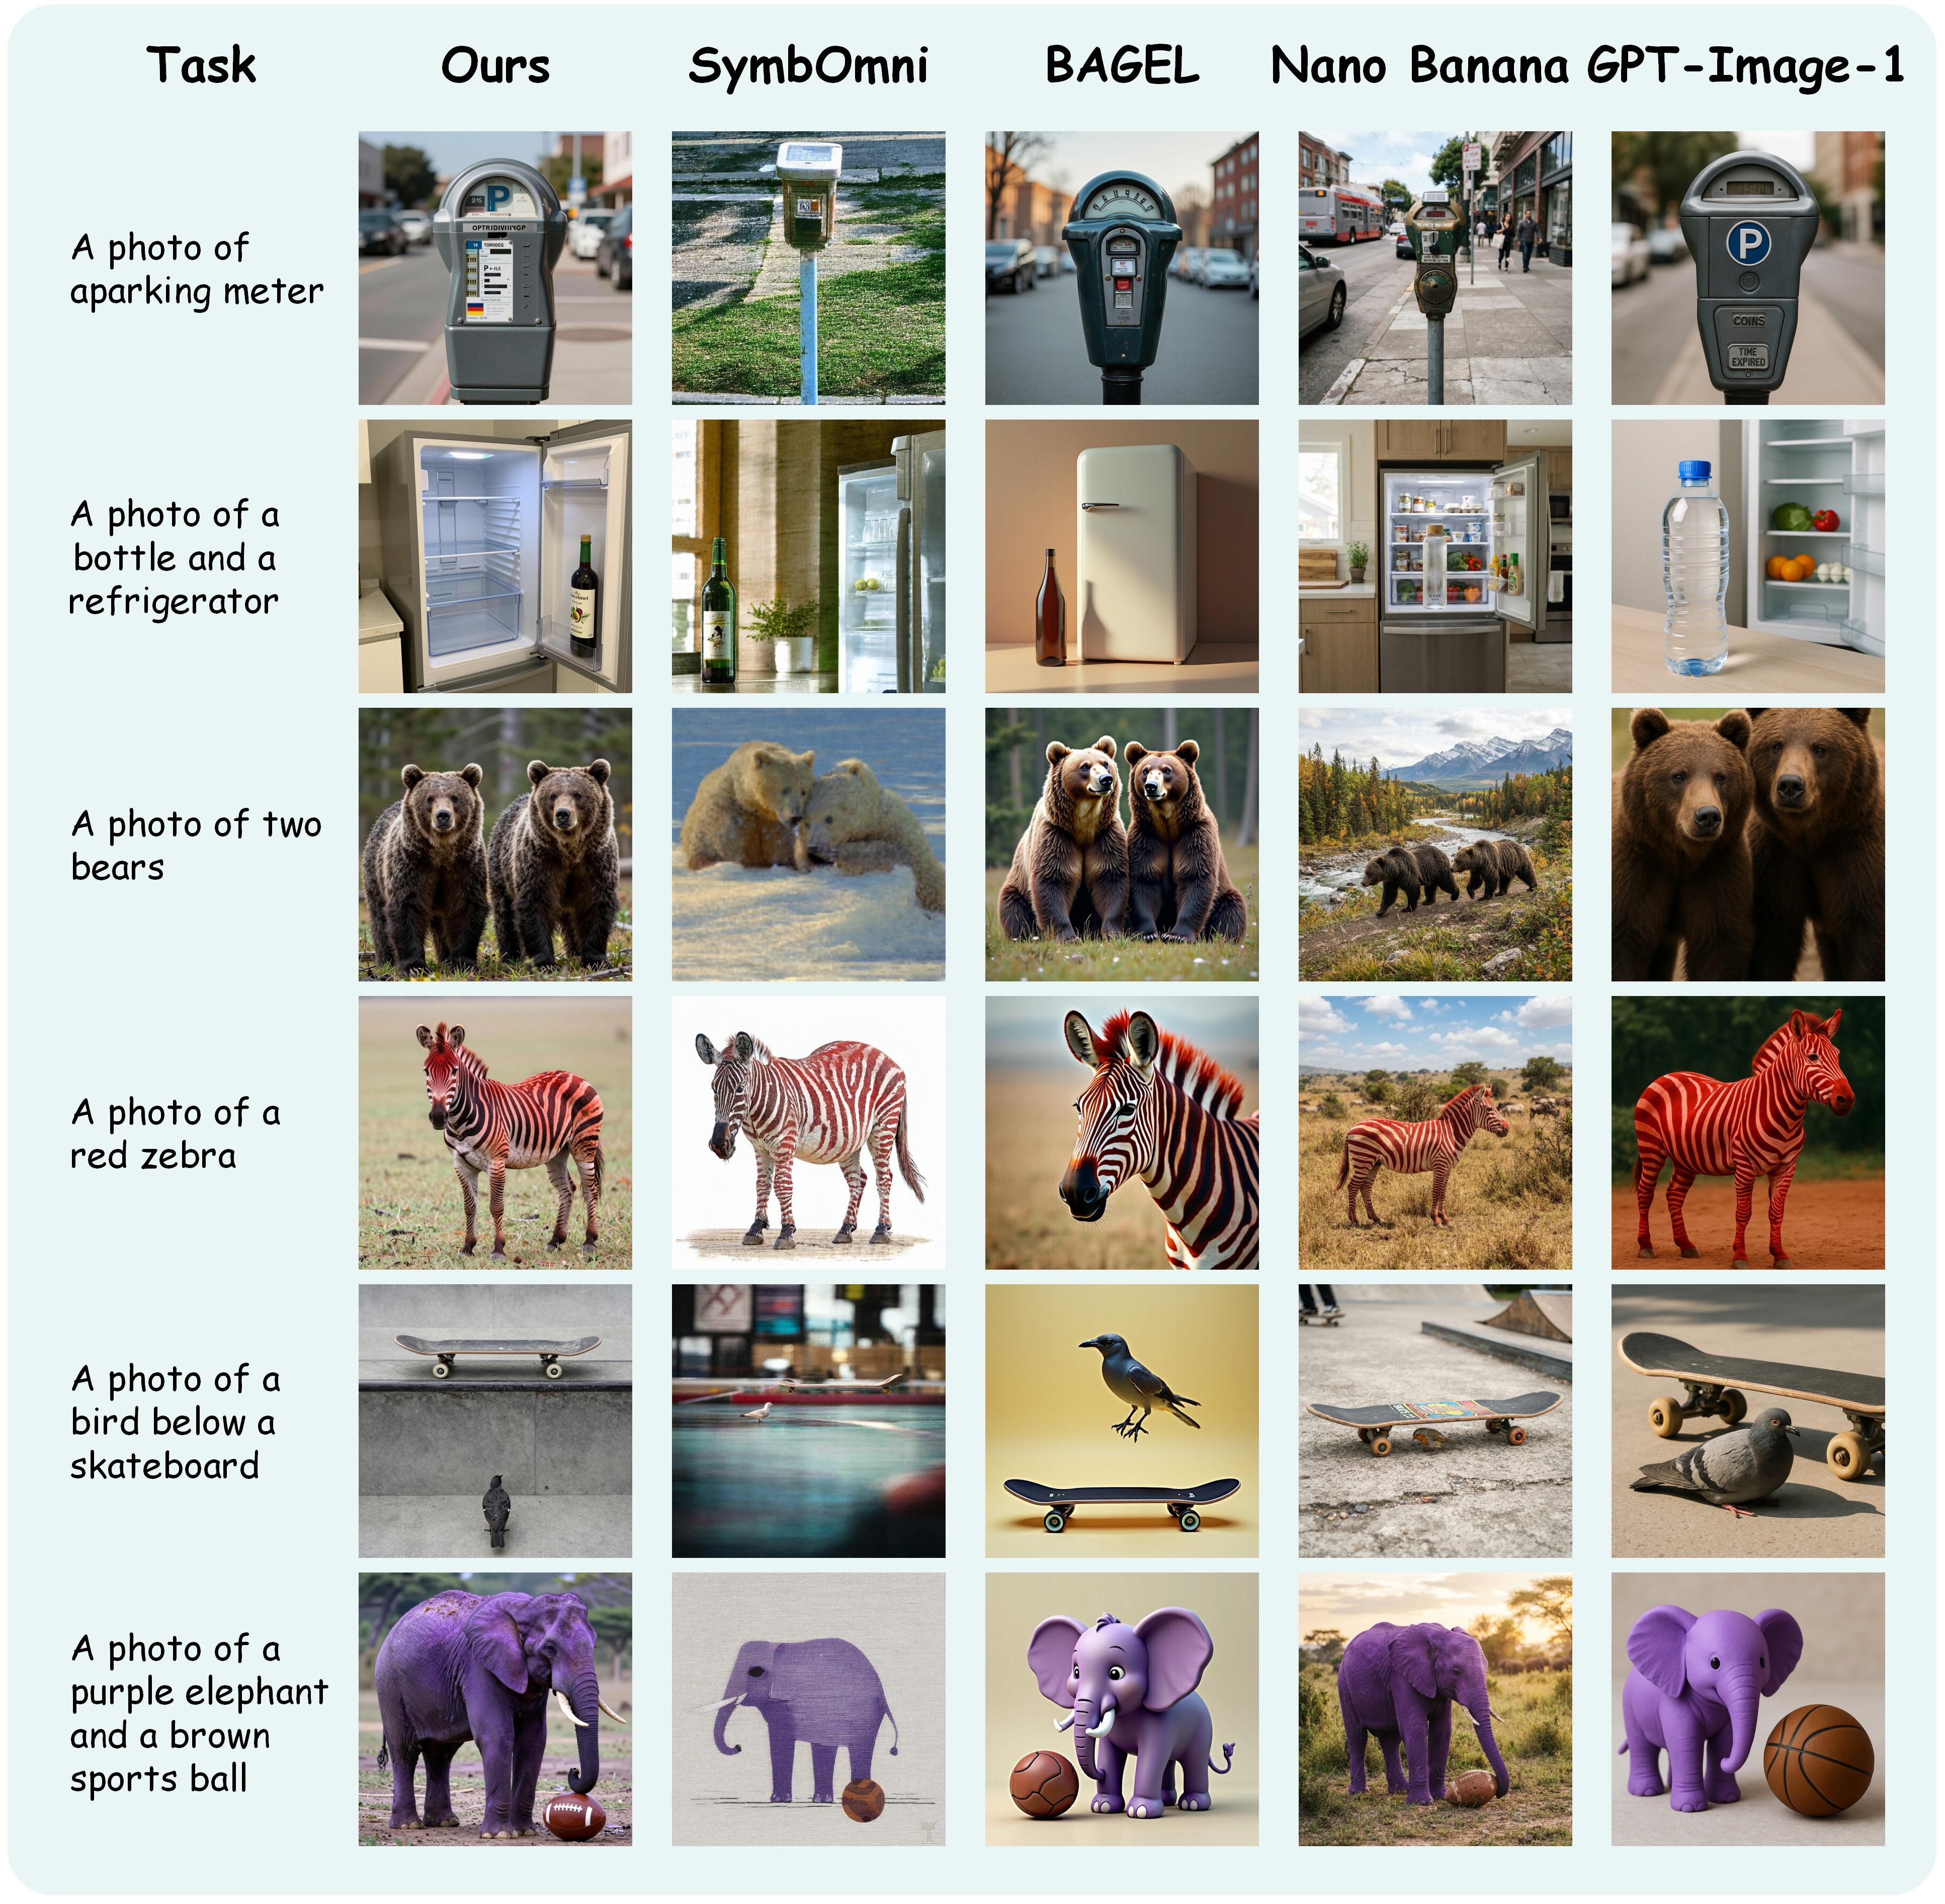
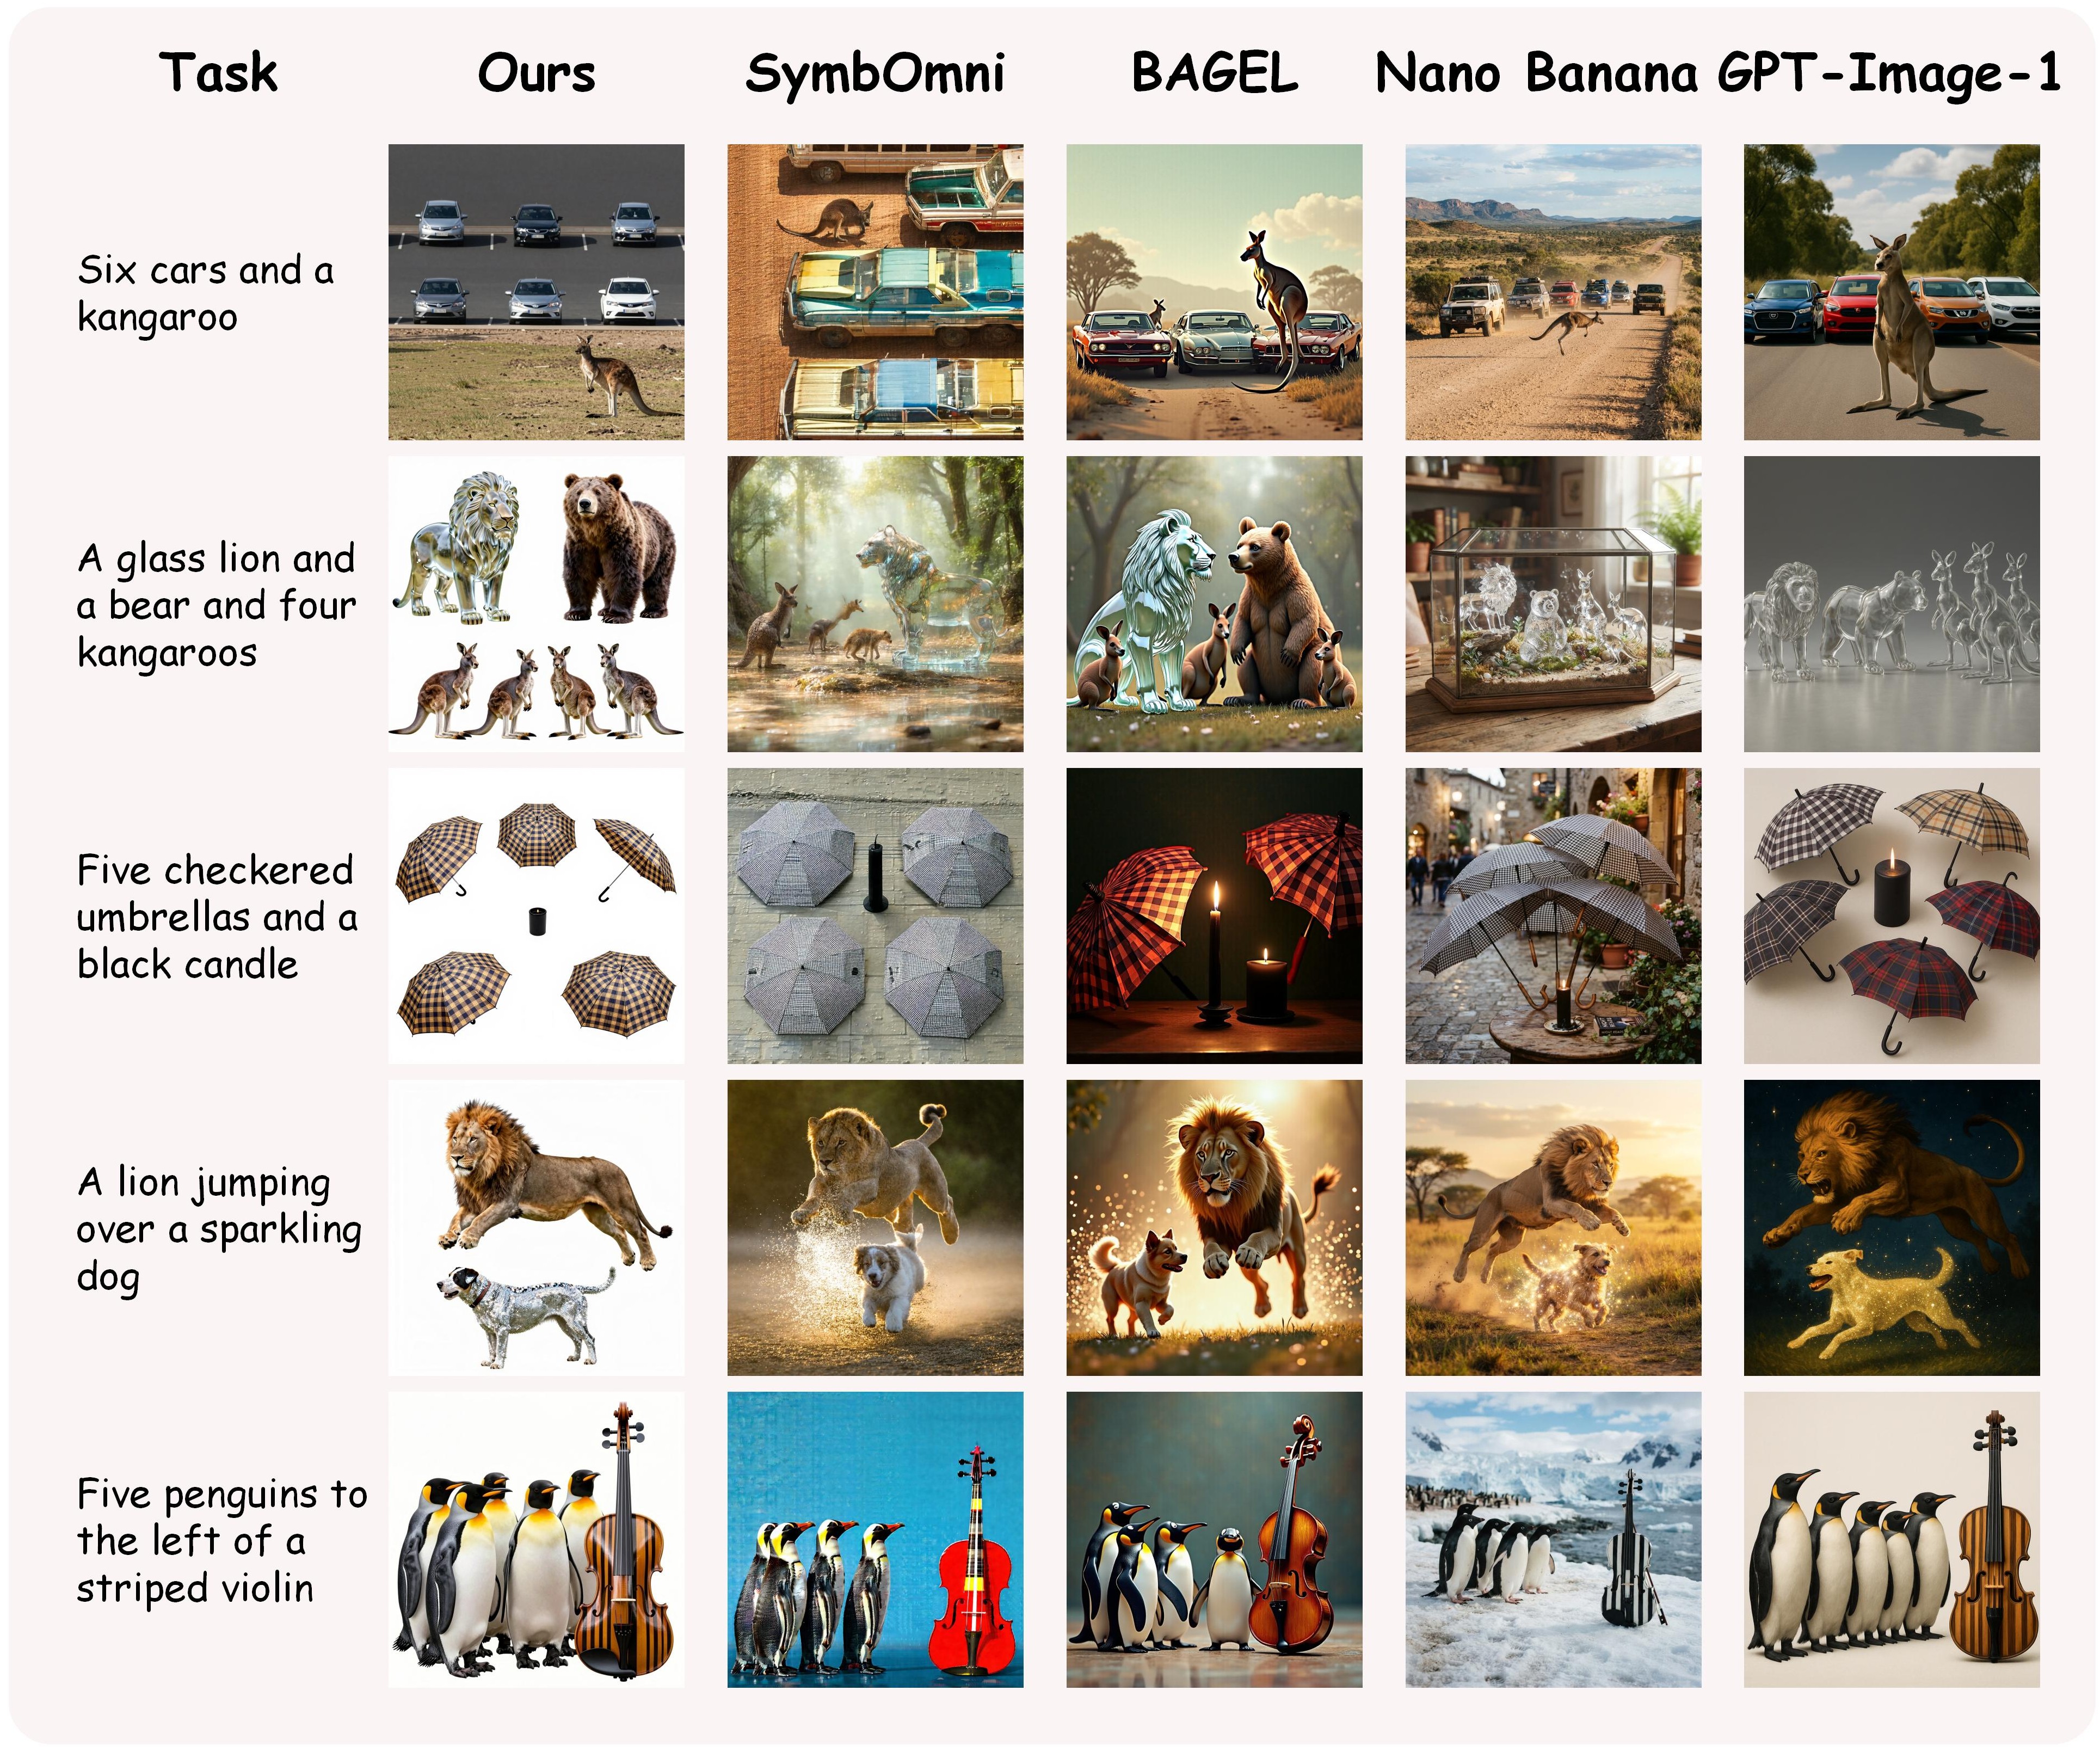
GenEval2 provides a fine-grained evaluation of text-to-image generation across object generation, attribute rendering, counting, spatial relations, and transitive verb relations.
| Method | Object↑ | Attribute↑ | Count↑ | Position↑ | Verb↑ | Overall↑ |
|---|---|---|---|---|---|---|
| Stable Diffusion Model Series | ||||||
| SD 2.1 | 55.1 | 30.4 | 22.3 | 11.7 | 17.8 | 27.46 |
| SDXL | 74.1↑19.0 | 42.4↑12.0 | 28.7↑6.4 | 16.0↑4.3 | 28.9↑11.1 | 38.02↑10.56 |
| SD3 | 87.0↑31.9 | 65.5↑35.1 | 49.9↑27.6 | 41.0↑29.3 | 46.7↑28.9 | 58.02↑30.56 |
| SD3.5-Large | 91.6↑36.5 | 70.3↑39.9 | 52.2↑29.9 | 39.5↑27.8 | 55.6↑37.8 | 61.84↑34.38 |
| State-of-the-Art Text-to-Image Models | ||||||
| FLUX.1-dev | 88.4 | 68.3 | 55.6 | 37.0 | 44.4 | 58.74 |
| Bagel + CoT | 92.9↑4.5 | 75.9↑7.6 | 55.6=0.0 | 50.6↑13.6 | 57.8↑13.4 | 66.56↑7.82 |
| Qwen-Image | 99.1↑10.7 | 85.6↑17.3 | 70.3↑14.7 | 60.2↑23.2 | 71.1↑26.7 | 77.26↑18.52 |
| Gemini 2.5 Flash Image | 99.0↑10.6 | 91.4↑23.1 | 70.1↑14.5 | 70.2↑33.2 | 86.7↑42.3 | 83.48↑24.74 |
| Collaborative AI Systems | ||||||
| SymbOmni | 95.0 | 83.6 | 74.8 | 68.8 | 64.5 | 77.34 |
| OmniHarness | 95.0=0.0 | 94.0↑10.4 | 94.0↑19.2 | 76.9↑8.1 | 89.0↑24.5 | 89.78↑12.44 |
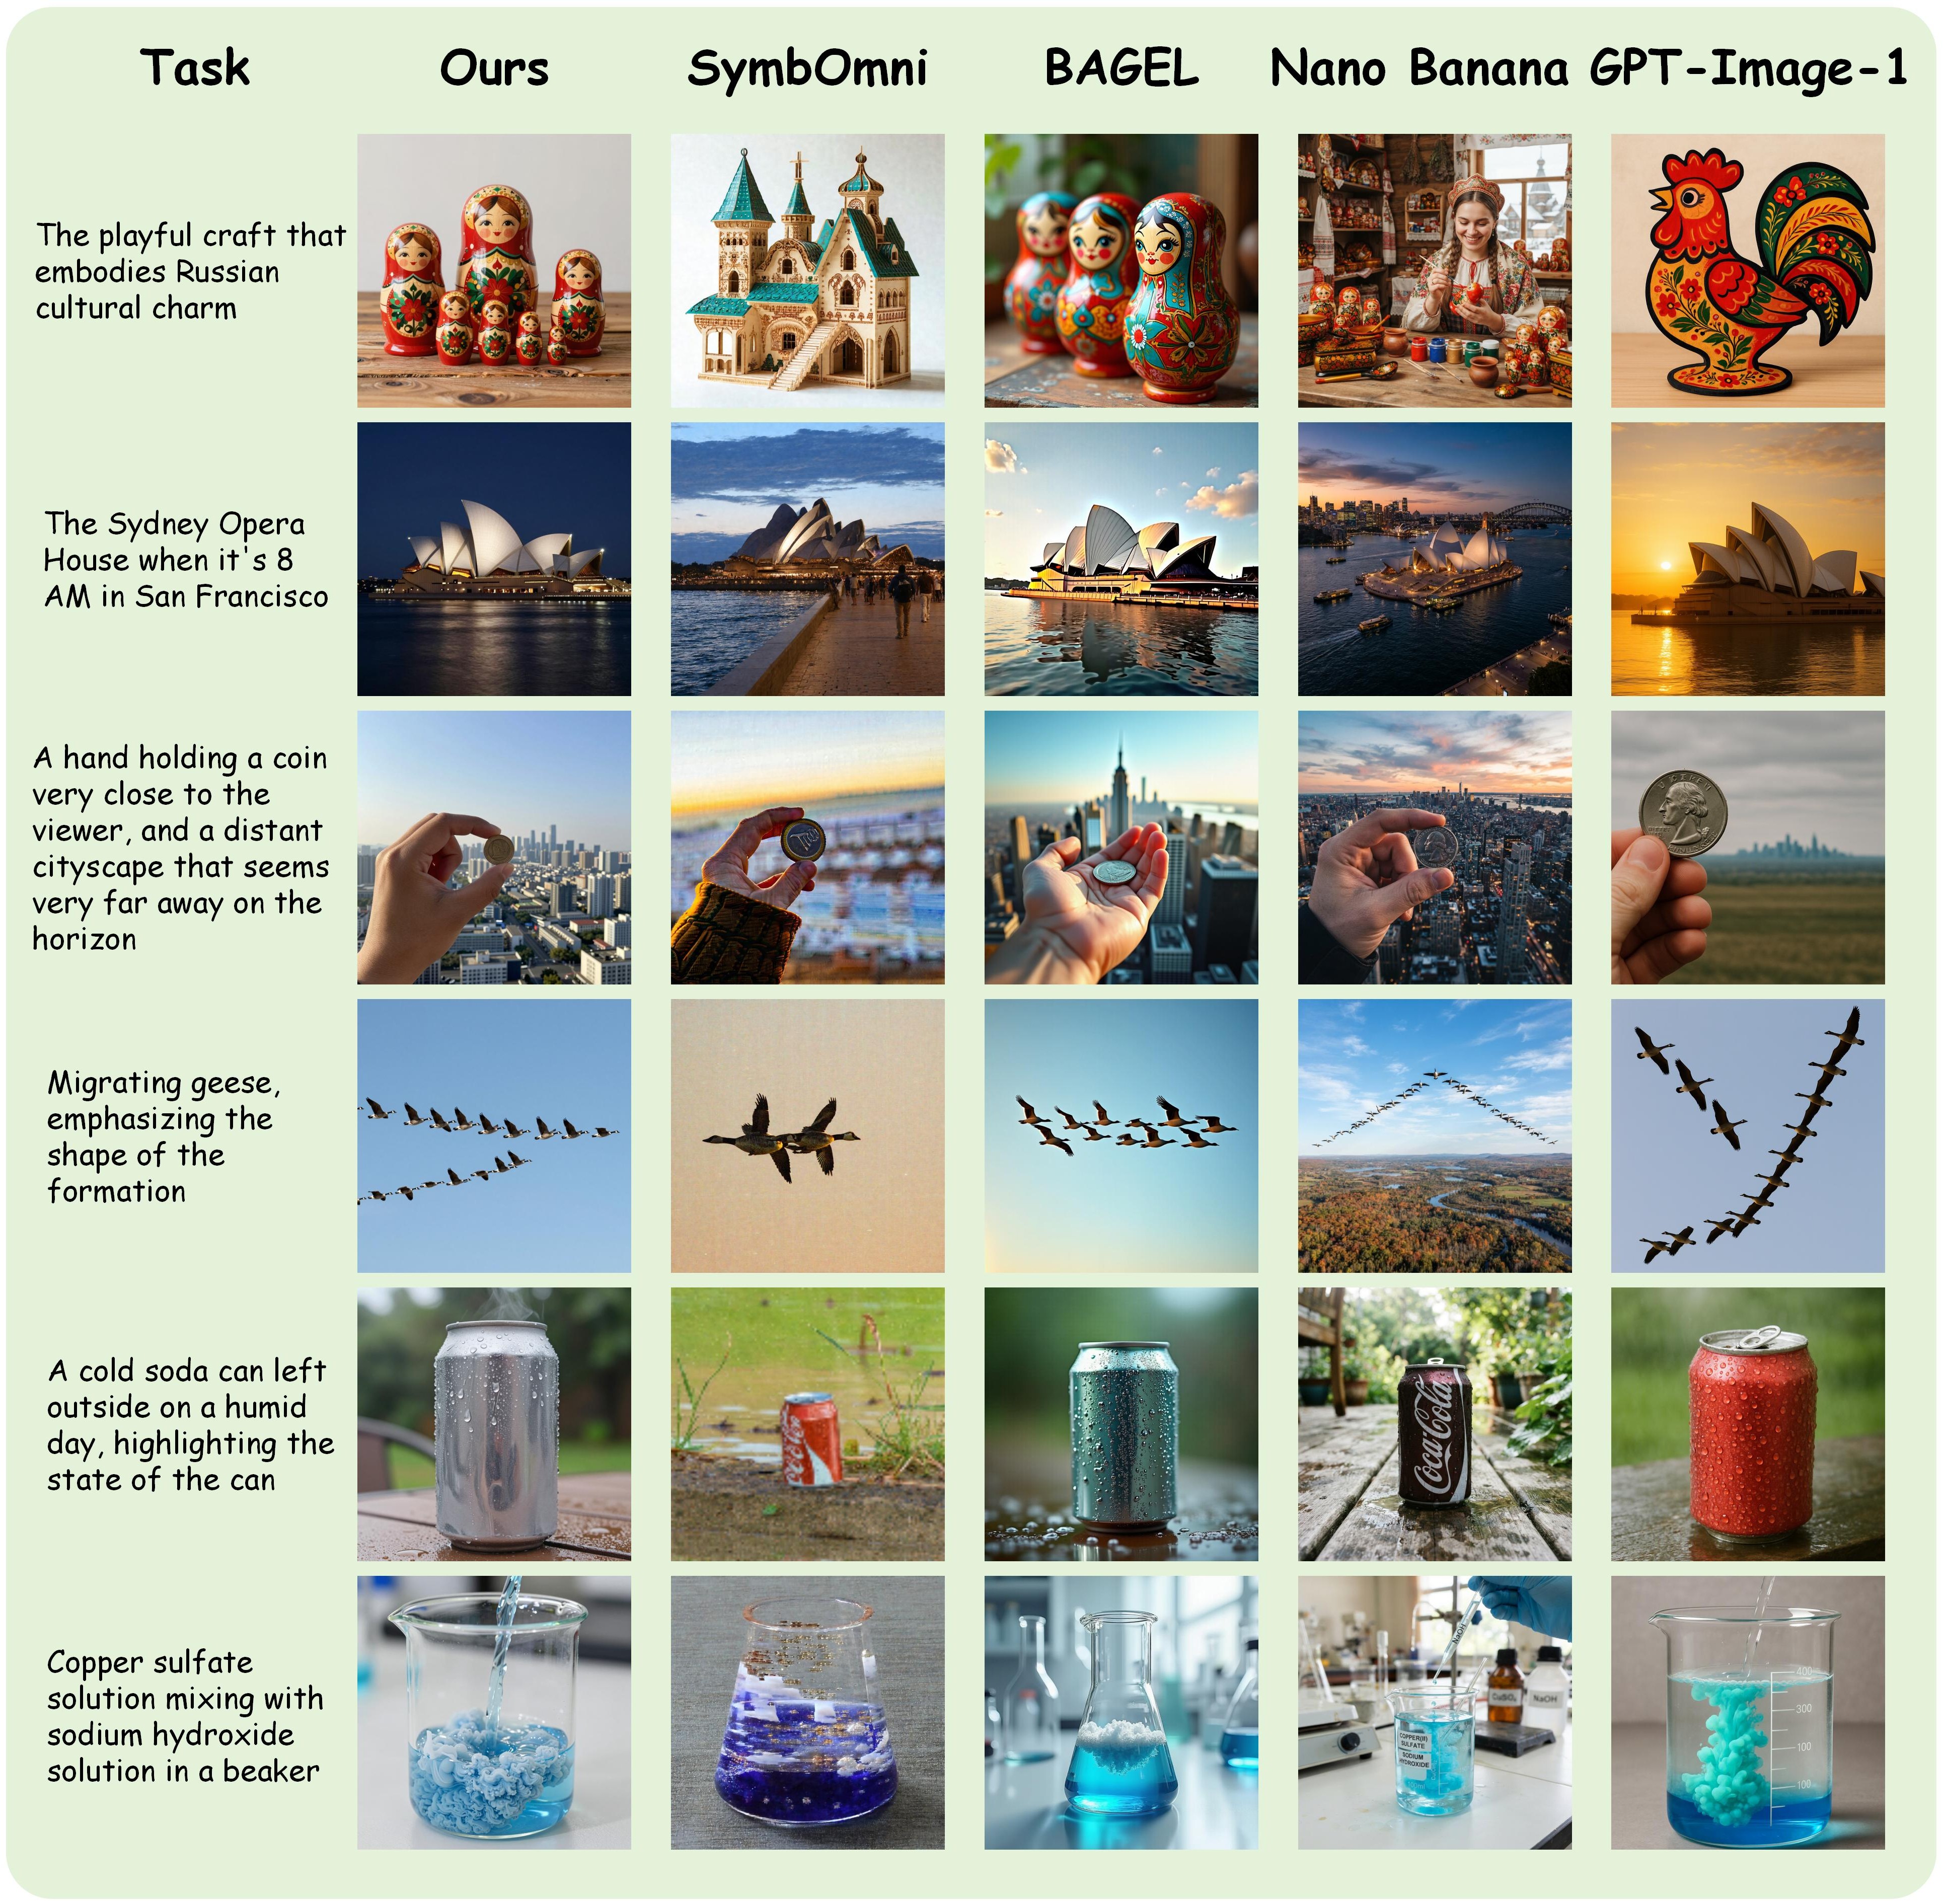
WISE evaluates world-knowledge-informed visual synthesis across cultural commonsense, temporal and spatial reasoning, biology, physics, and chemistry.
| Method | Cultural↑ | Time↑ | Space↑ | Biology↑ | Physics↑ | Chemistry↑ | Overall↑ |
|---|---|---|---|---|---|---|---|
| Dedicated T2I Models | |||||||
| SDv1.5 | 0.34 | 0.35 | 0.32 | 0.28 | 0.29 | 0.21 | 0.32 |
| SDv2.1 | 0.30↓0.04 | 0.38↑0.03 | 0.35↑0.03 | 0.33↑0.05 | 0.34↑0.05 | 0.21=0.00 | 0.32=0.00 |
| SD-XL | 0.43↑0.09 | 0.48↑0.13 | 0.47↑0.15 | 0.44↑0.16 | 0.45↑0.16 | 0.27↑0.06 | 0.43↑0.11 |
| SD3-Medium | 0.42↑0.08 | 0.44↑0.09 | 0.48↑0.16 | 0.39↑0.11 | 0.47↑0.18 | 0.29↑0.08 | 0.42↑0.10 |
| SD3.5-Medium | 0.43↑0.09 | 0.50↑0.15 | 0.52↑0.20 | 0.41↑0.13 | 0.53↑0.24 | 0.33↑0.12 | 0.45↑0.13 |
| SD3.5-Large | 0.44↑0.10 | 0.50↑0.15 | 0.58↑0.26 | 0.44↑0.16 | 0.52↑0.23 | 0.31↑0.10 | 0.46↑0.14 |
| PixArt-Alpha | 0.45↑0.11 | 0.50↑0.15 | 0.48↑0.16 | 0.49↑0.21 | 0.56↑0.27 | 0.34↑0.13 | 0.47↑0.15 |
| Playground-v2.5 | 0.49↑0.15 | 0.58↑0.23 | 0.55↑0.23 | 0.43↑0.15 | 0.48↑0.19 | 0.33↑0.12 | 0.49↑0.17 |
| FLUX.1-schnell | 0.39↑0.05 | 0.44↑0.09 | 0.50↑0.18 | 0.31↑0.03 | 0.44↑0.15 | 0.26↑0.05 | 0.40↑0.08 |
| FLUX.1-dev | 0.48↑0.14 | 0.58↑0.23 | 0.62↑0.30 | 0.42↑0.14 | 0.51↑0.22 | 0.35↑0.14 | 0.50↑0.18 |
| Unified MLLM Models | |||||||
| Janus-1.3B | 0.16 | 0.26 | 0.35 | 0.28 | 0.30 | 0.14 | 0.23 |
| JanusFlow-1.3B | 0.13↓0.03 | 0.26=0.00 | 0.28↓0.07 | 0.20↓0.08 | 0.19↓0.11 | 0.11↓0.03 | 0.18↓0.05 |
| Janus-Pro-1B | 0.20↑0.04 | 0.28↑0.02 | 0.45↑0.10 | 0.24↓0.04 | 0.32↑0.02 | 0.16↑0.02 | 0.26↑0.03 |
| Janus-Pro-7B | 0.30↑0.14 | 0.37↑0.11 | 0.49↑0.14 | 0.36↑0.08 | 0.42↑0.12 | 0.26↑0.12 | 0.35↑0.12 |
| Show-o | 0.28↑0.12 | 0.36↑0.10 | 0.40↑0.05 | 0.23↓0.05 | 0.33↑0.03 | 0.22↑0.08 | 0.30↑0.07 |
| Show-o-512 | 0.28↑0.12 | 0.40↑0.14 | 0.48↑0.13 | 0.30↑0.02 | 0.46↑0.16 | 0.30↑0.16 | 0.35↑0.12 |
| VILA-U-7B | 0.26↑0.10 | 0.33↑0.07 | 0.37↑0.02 | 0.35↑0.07 | 0.39↑0.09 | 0.23↑0.09 | 0.31↑0.08 |
| Orthus-7B-base | 0.07↓0.09 | 0.10↓0.16 | 0.12↓0.23 | 0.15↓0.13 | 0.15↓0.15 | 0.10↓0.04 | 0.10↓0.13 |
| Orthus-7B-instruct | 0.23↑0.07 | 0.31↑0.05 | 0.38↑0.03 | 0.28=0.00 | 0.31↑0.01 | 0.20↑0.06 | 0.27↑0.04 |
| Emu3 | 0.34↑0.18 | 0.45↑0.19 | 0.48↑0.13 | 0.41↑0.13 | 0.45↑0.15 | 0.27↑0.13 | 0.39↑0.16 |
| BAGEL | 0.44↑0.28 | 0.55↑0.29 | 0.68↑0.33 | 0.44↑0.16 | 0.60↑0.30 | 0.39↑0.25 | 0.52↑0.29 |
| BAGEL + CoT | 0.76↑0.60 | 0.69↑0.43 | 0.75↑0.40 | 0.65↑0.37 | 0.75↑0.45 | 0.58↑0.44 | 0.70↑0.47 |
| Closed-Source Models | |||||||
| GPT-Image-1 | 0.81 | 0.71 | 0.89 | 0.83 | 0.79 | 0.74 | 0.80 |
| Collaborative AI Systems | |||||||
| ComfyMind | 0.85 | 0.66 | 0.72 | 0.67 | 0.70 | 0.78 | 0.76 |
| SymbOmni | 0.90↑0.05 | 0.70↑0.04 | 0.74↑0.02 | 0.75↑0.08 | 0.74↑0.04 | 0.78=0.00 | 0.80↑0.04 |
| OmniHarness | 0.88↑0.03 | 0.85↑0.19 | 0.86↑0.14 | 0.84↑0.17 | 0.82↑0.12 | 0.86↑0.08 | 0.86↑0.10 |
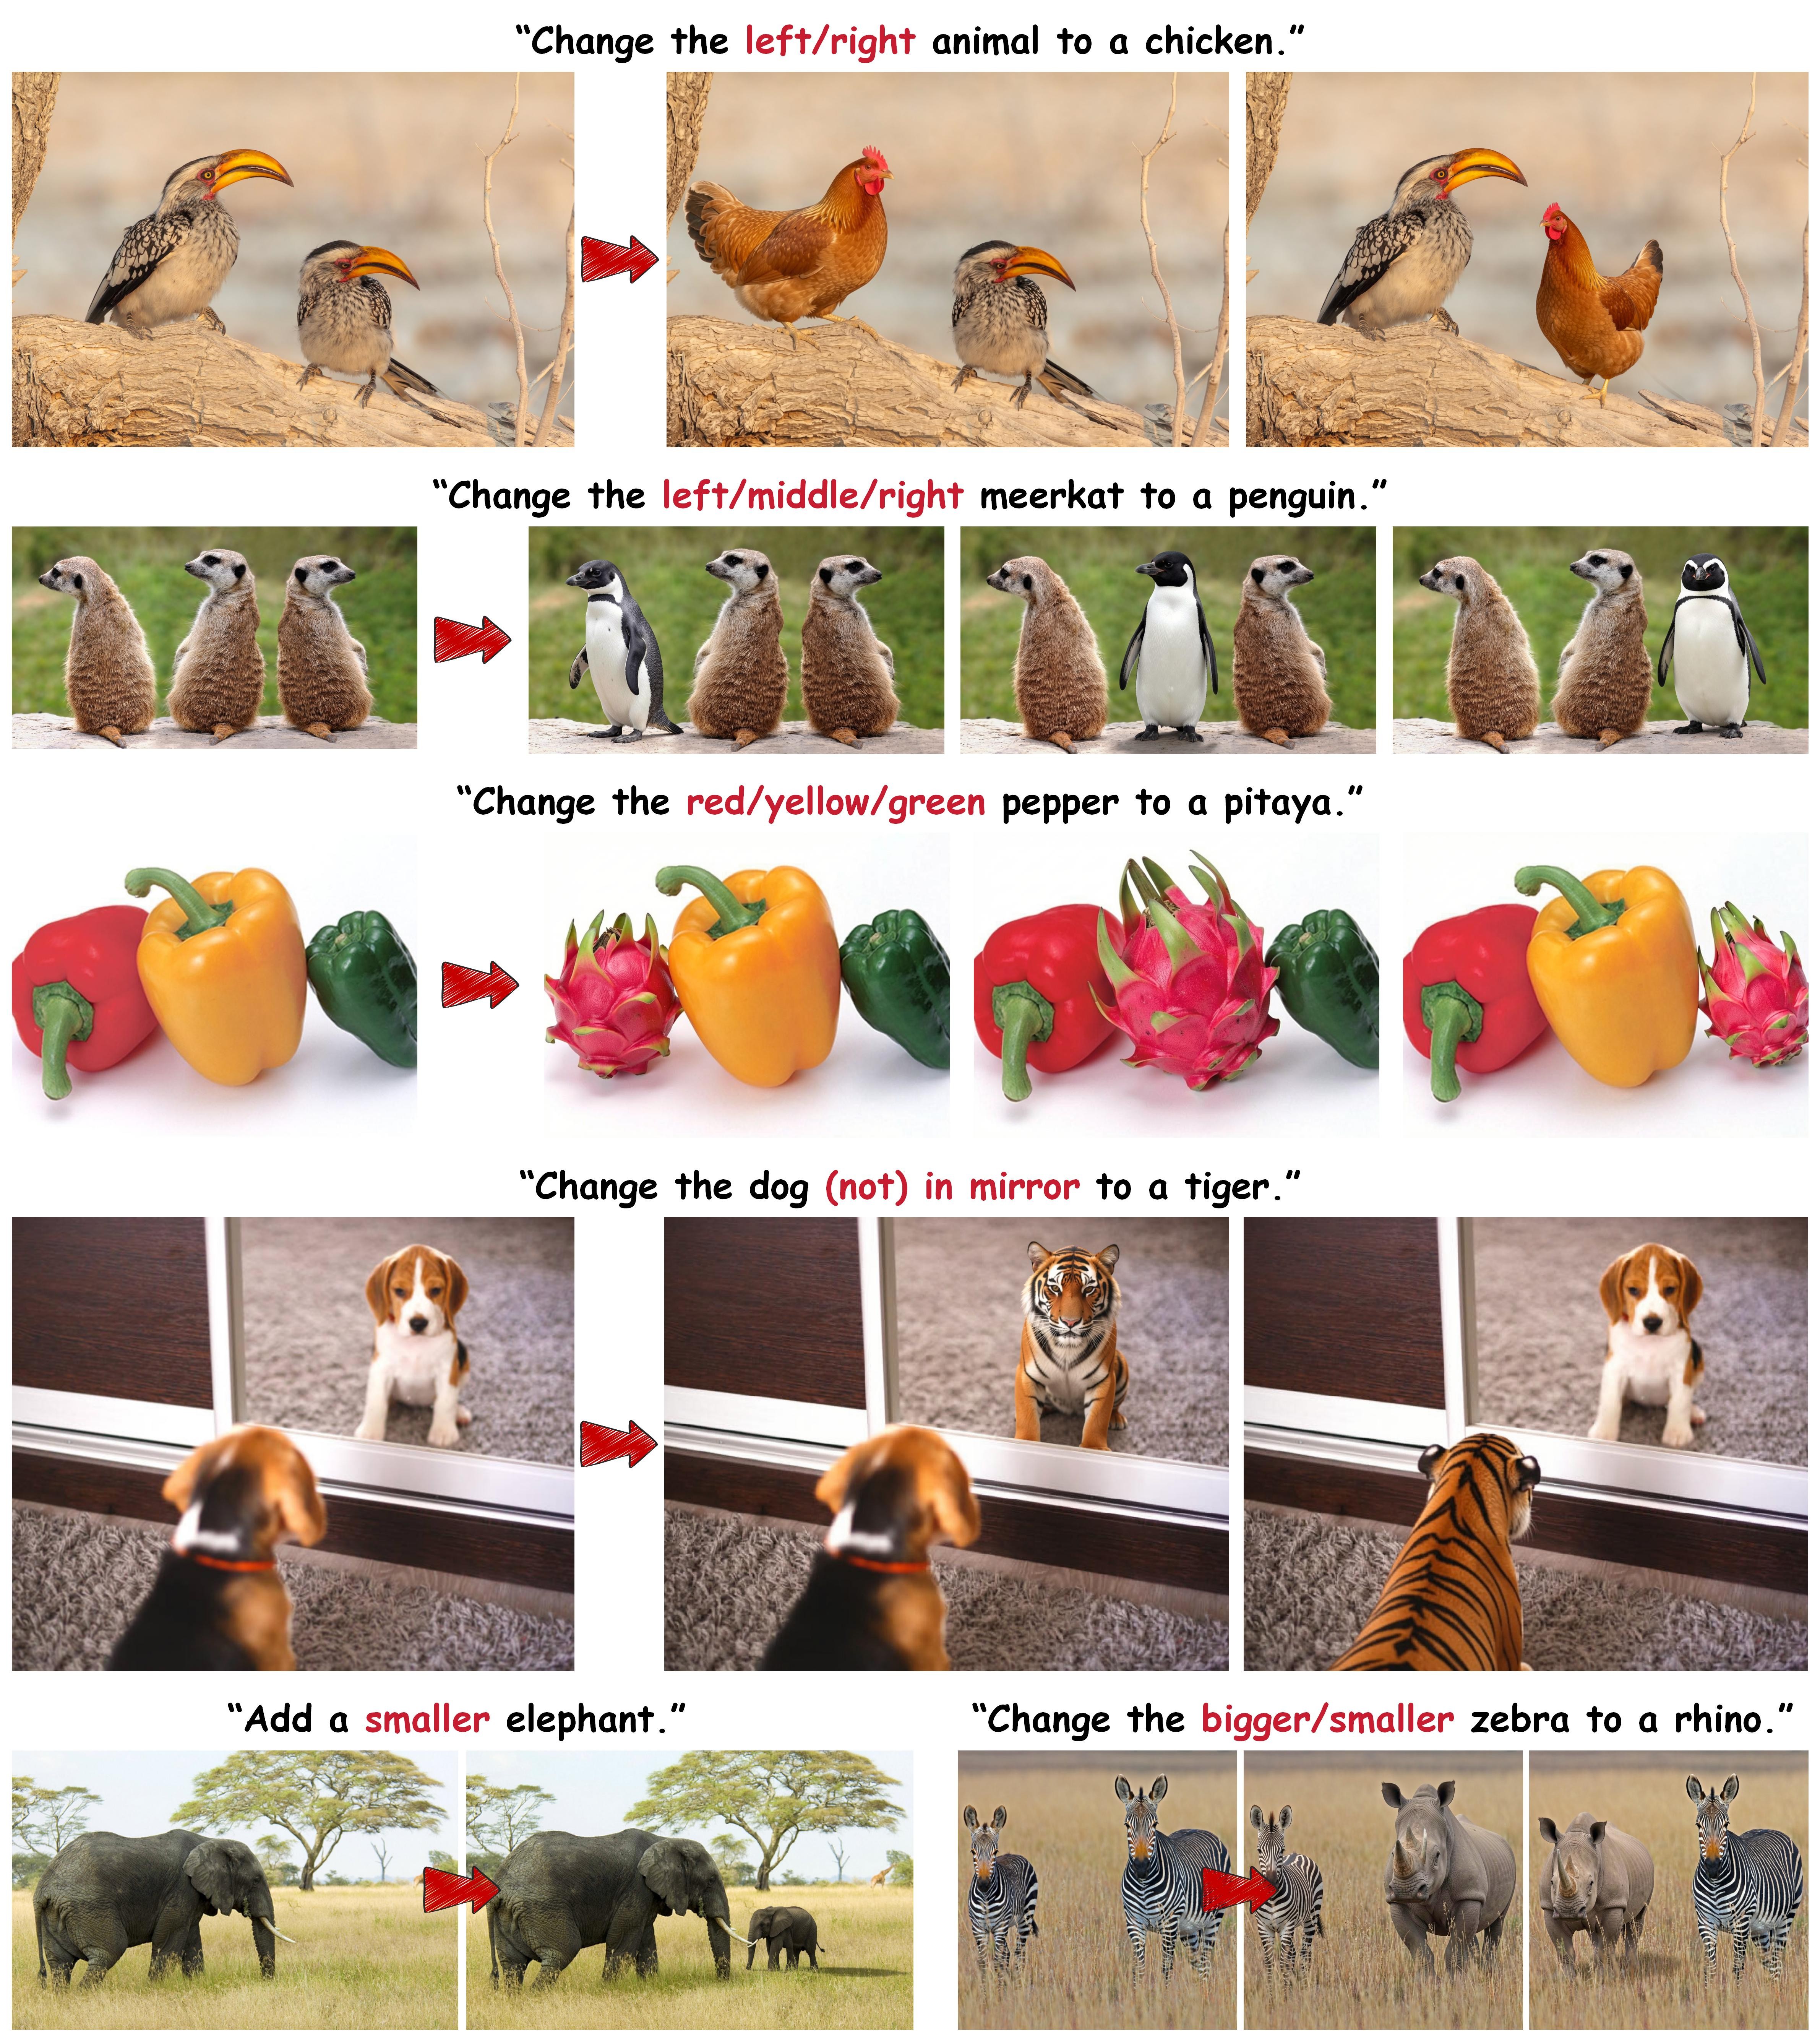
Reason-Edit evaluates instruction-based image editing through Understanding Scenarios with explicit target cues and Reasoning Scenarios with indirect commonsense descriptions, emphasizing accurate target localization and preservation of unrelated content.
| Method | Understanding Scenarios | Reasoning Scenarios | ||||||
|---|---|---|---|---|---|---|---|---|
| PSNR↑ | SSIM↑ | LPIPS↓ | CLIP↑ | PSNR↑ | SSIM↑ | LPIPS↓ | CLIP↑ | |
| InstructPix2Pix | 21.58 | 0.72 | 0.09 | 22.76 | 24.23 | 0.71 | 0.08 | 19.41 |
| MagicBrush | 18.12↓3.46 | 0.68↓0.04 | 0.14↑0.05 | 22.62↓0.14 | 22.10↓2.13 | 0.69↓0.01 | 0.11↑0.03 | 19.76↑0.34 |
| InstructDiffusion | 23.26↑1.68 | 0.74↑0.02 | 0.07↓0.02 | 23.08↑0.32 | 21.45↓2.78 | 0.67↓0.04 | 0.12↑0.03 | 19.52↑0.11 |
| SmartEdit-7B | 22.05↑0.47 | 0.73↑0.01 | 0.09≈0.00 | 23.61↑0.85 | 25.26↑1.02 | 0.74↑0.04 | 0.06↓0.03 | 20.95↑1.54 |
| SmartEdit-13B | 23.60↑2.02 | 0.75↑0.03 | 0.07↓0.02 | 23.54↑0.77 | 25.76↑1.52 | 0.75↑0.04 | 0.05↓0.03 | 20.78↑1.36 |
| InsightEdit | 23.59↑2.01 | 0.75↑0.03 | 0.07↓0.02 | 23.73↑0.97 | 25.71↑1.48 | 0.75↑0.04 | 0.05↓0.03 | 20.87↑1.45 |
| OmniHarness | 23.89↑2.32 | 0.86↑0.14 | 0.05↓0.04 | 24.55↑1.79 | 23.87↓0.36 | 0.80↑0.09 | 0.05↓0.03 | 21.32↑1.91 |
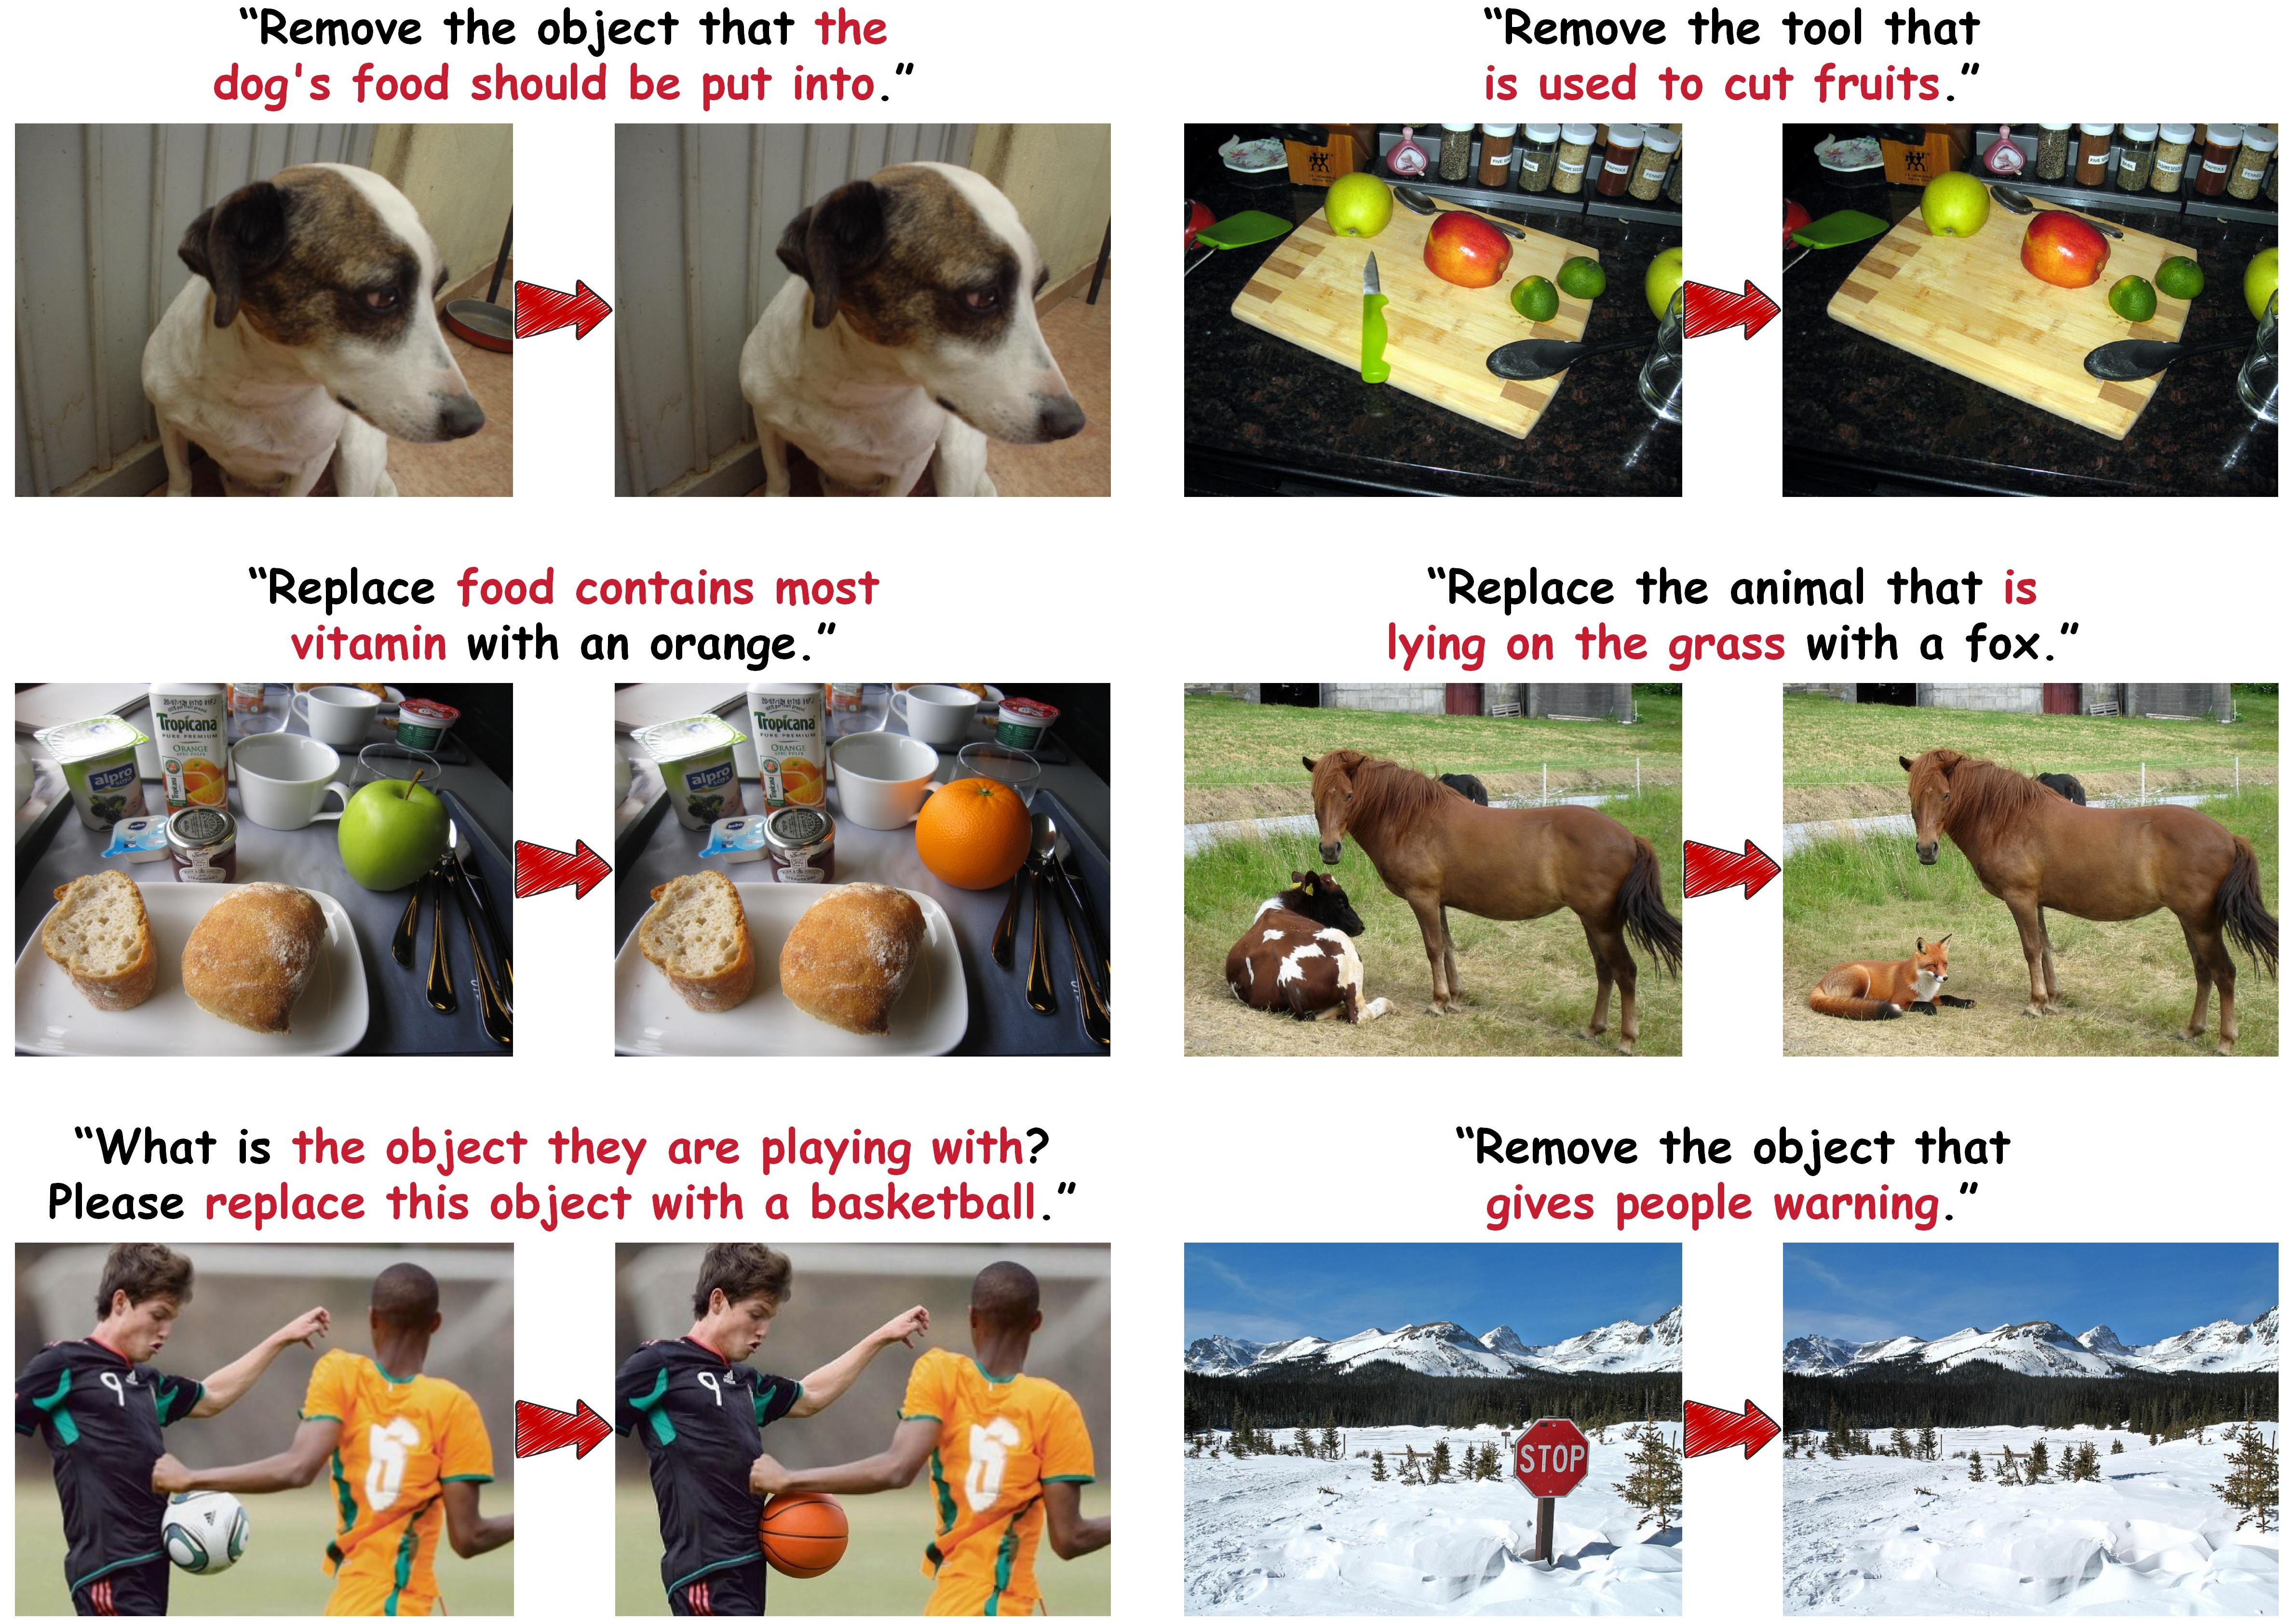
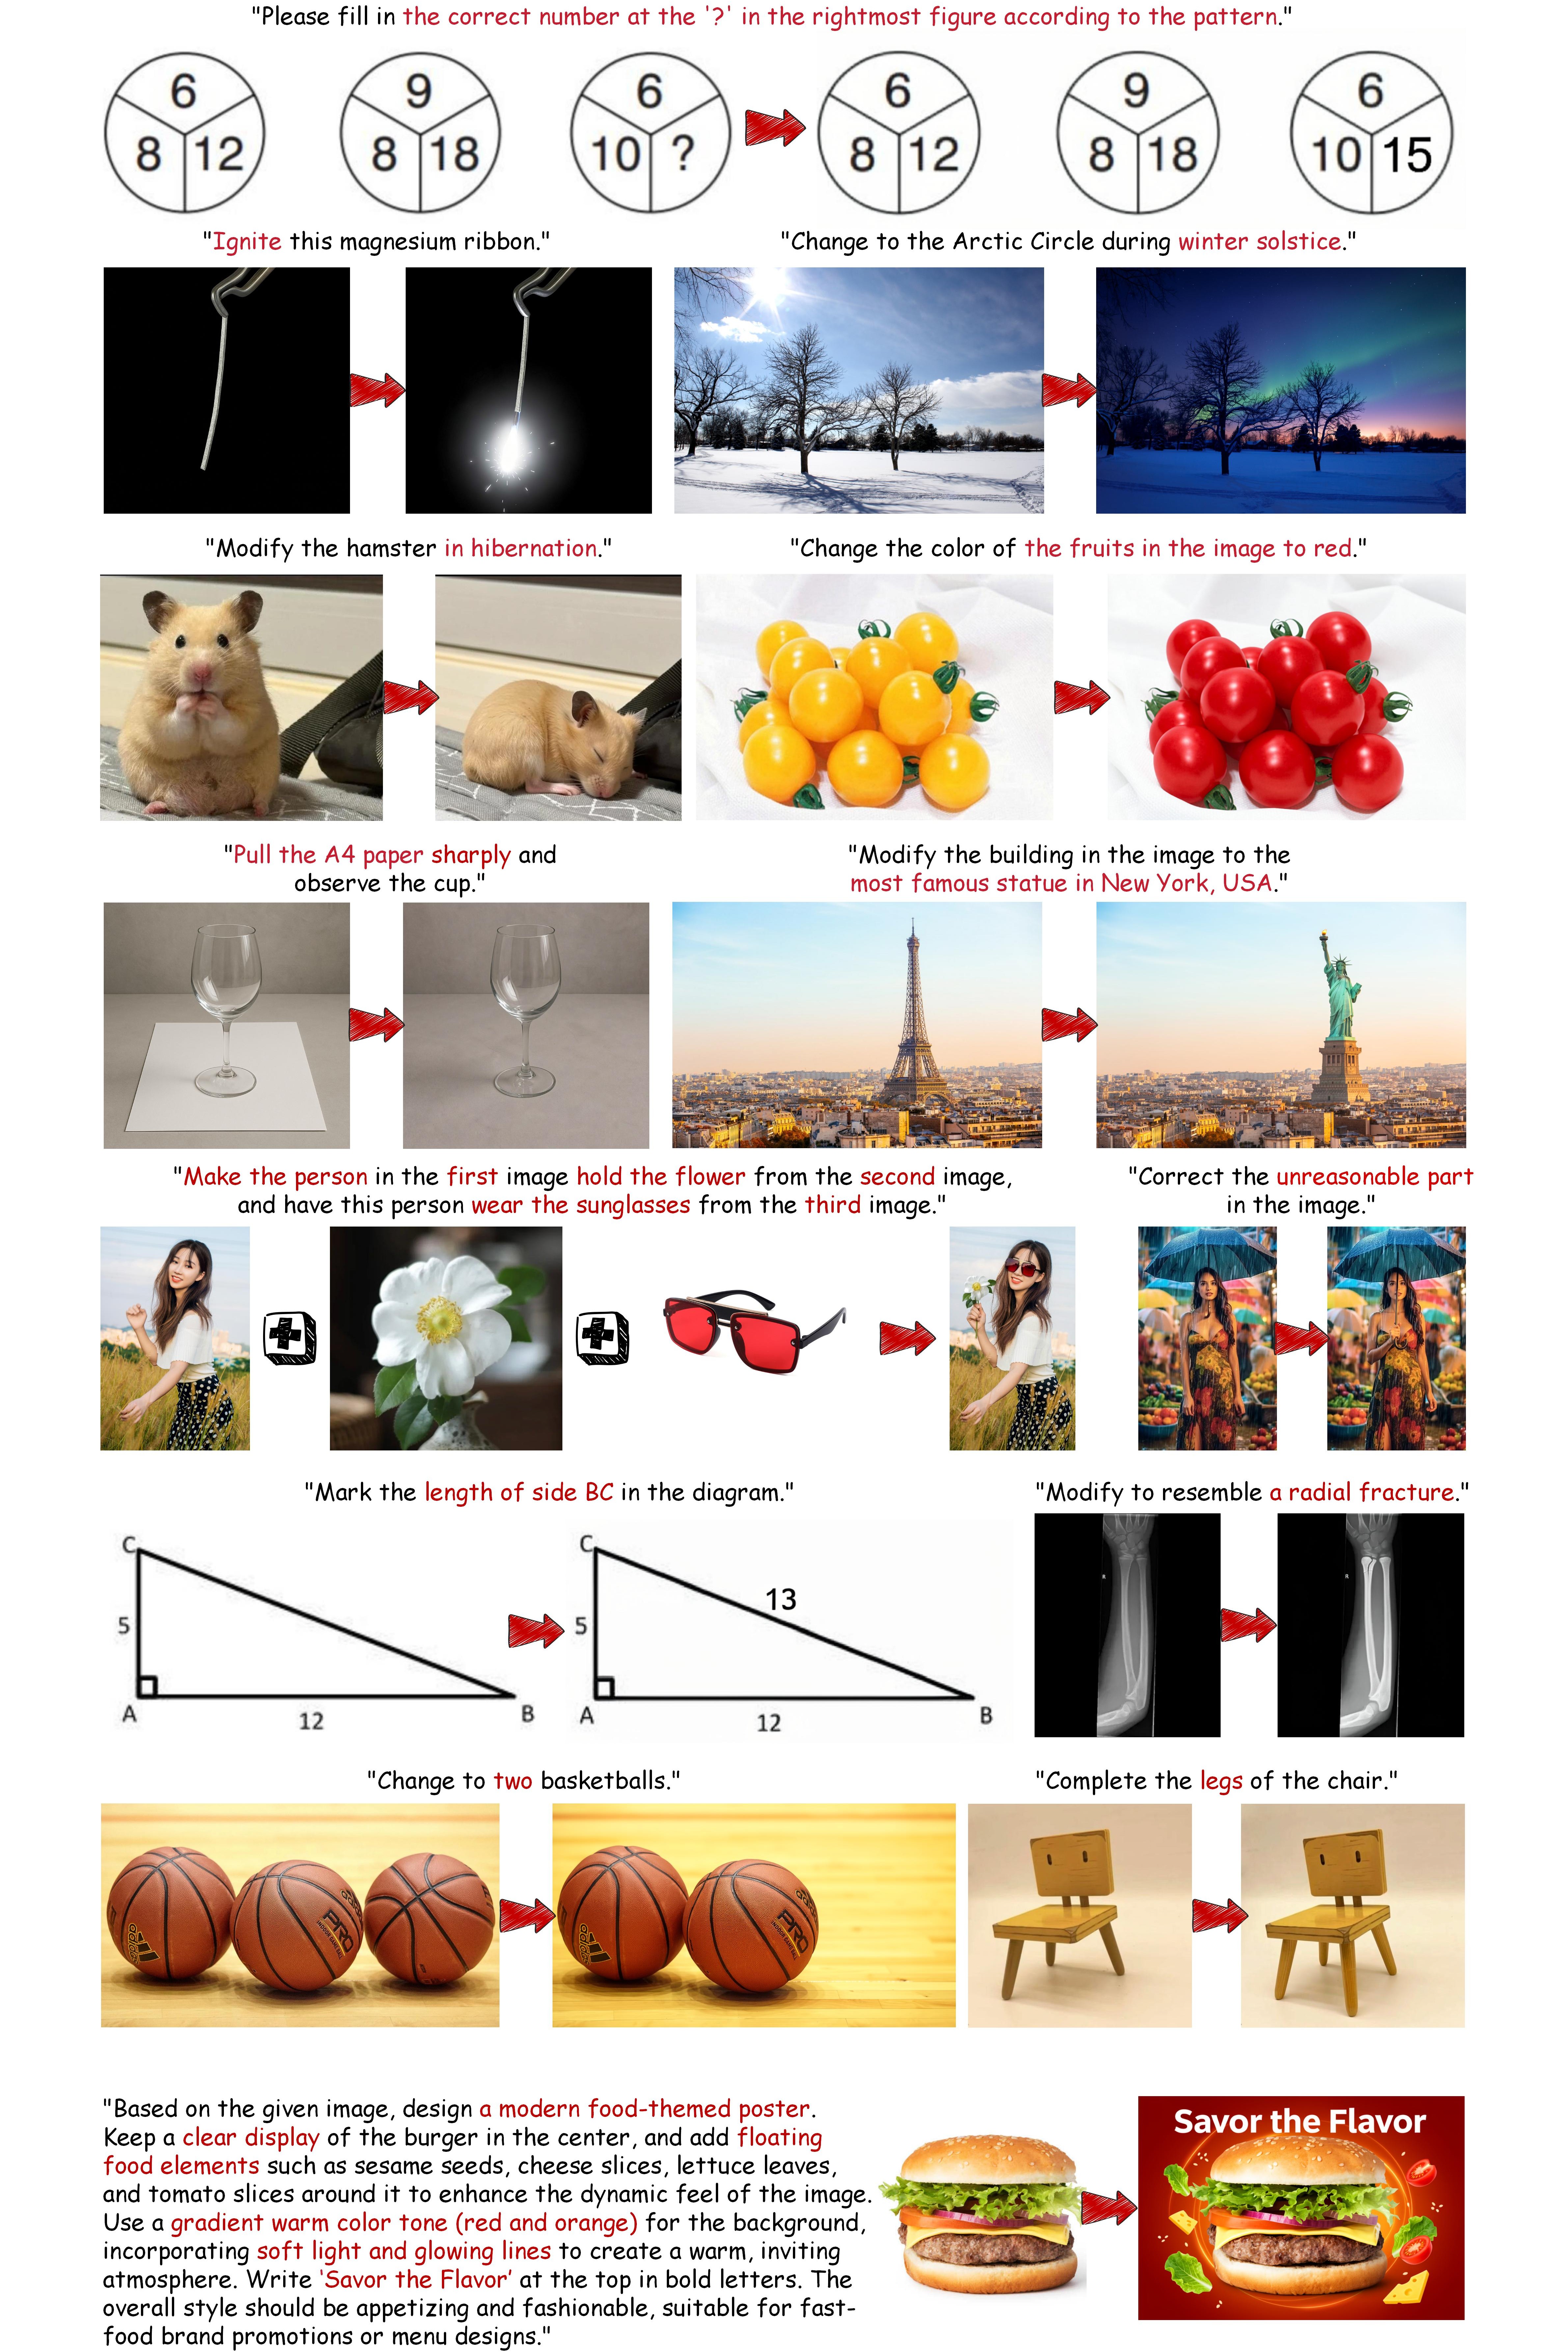
KRIS-Bench evaluates factual, conceptual, and procedural knowledge in knowledge-intensive visual generation and editing, spanning reasoning, transformation, and multi-image composition tasks.
| Method | Factual↑ | Conceptual↑ | Procedural↑ | Overall↑ |
|---|---|---|---|---|
| Closed-Source Models | ||||
| GPT-Image-1 | 79.80 | 81.37 | 78.32 | 80.09 |
| Gemini 2.0 Flash Experimental | 65.26↓14.54 | 59.65↓21.72 | 62.90↓15.42 | 62.41↓17.68 |
| Doubao | 63.30↓16.50 | 62.23↓19.14 | 54.17↓24.15 | 60.70↓19.39 |
| Open-Source Models | ||||
| BAGEL-Think | 55.77 | 59.44 | 39.26 | 53.36 |
| BAGEL | 47.71↓8.06 | 52.17↓7.27 | 40.23↑0.97 | 47.76↓5.60 |
| Step1X-Edit | 45.52↓10.25 | 48.01↓11.43 | 31.82↓7.44 | 43.29↓10.07 |
| Emu2 | 45.40↓10.37 | 37.54↓21.90 | 34.91↓4.35 | 39.70↓13.66 |
| AnyEdit | 39.26↓16.51 | 41.88↓17.56 | 31.74↓7.52 | 38.55↓14.81 |
| MagicBrush | 41.84↓13.93 | 39.24↓20.20 | 26.54↓12.72 | 37.15↓16.21 |
| OmniGen | 33.11↓22.66 | 28.02↓31.42 | 23.89↓15.37 | 28.85↓24.51 |
| InsPix2Pix | 23.33↓32.44 | 25.59↓33.85 | 17.28↓21.98 | 22.82↓30.54 |
| Collaborative AI Systems | ||||
| SymbOmni | 73.33 | 72.28 | 70.29 | 72.18 |
| OmniHarness | 74.81↑1.48 | 81.89↑9.61 | 73.22↑2.93 | 77.33↑5.15 |
@misc{xu2026omniharnessharnessinggeneralizablevisual,
  title={OmniHarness: Harnessing Generalizable Visual Generation via Symbolic Policy Learning},
  author={Xu Xu and Jinxiu Liu and Zhangbo Qiao and Jiaxing Lu and Xiangyu Zhang and Yubin Gu and Fangwei Ning and Yan Shi},
  year={2026},
  eprint={2609.16057},
  archivePrefix={arXiv},
  primaryClass={cs.LG},
  url={https://arxiv.org/abs/2609.16057},
}